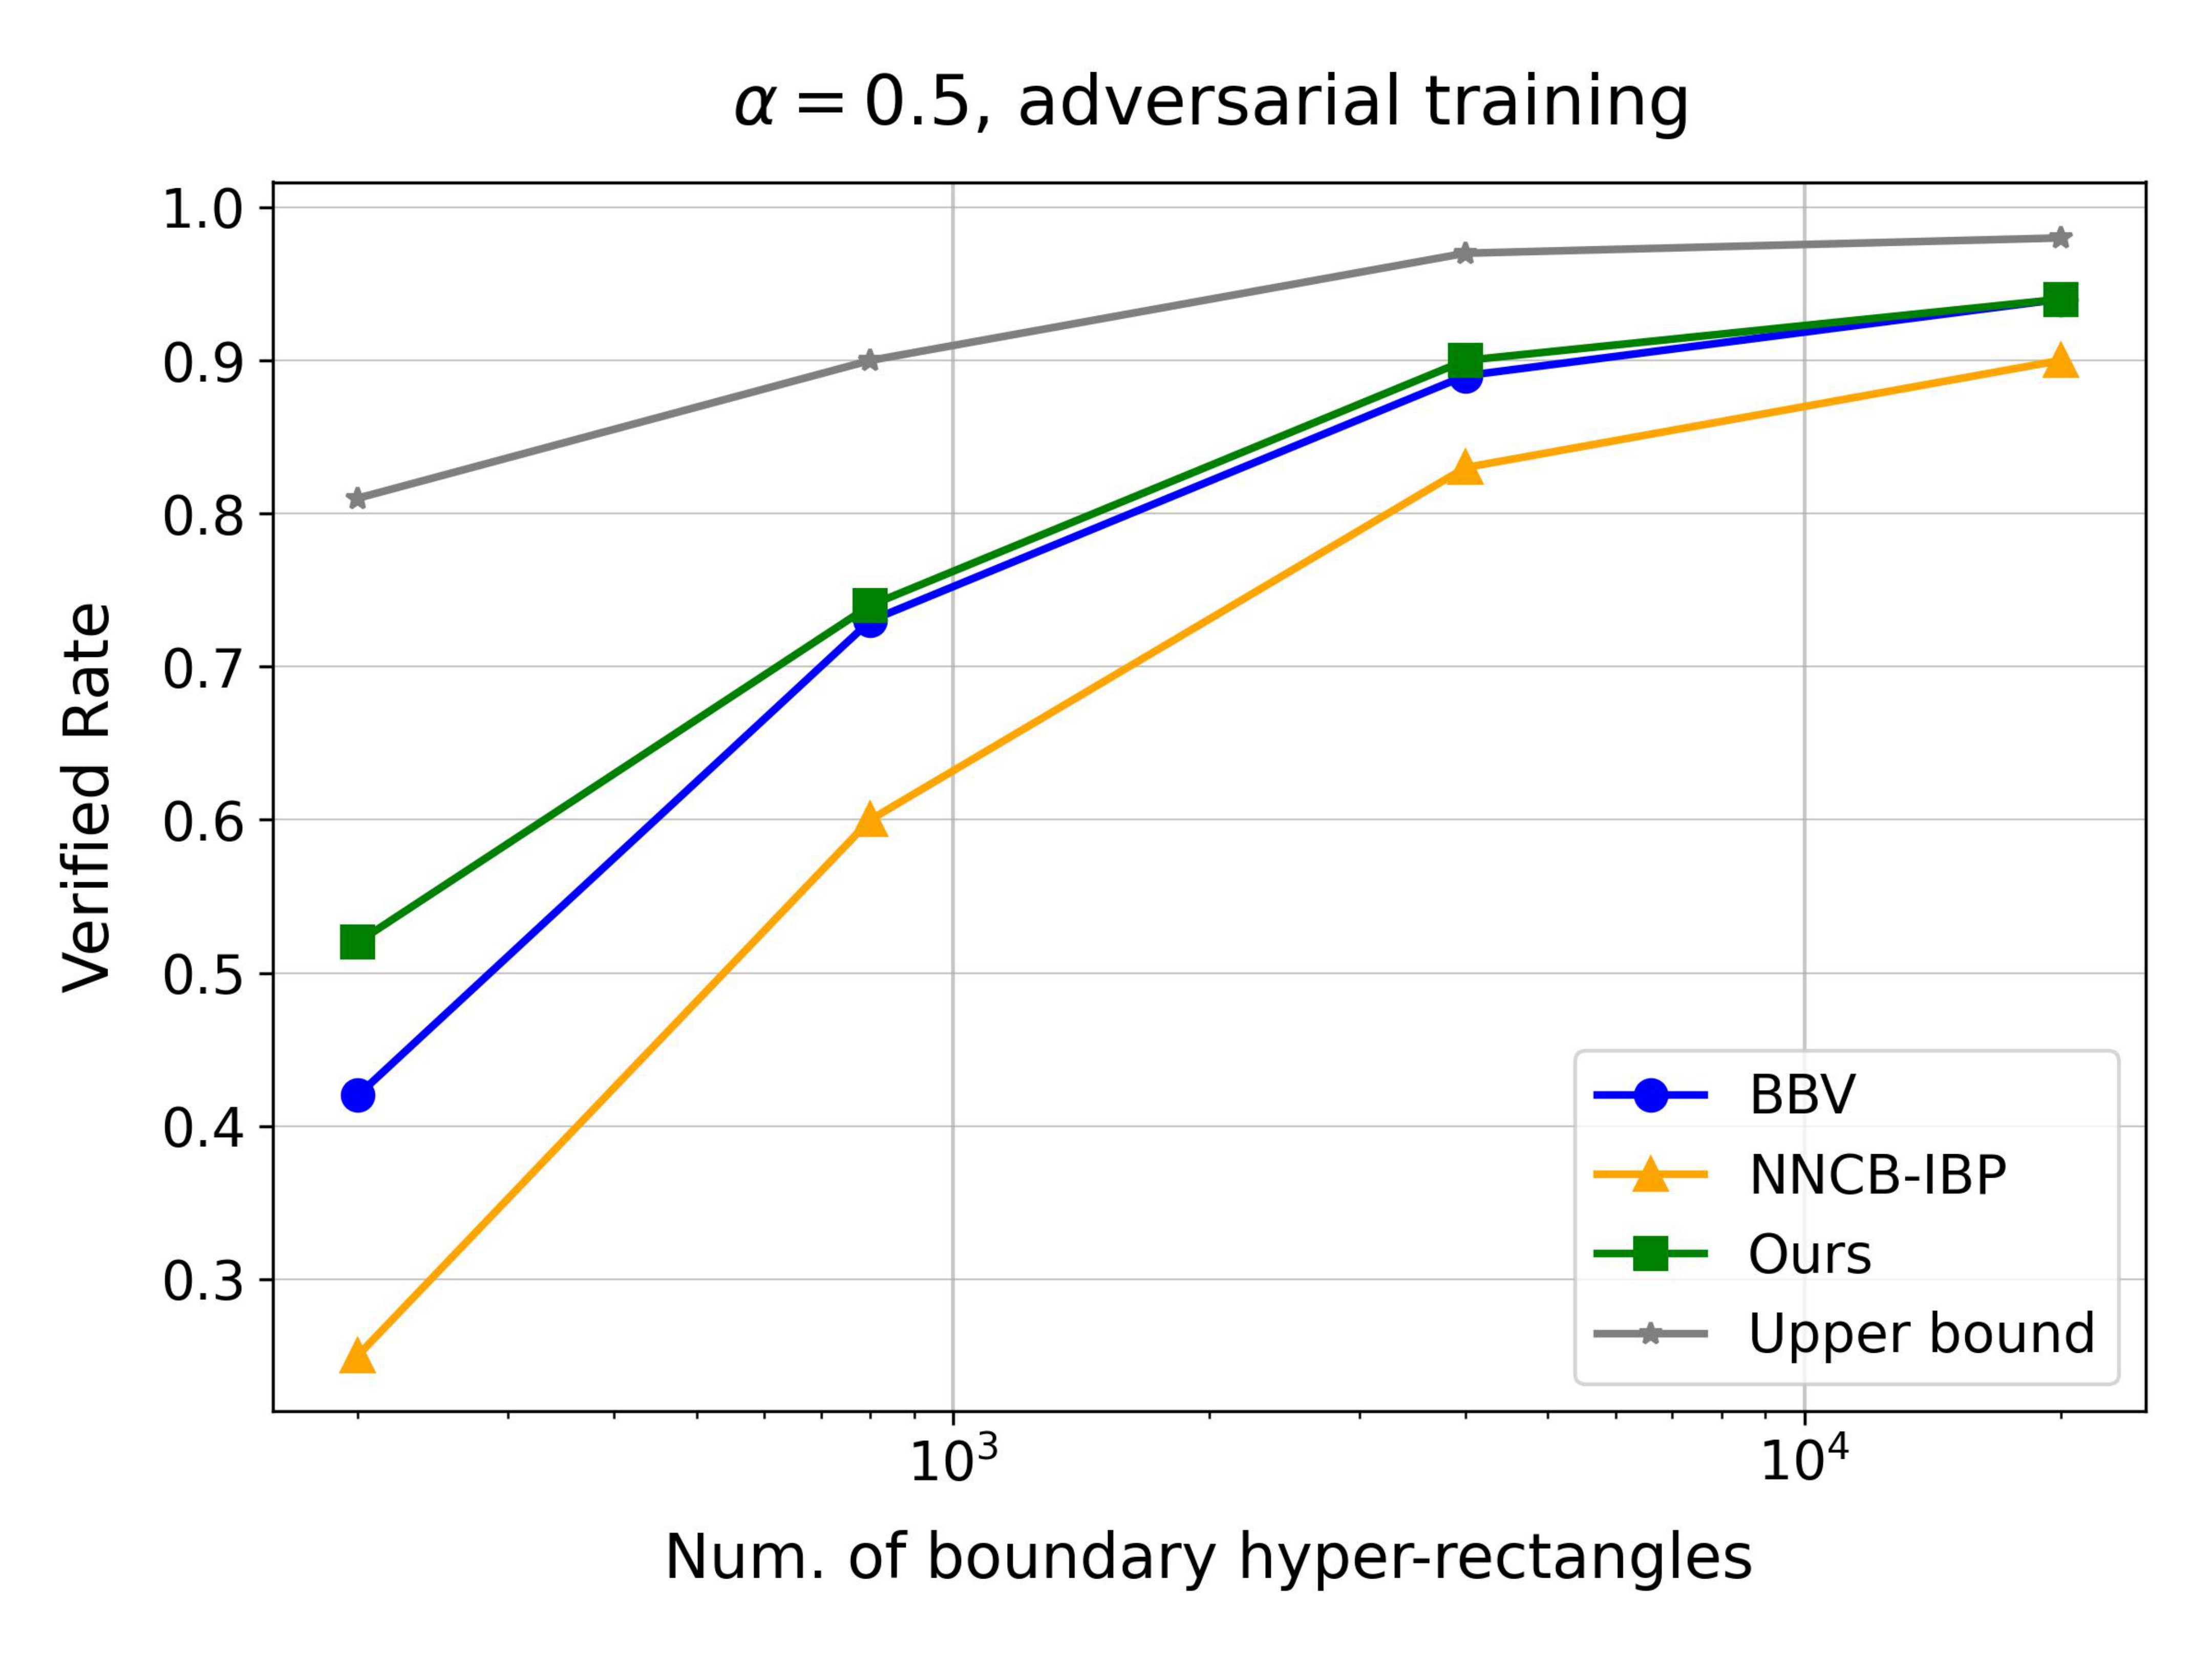
Existing chart-to-code systems increasingly rely on model-based
judgment signals, especially in agentic pipelines and RL-style
training. But chart evaluation is not the same as generic image
similarity: small changes in axes, legends, layout, or text can
make a chart unacceptable even when automatic scores remain high.
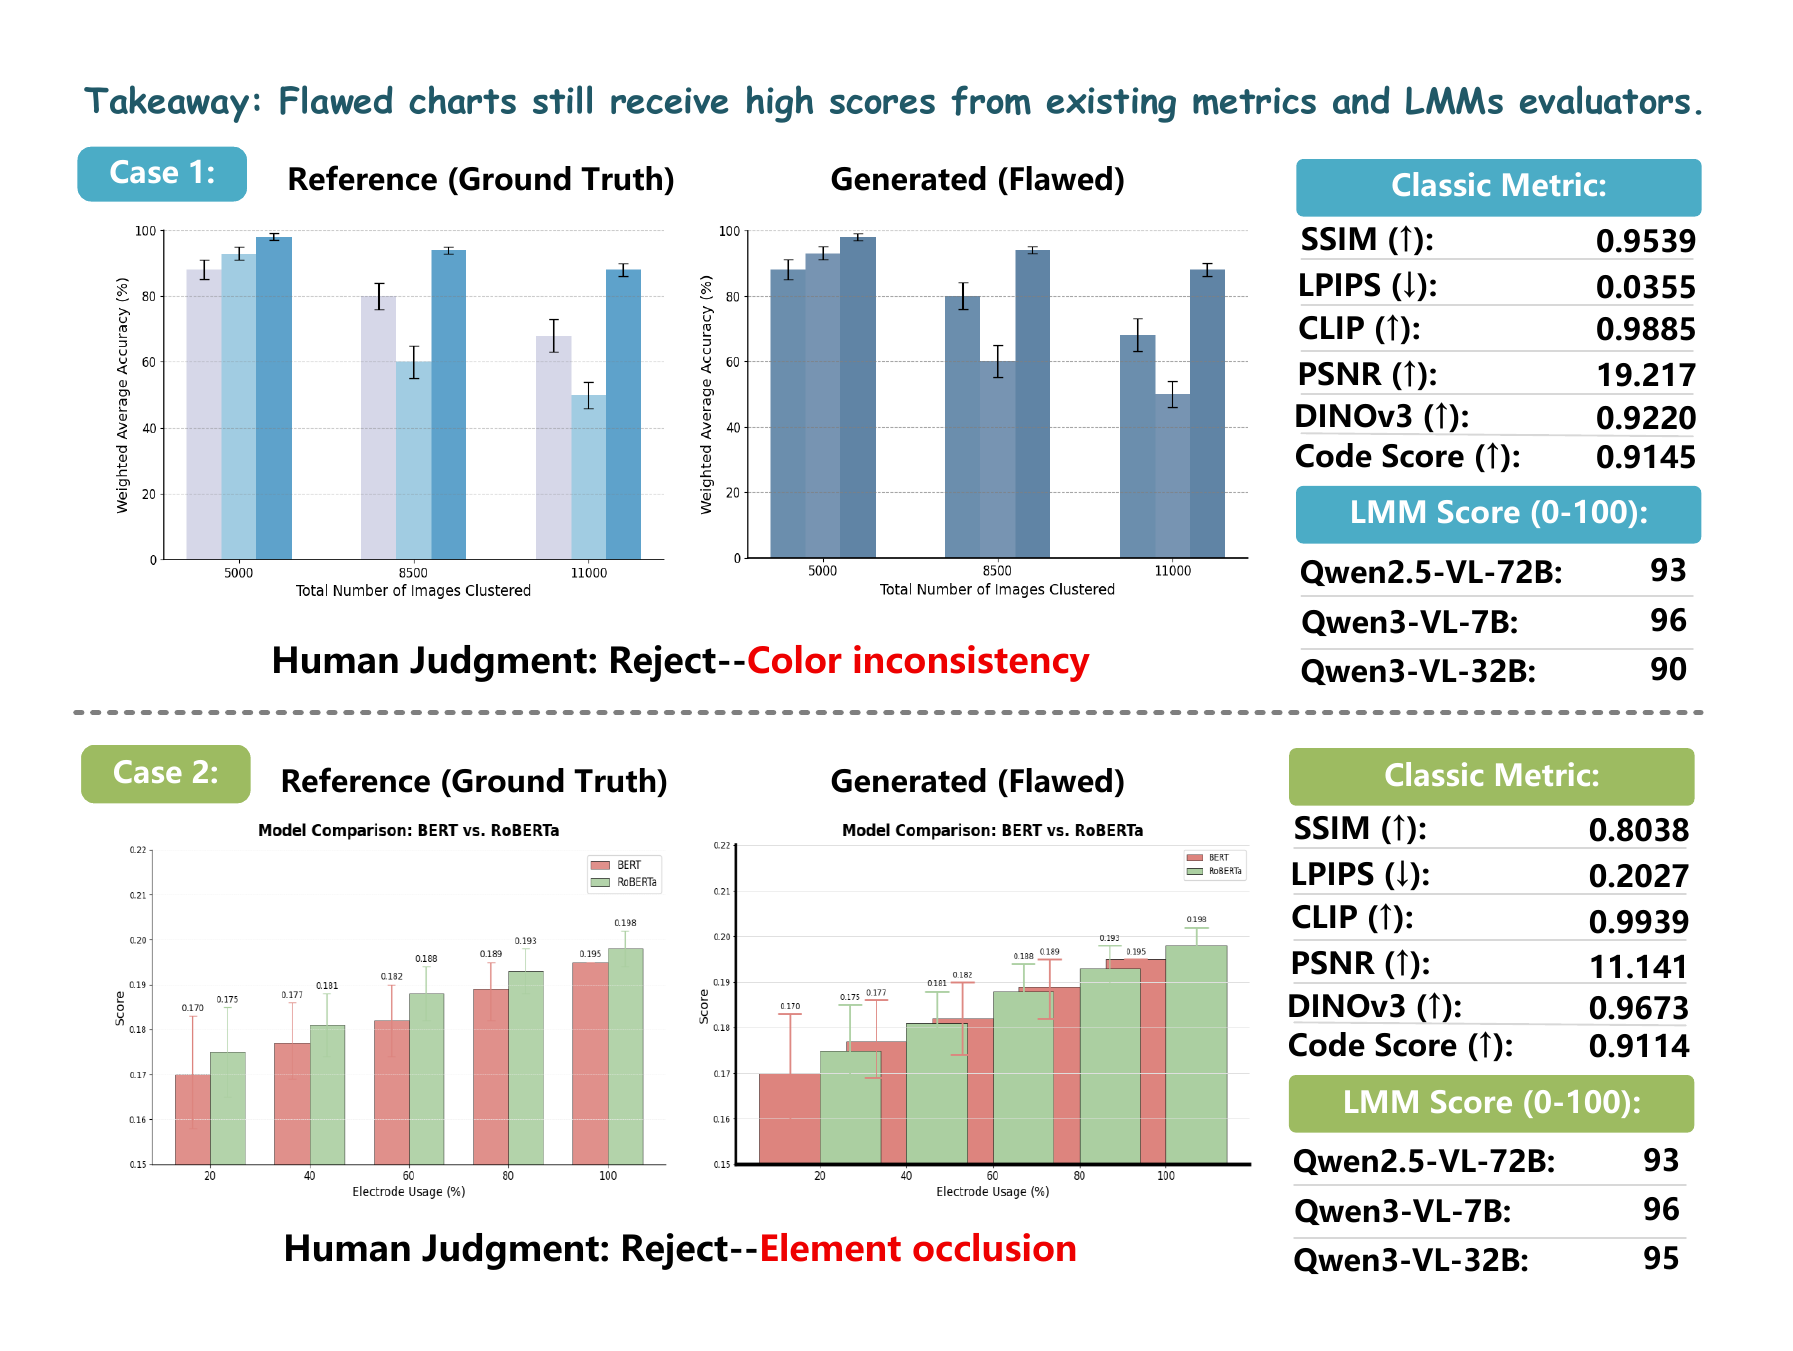
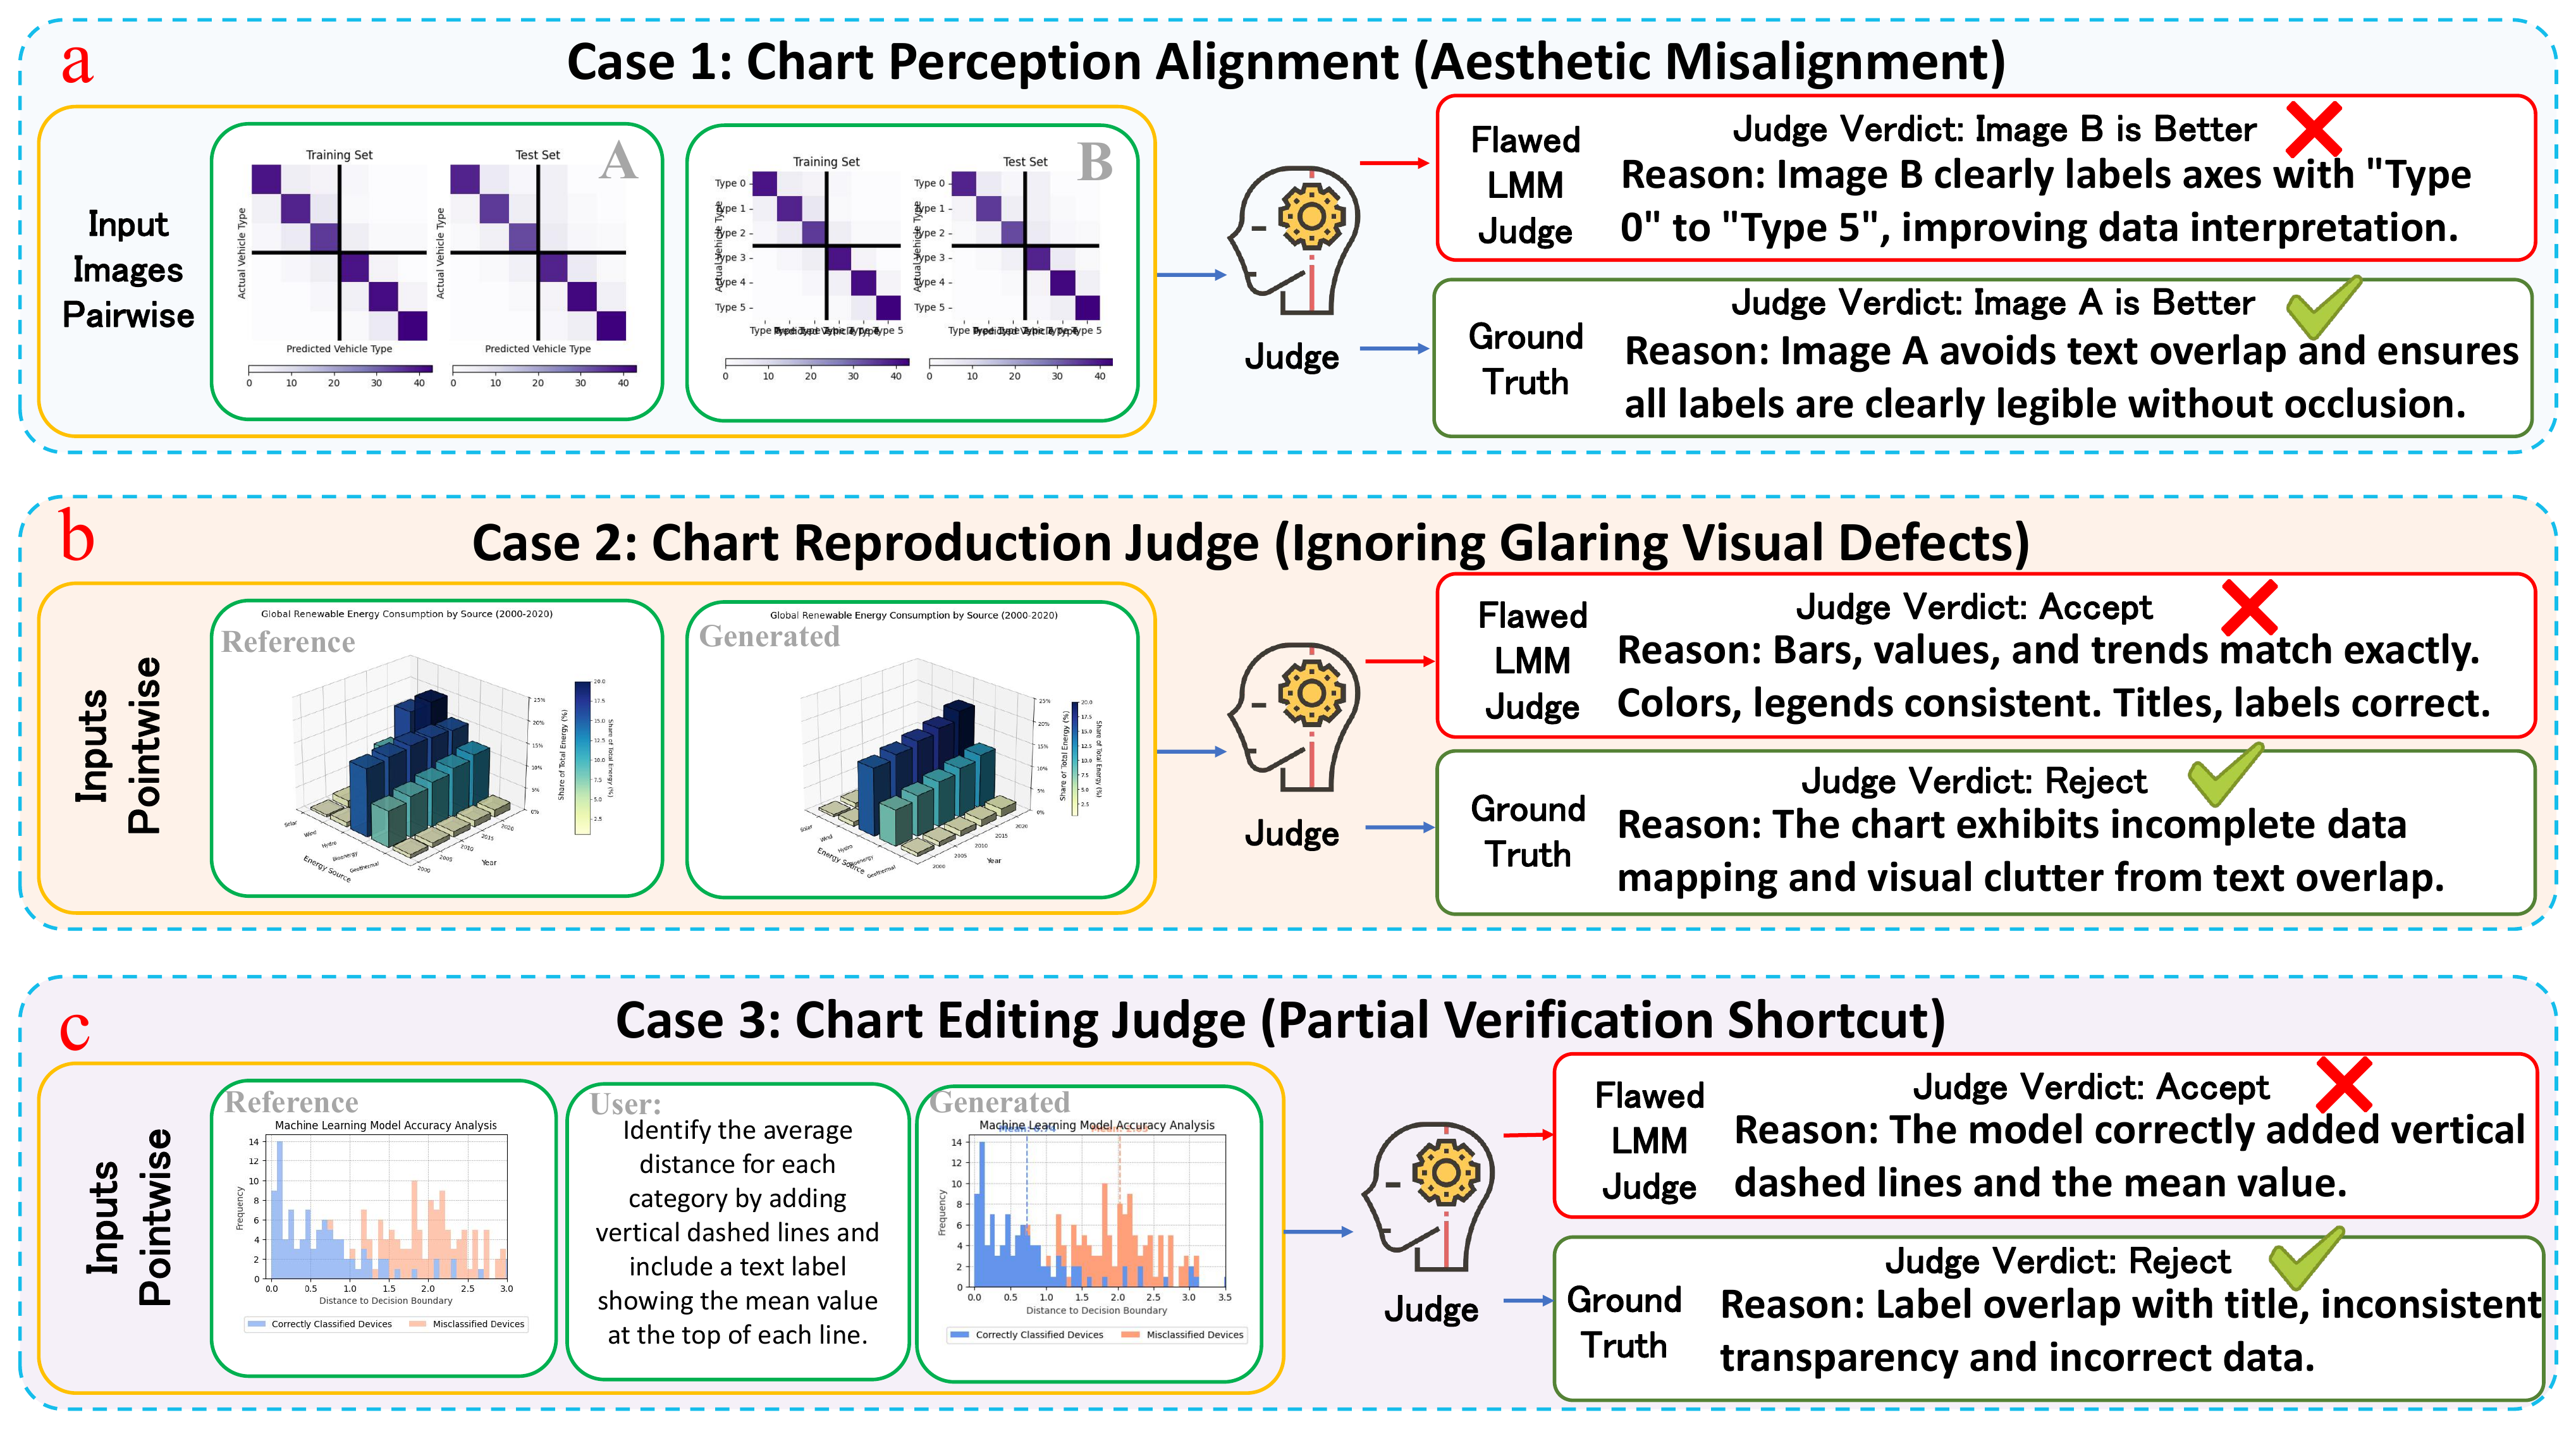
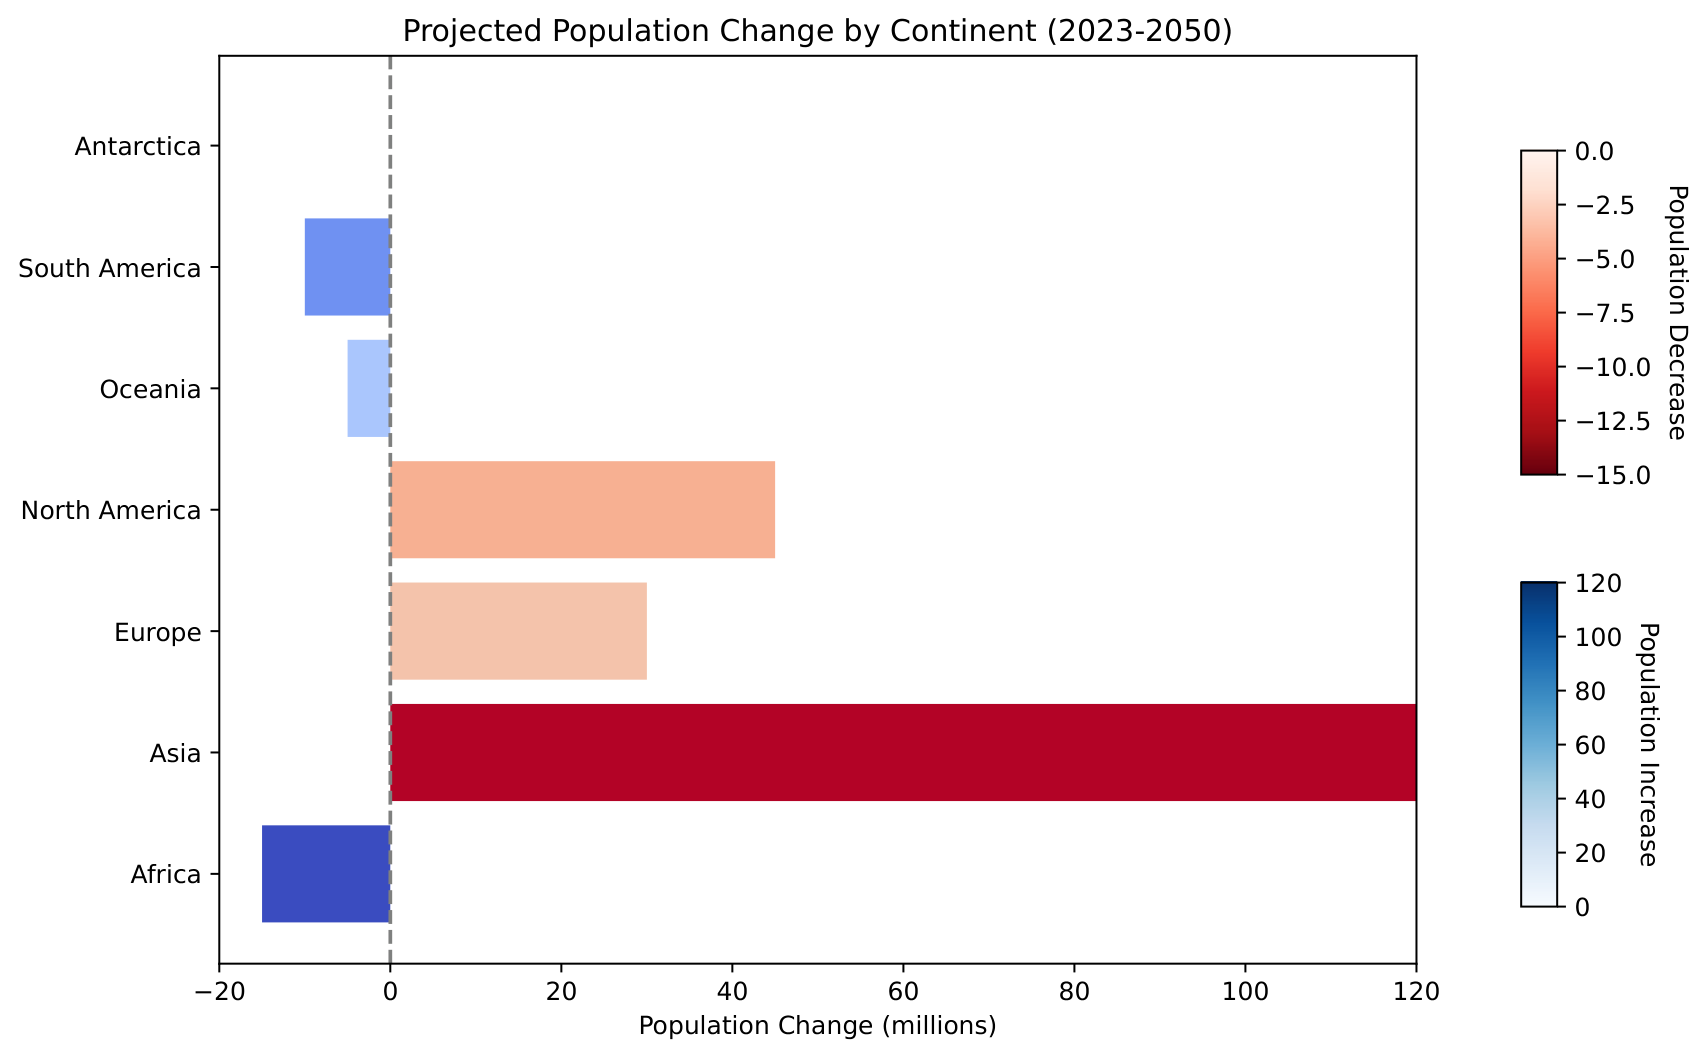
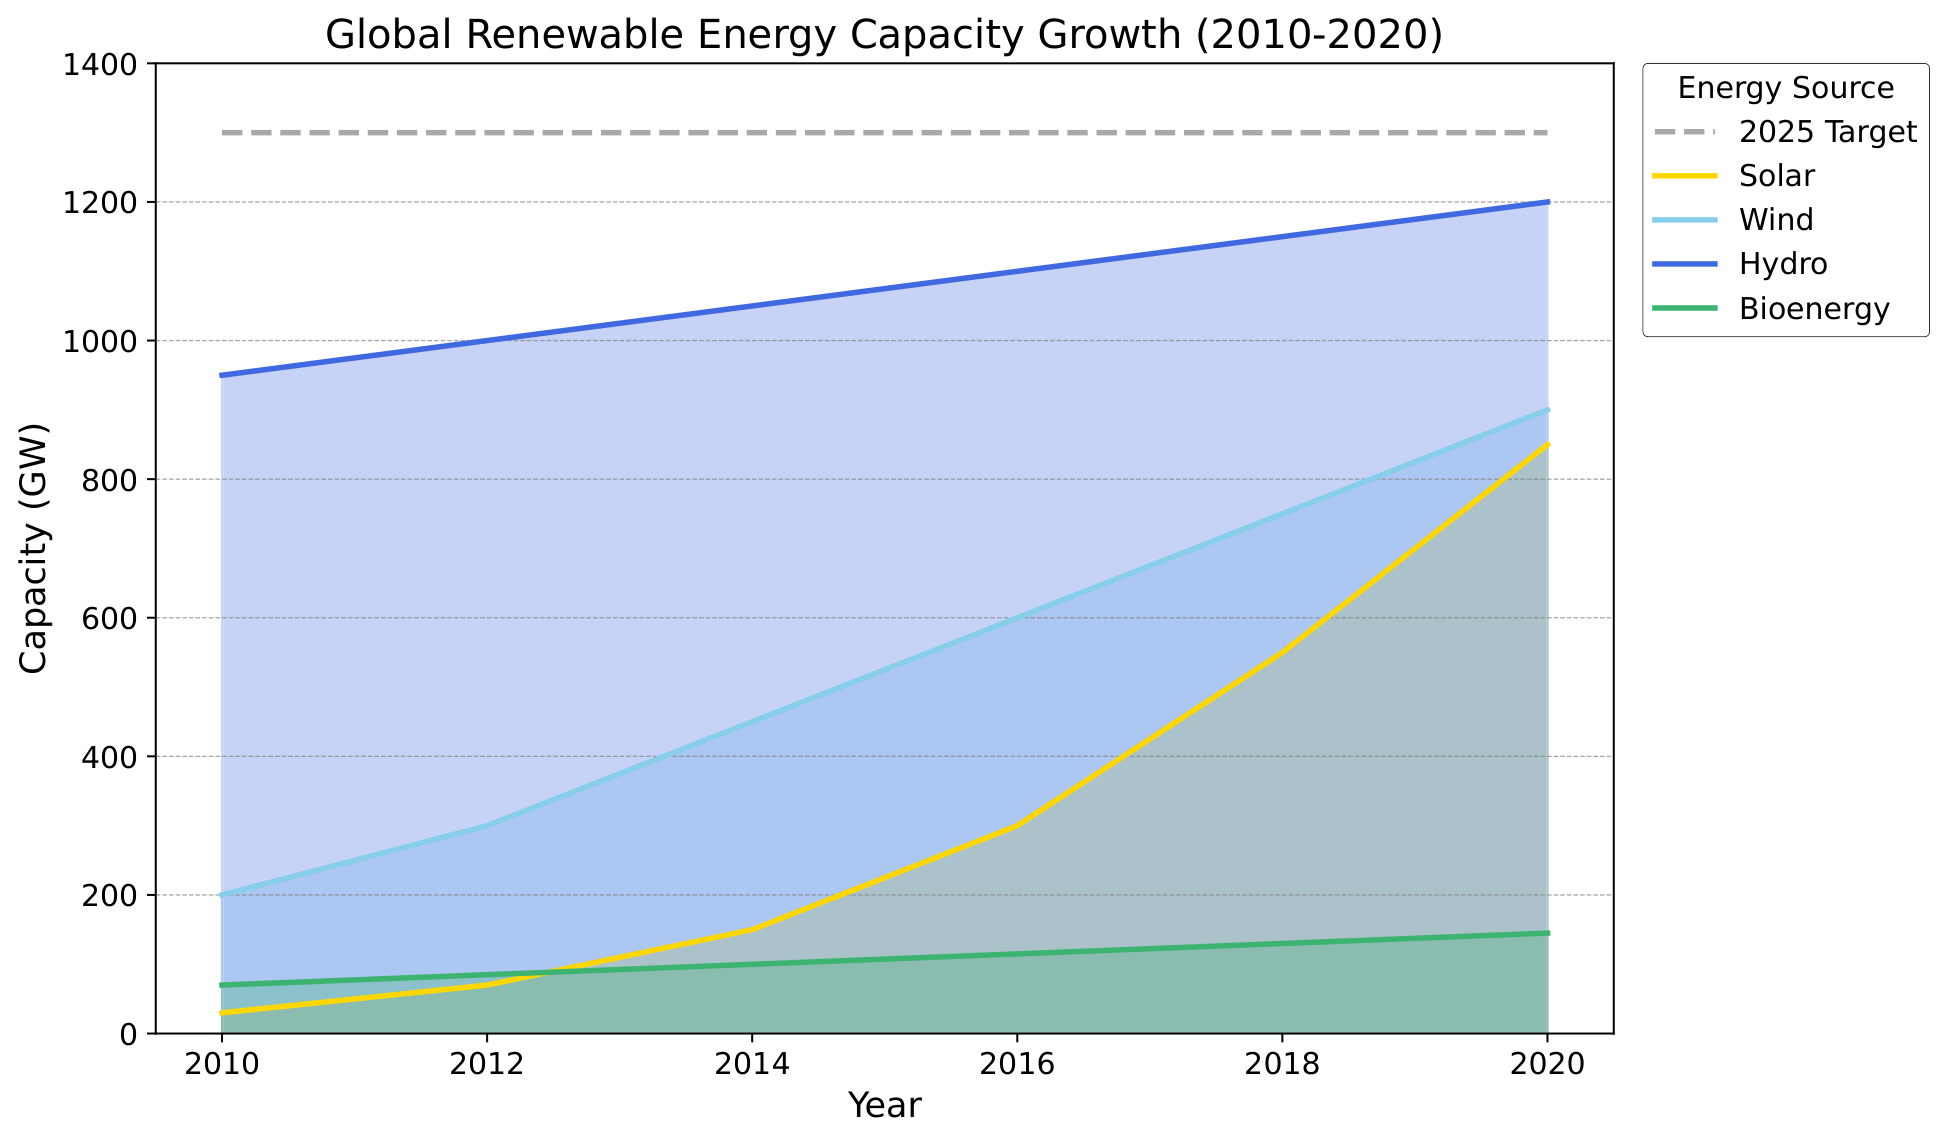
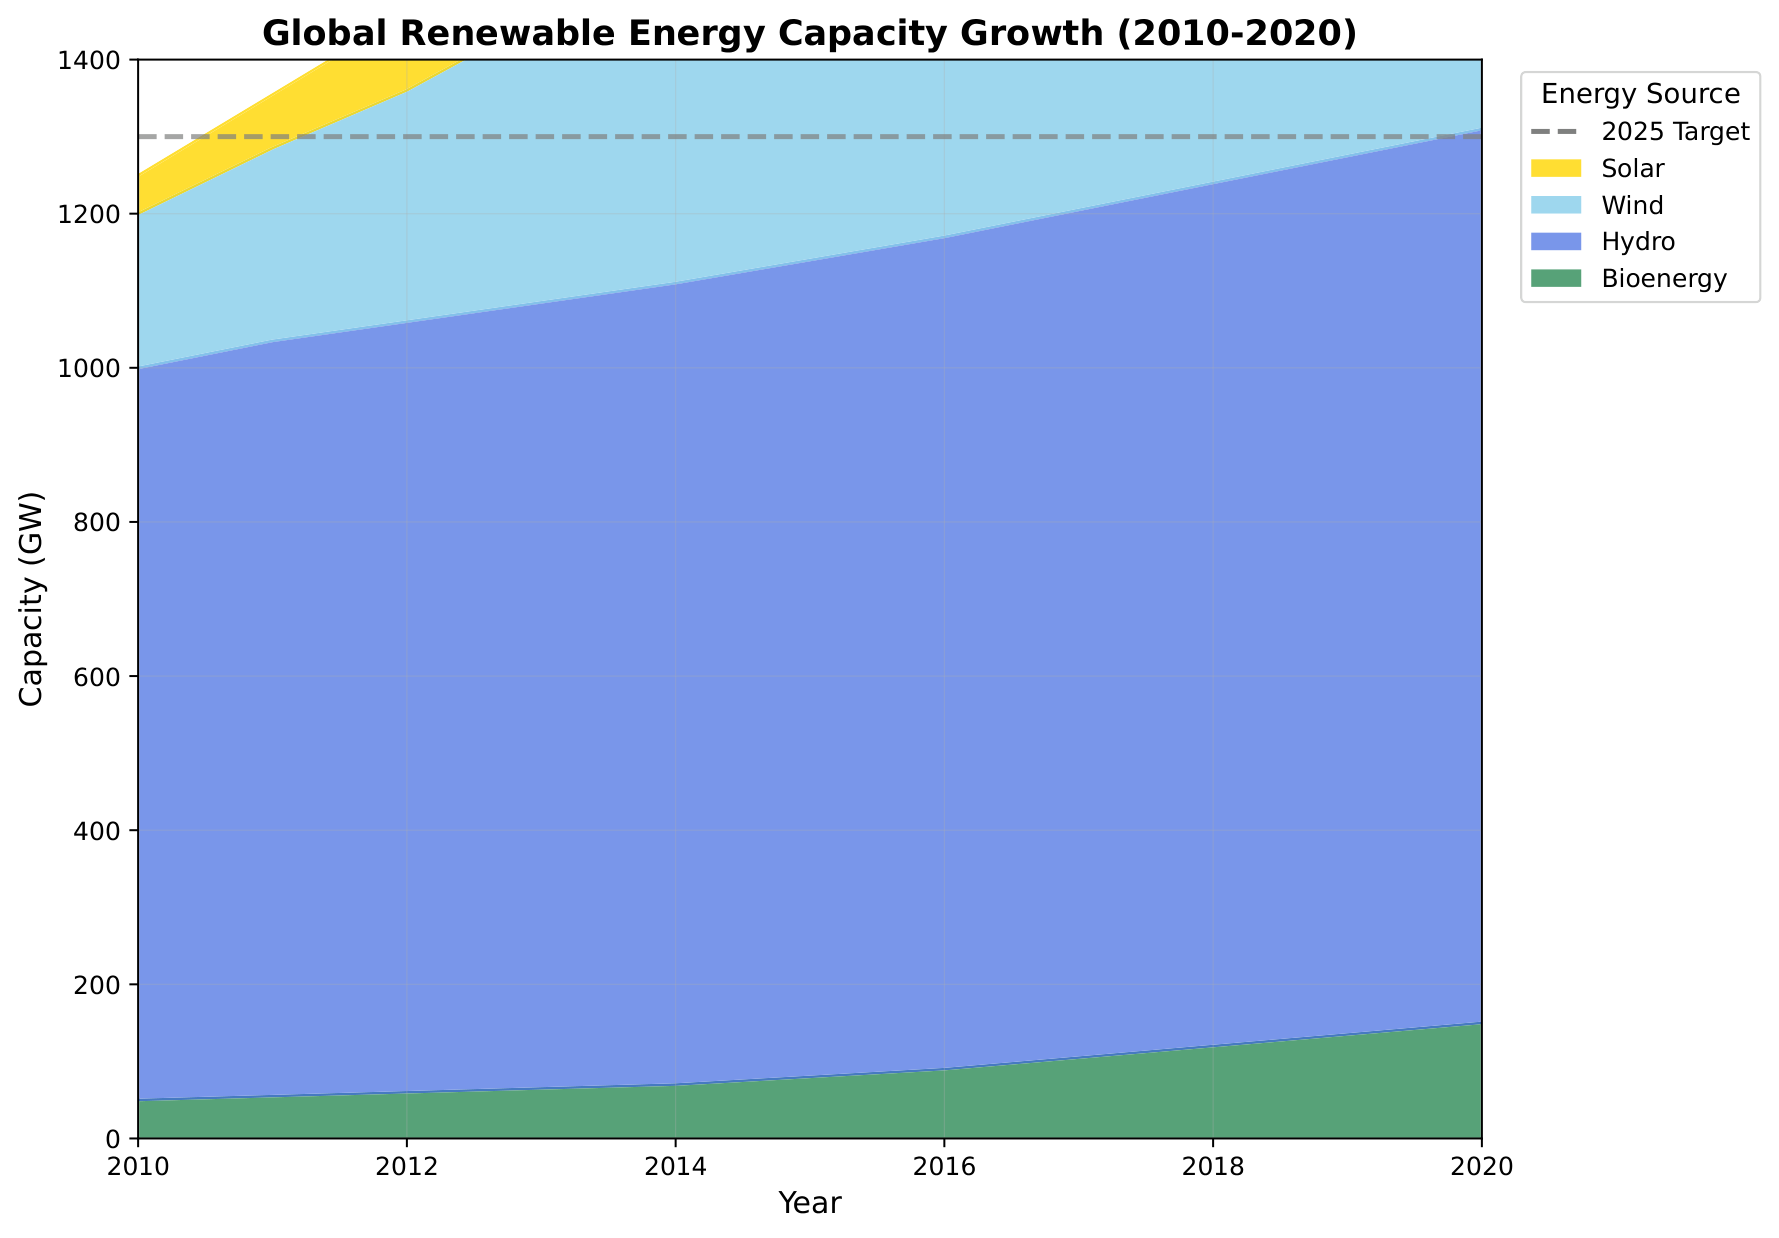
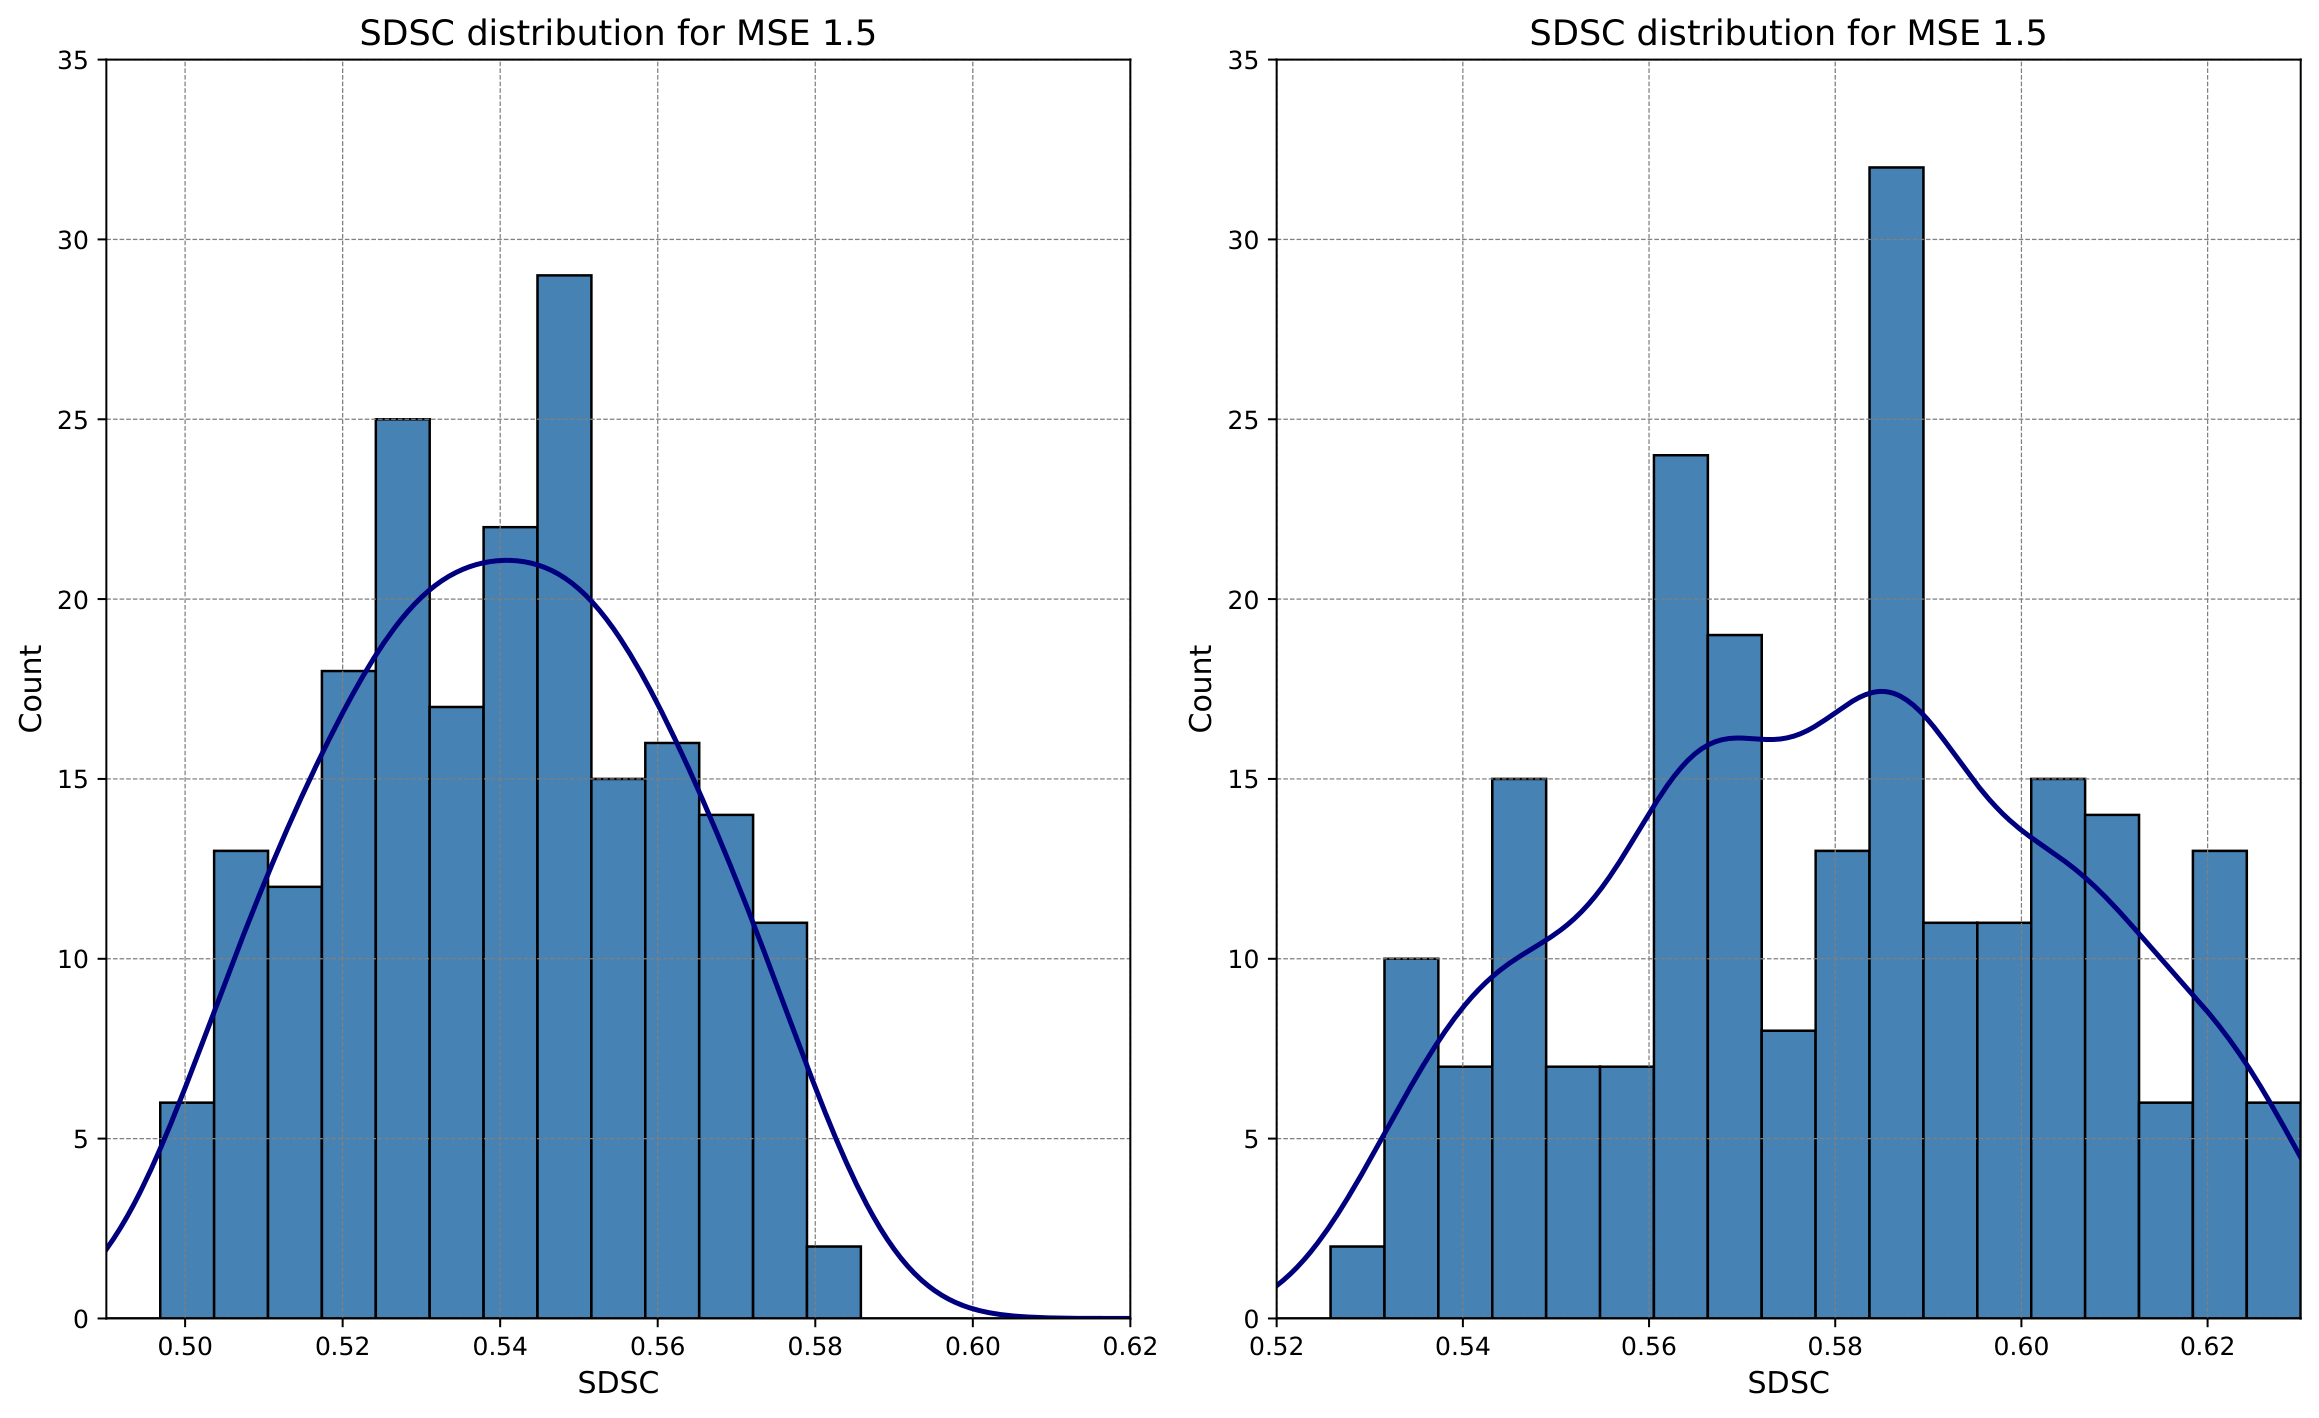
Figure 1: Comparison of chart quality judgment signals.
Despite obvious visual flaws, similarity metrics
(PSNR ↑, SSIM ↑, LPIPS ↓, CLIP ↑, DINOv3 ↑),
rule-based metrics, and LMM evaluators tend to give a high score,
failing to identify incorrect charts.
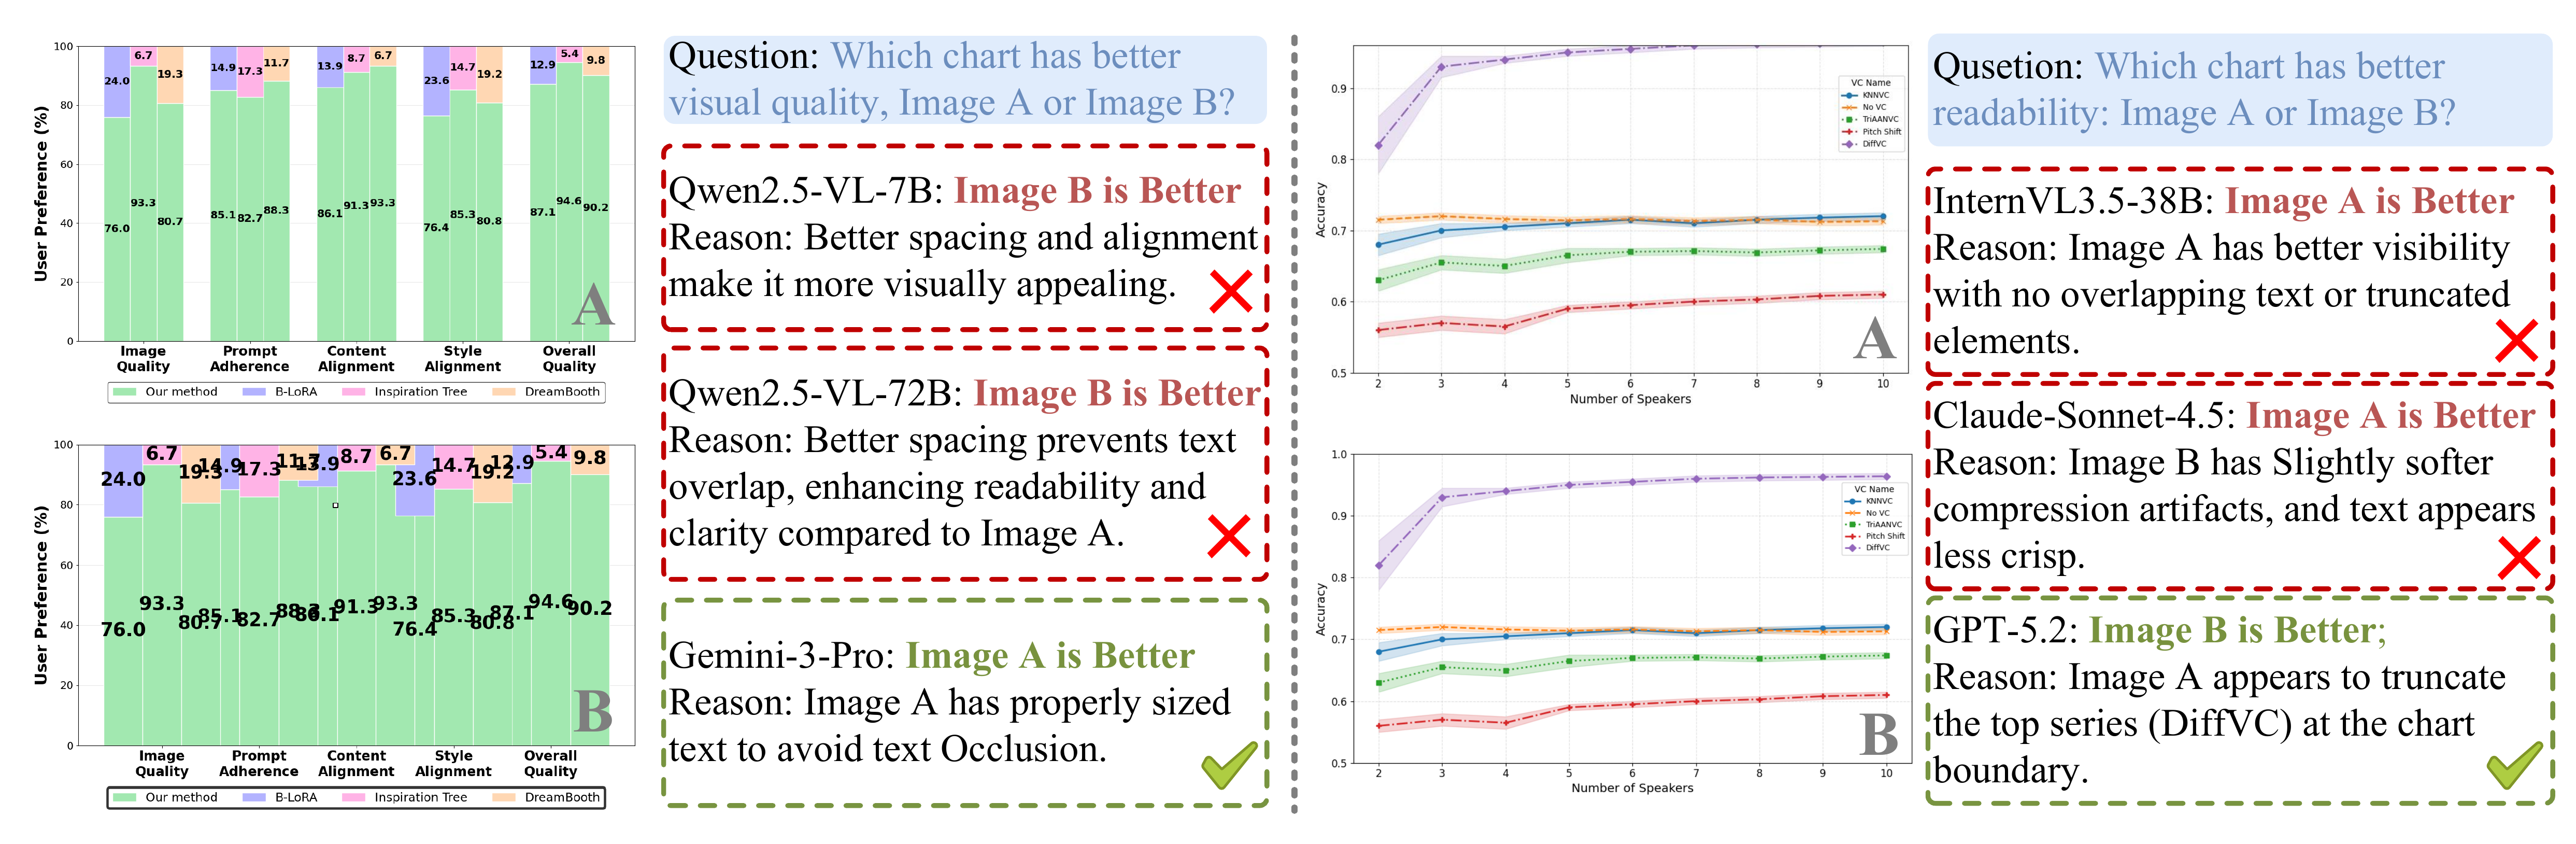
Figure 2: Open-source LMMs often fail to select the
correct chart even when visual differences are clear.
Abstract
Building strong chart-to-code systems increasingly relies on
reinforcement learning, whose effectiveness depends critically on
the quality of the reward signal. Large Multimodal Models (LMMs)
play a natural critical role in jointly assessing chart visual
appearance and task requirements. They are therefore increasingly
used as visual critics and reward models, yet their reliability as
judges remains largely unexplored. To this end, we introduce
ChartJudgeBench, a diagnostic vision-language benchmark for
assessing LMM judges in chart-to-code workflows. It includes 1,003
Chart Perception Alignment (CPA) instances for pairwise chart
comparison and 650 Chart Reasoning Judgment (CRJ) instances for
binary Accept/Reject verification in Chart Reproduction
and Chart Editing. Together, these tasks emulate the core
judging decisions required in agentic refinement and RL-based chart
optimization. Our evaluation of strong LMMs reveals four systematic
limitations: (i) positional bias in pairwise comparison, (ii) a
strong tendency to overpredict Accept, (iii) difficulty in
matching visual styles and aesthetics, and (iv) an unexpected
leniency bias in RL-trained models. These findings show that current
LMM judges require explicit reliability validation before being used
as critics or reward models in chart-to-code optimization.
Matching visual styles and aesthetics remains difficult.
04
RL-trained models exhibit an unexpected leniency bias.
Benchmark Setting
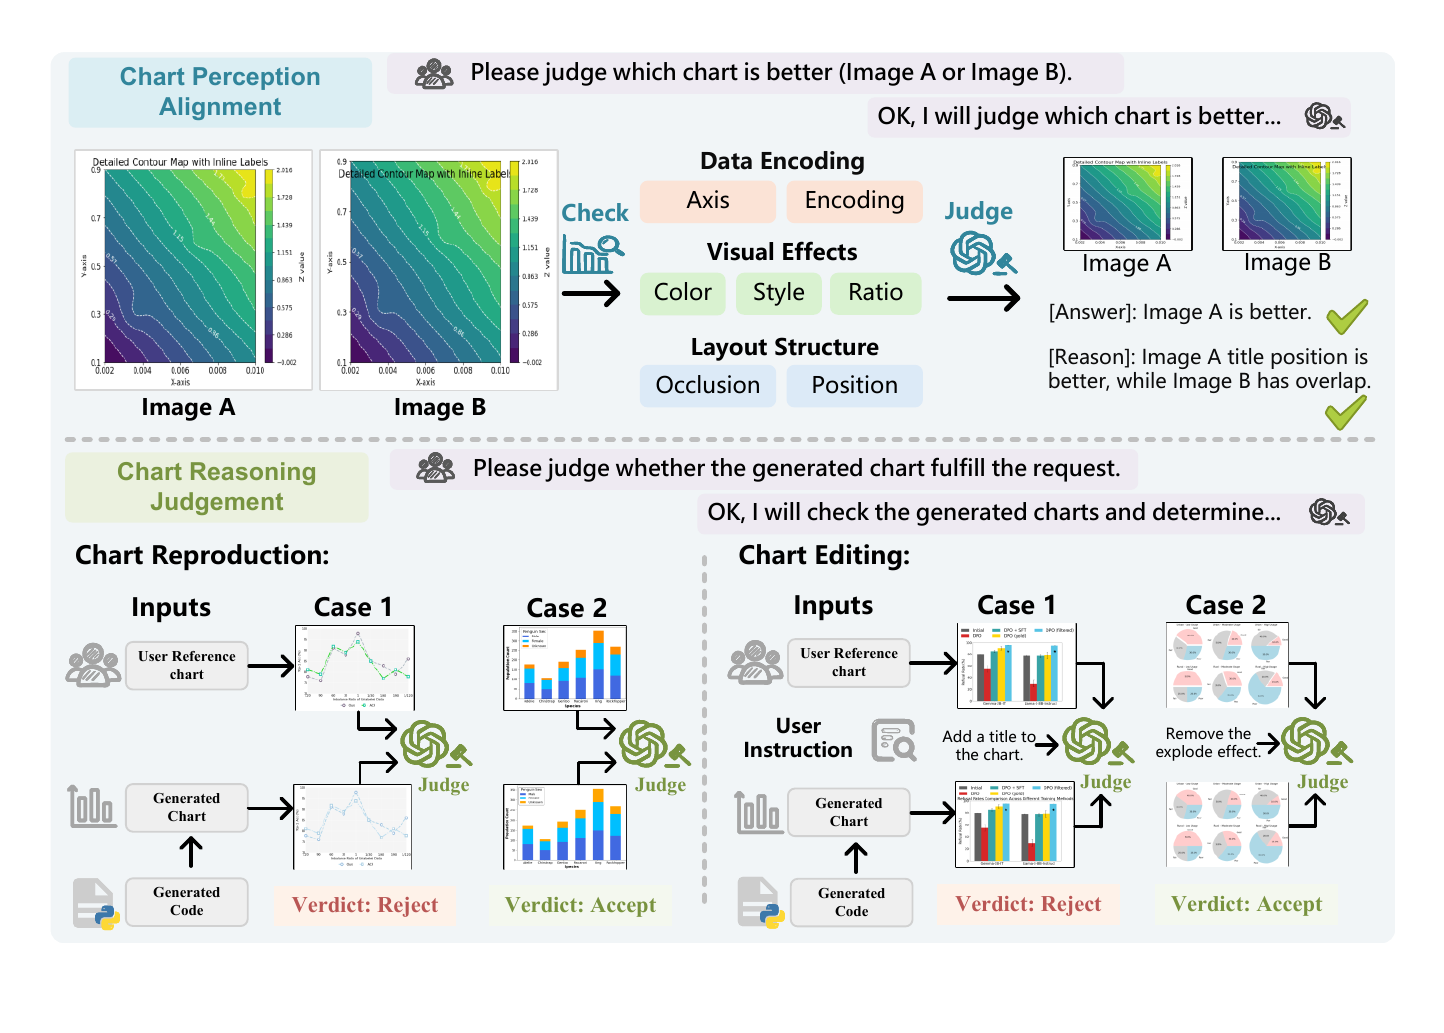
Figure 3:Illustration of CPA and CRJ tasks in ChartJudgeBench. The benchmark includes one
CPA task, where the model chooses the visually better chart between two candidates, and two
CRJ subtasks: Chart Reproduction, which judges whether a generated chart faithfully matches
the reference, and Chart Editing, which judges whether an edit is correctly applied without
introducing side effects.
Results and Analysis
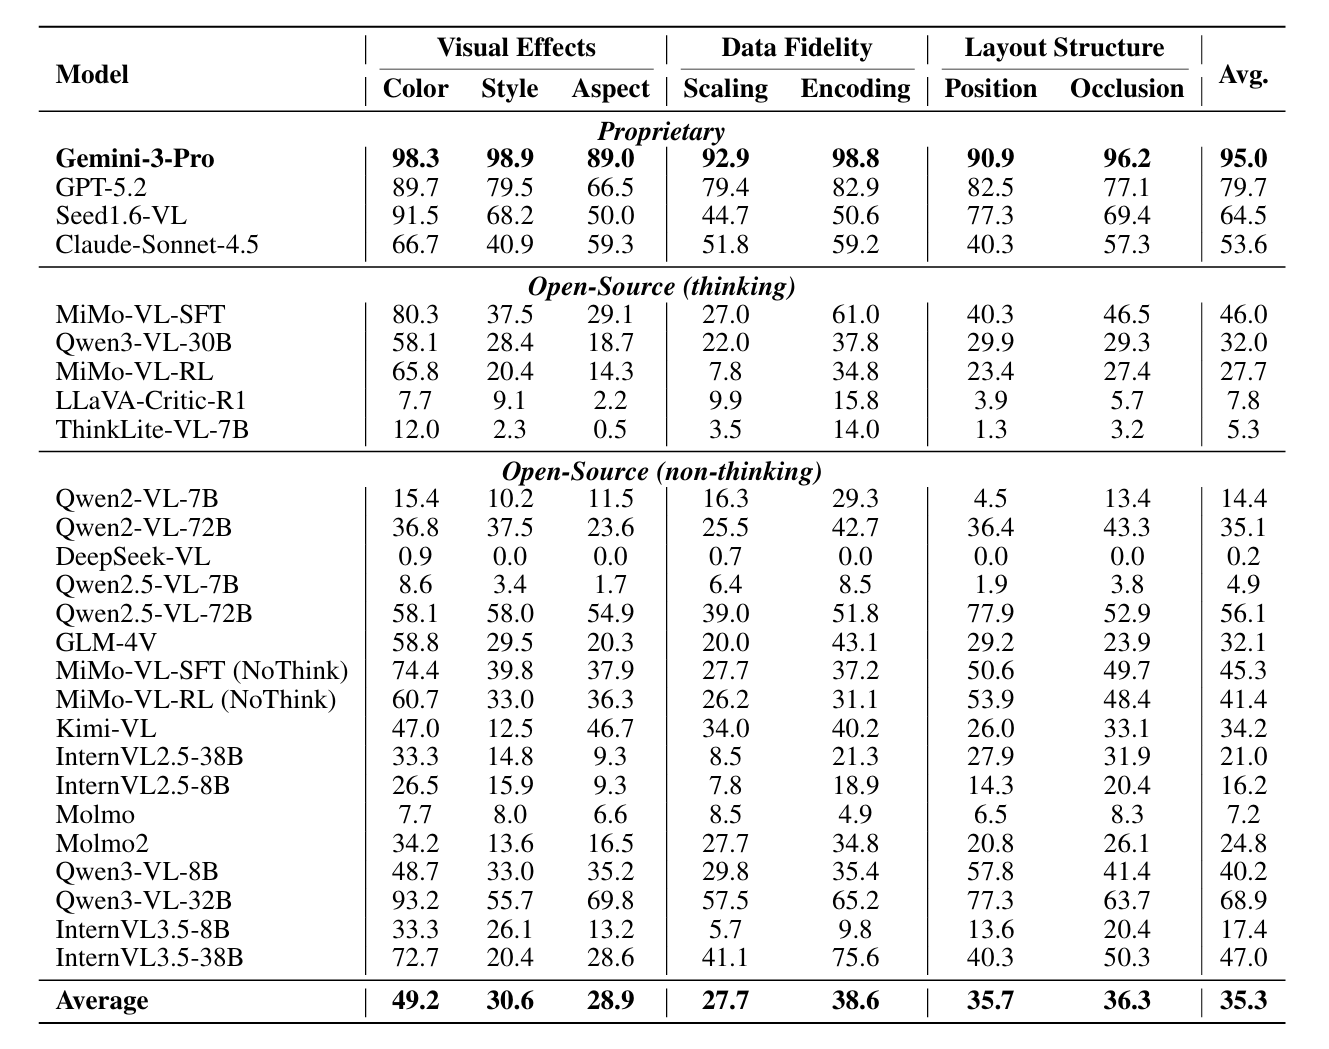
Table 1:Evaluation results on Chart Perception
Alignment Tasks. All the results are Accuracy (%)
across 7 sub-dimensions and 3 major categories.
Summary 1: A substantial performance gap exists
between proprietary and open-source models in chart
quality perception.
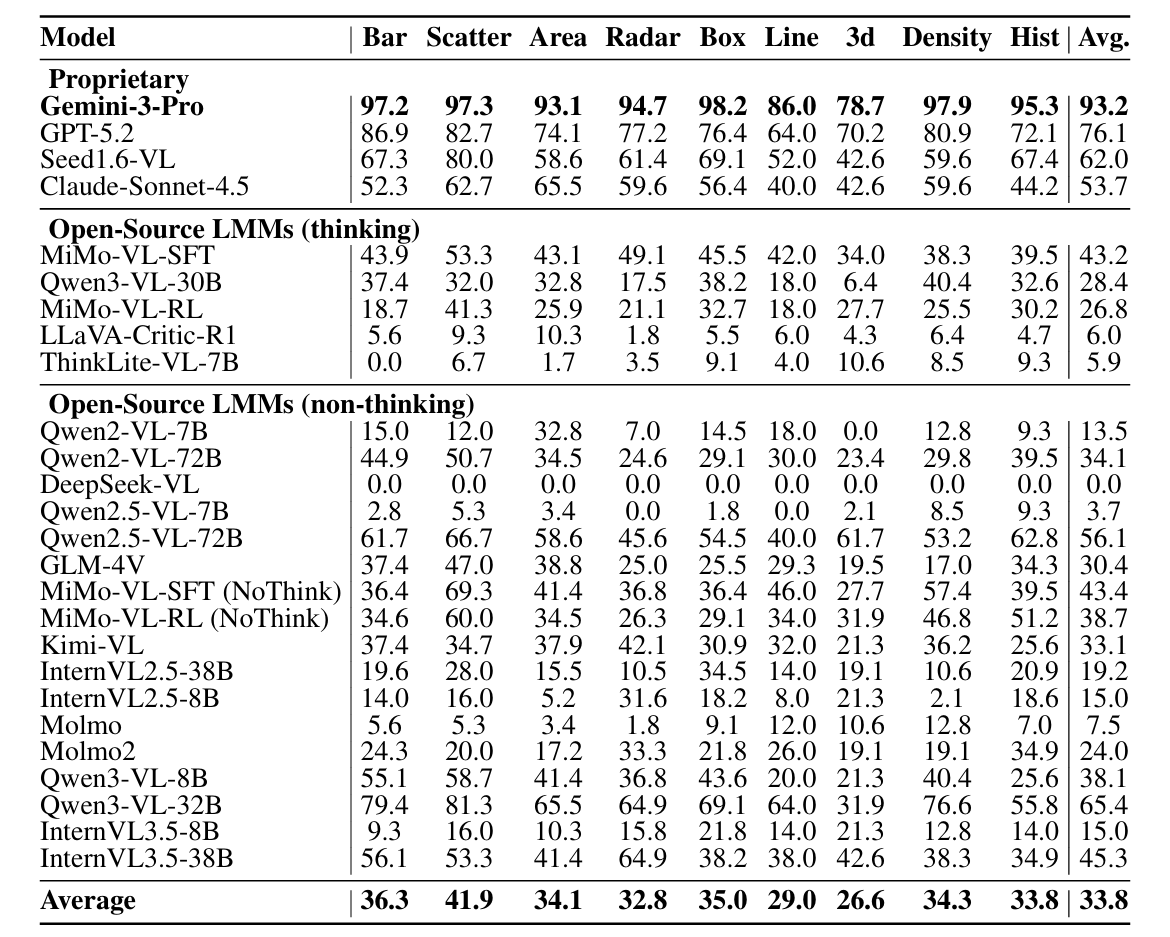
Table 2:Evaluation results on Chart Perception
Alignment Tasks. The comparison results on diverse
chart types.
Summary 2: Model performance varies significantly
across different chart types.
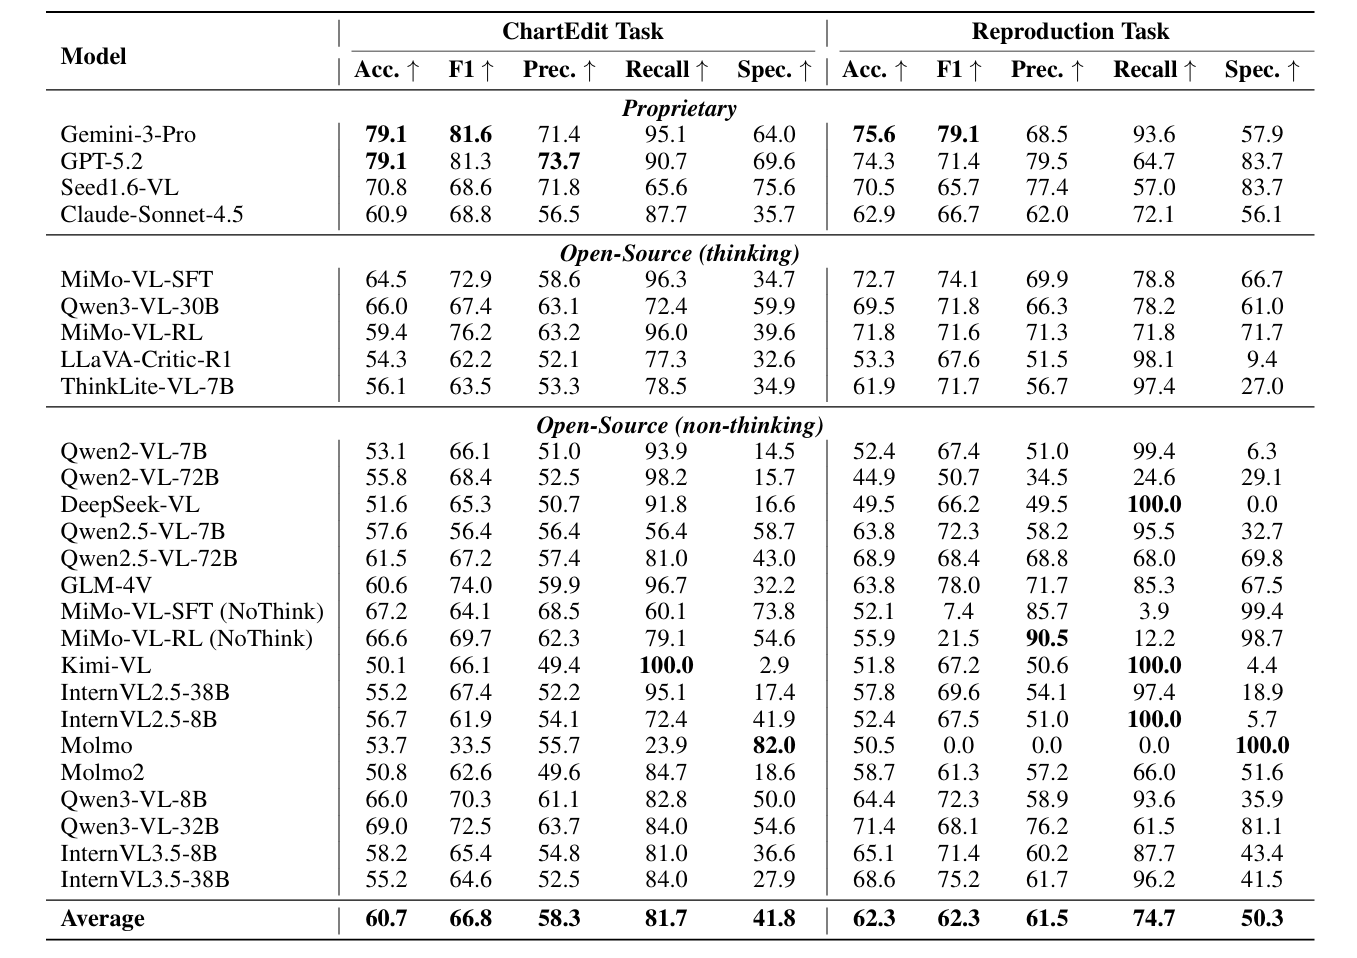
Table 3:Model Performance Evaluation on Chart
Reasoning Judgment Tasks. Best results in each column
are in bold. Spec. is
Specificity = TN / (TN + FP).
Summary 3: Proprietary models demonstrate robust
basic chart perception alignment, while their performance
degrades noticeably in the reasoning tasks.
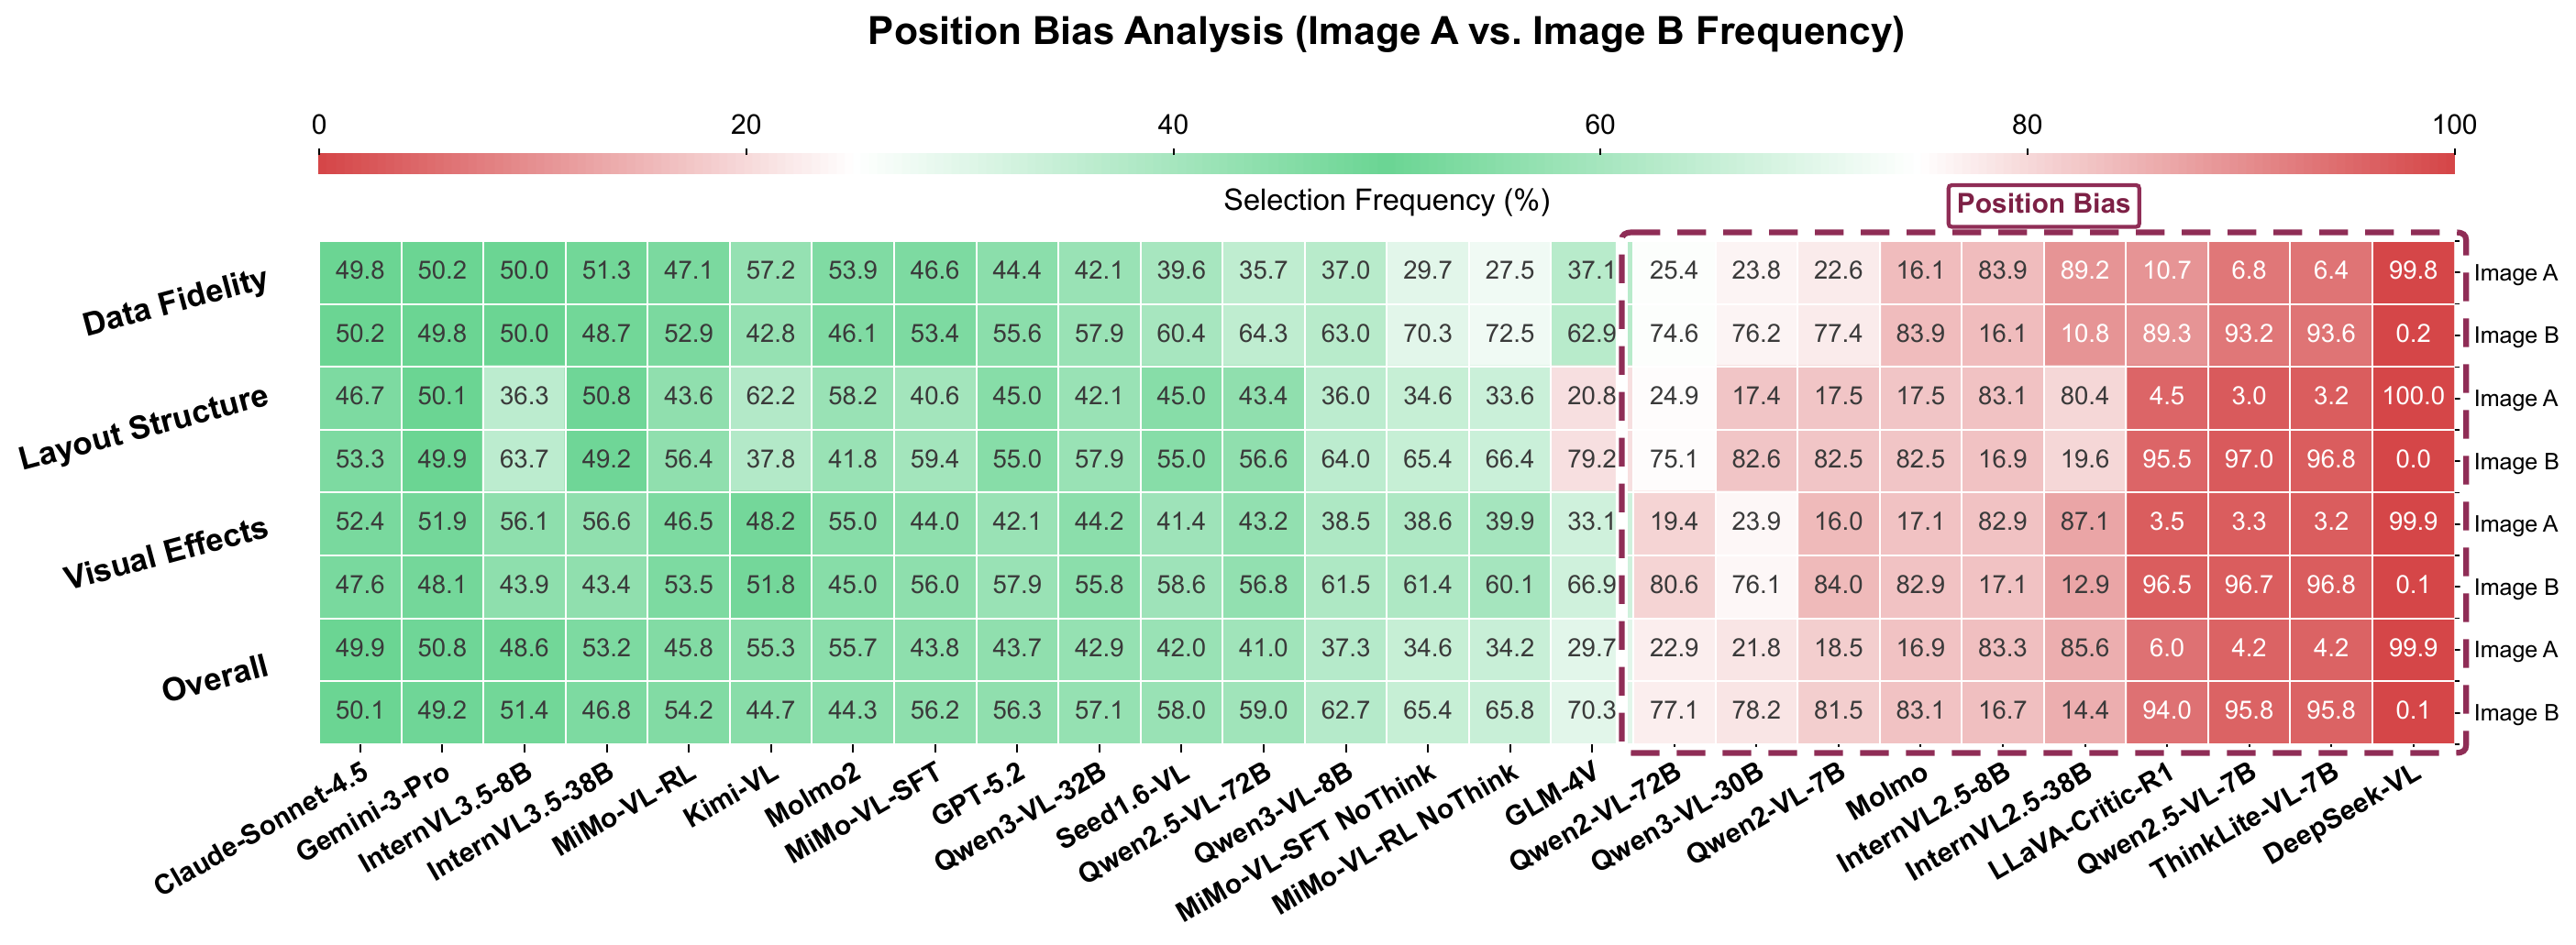
Figure 5: Positional preference in CPA. Many models
exhibit a strong tendency to favor a fixed image position.
Finding 2: When fine-grained visual discrimination
is insufficient, many models fall back to positional
preferences.
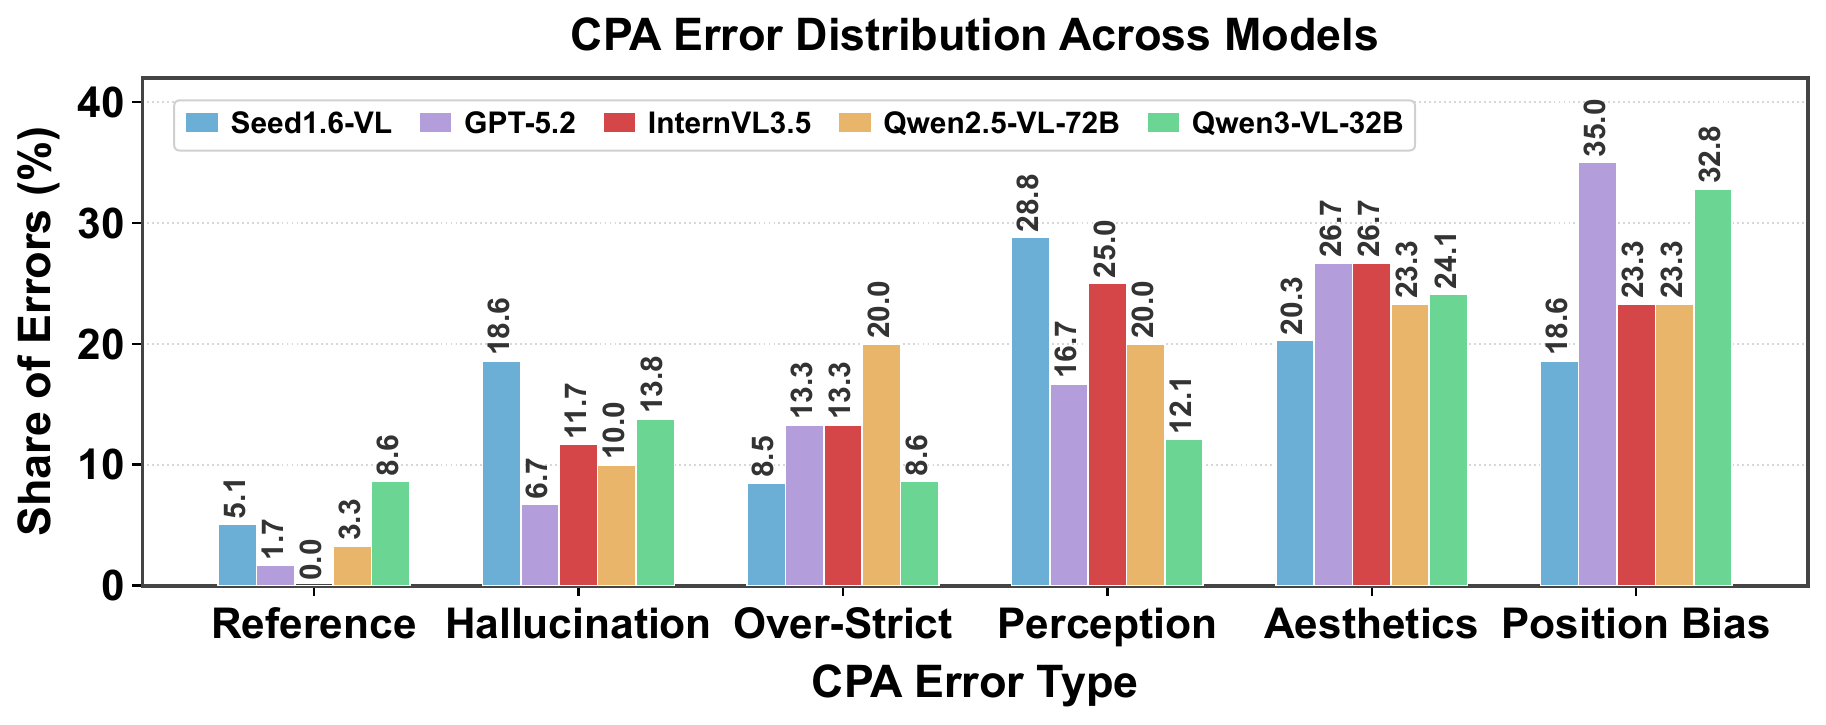
Figure 6: Percentage distribution of CPA error types
across representative LMMs.
Finding 5: Aesthetic alignment remains a common
failure mode.
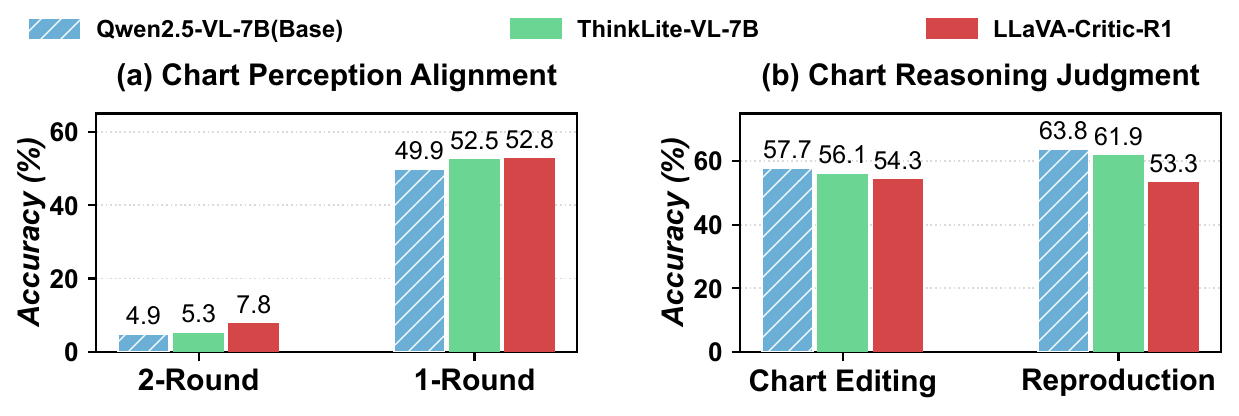
Figure 7: Accuracy comparison of the base and
post-trained models on (a) CPA and (b) CRJ.
Finding 7: Post-training and thinking-style
inference provide limited gains in pairwise chart
comparison.
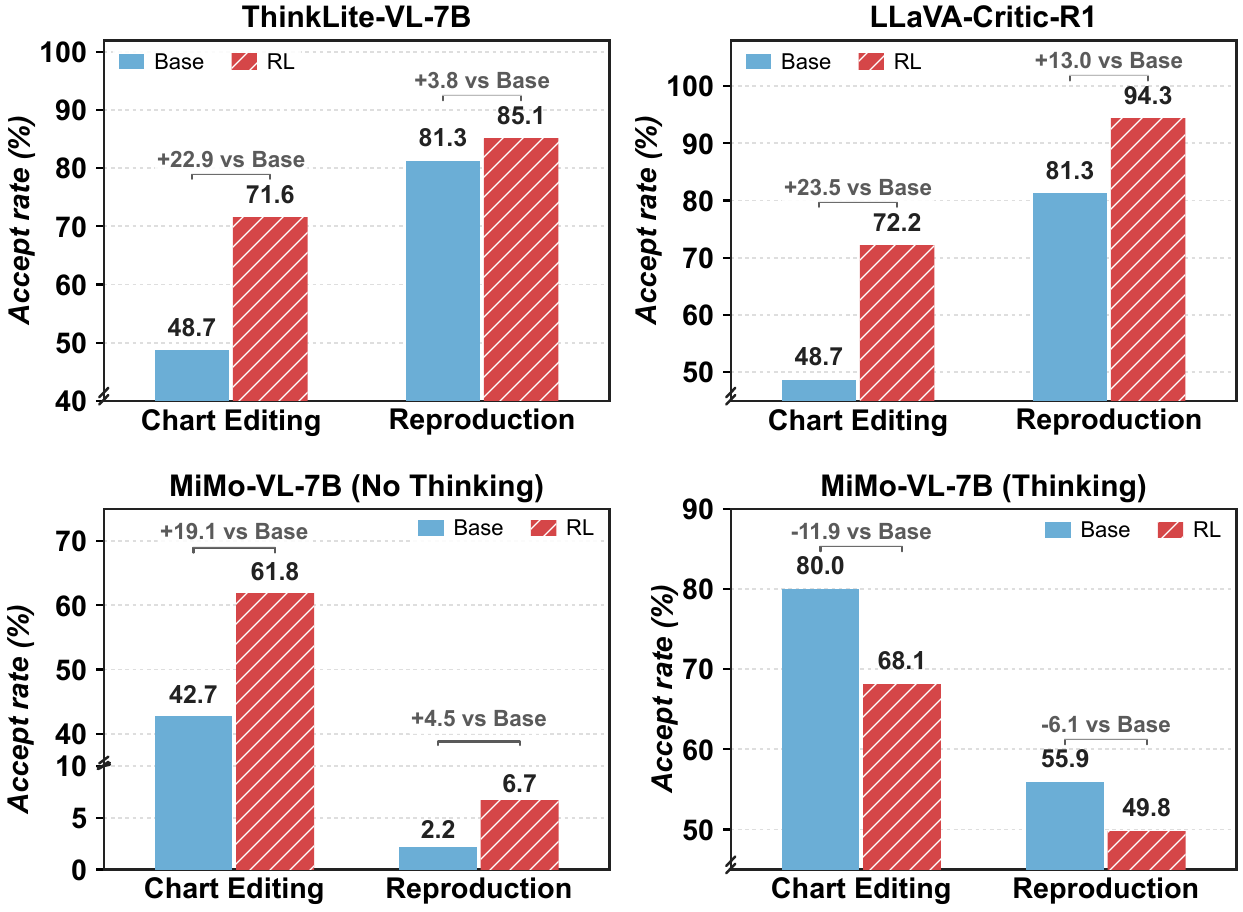
Finding 8: Post-training and thinking-style
inference may increase leniency bias in CRJ and therefore
reduce accuracy.
Figure 8: Acceptance rates of base, post-trained,
and thinking models in CRJ. Excessively high rates indicate
overprediction of the Accept label.
Finding 8: Post-training and thinking-style
inference can make CRJ judges more lenient rather than
improving fine-grained chart verification.
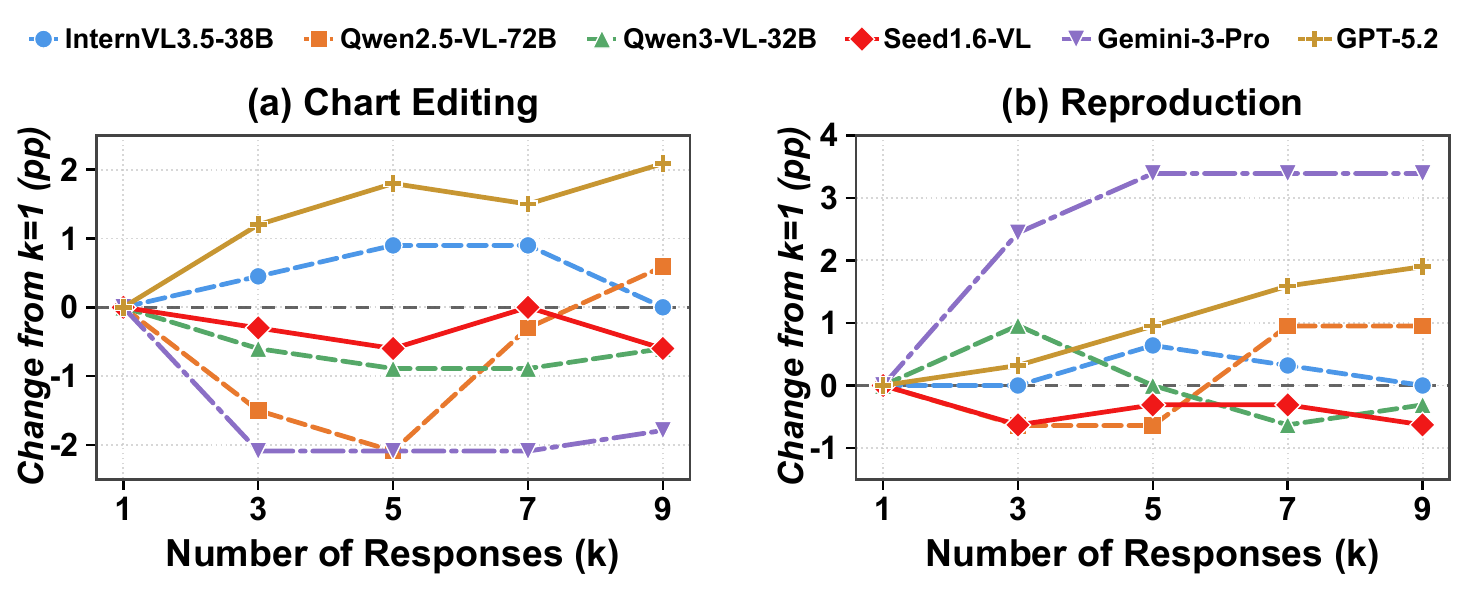
Figure 10: Test-time computation scaling with
majority voting over K in {1, 3, 5, 7, 9} runs.
Finding 9: Majority voting provides limited and
model-dependent gains for chart judgment.
Case Study
Figure 9:Case studies. Representative failures
of LMM judges in chart judgment. Zoom in for the best view.
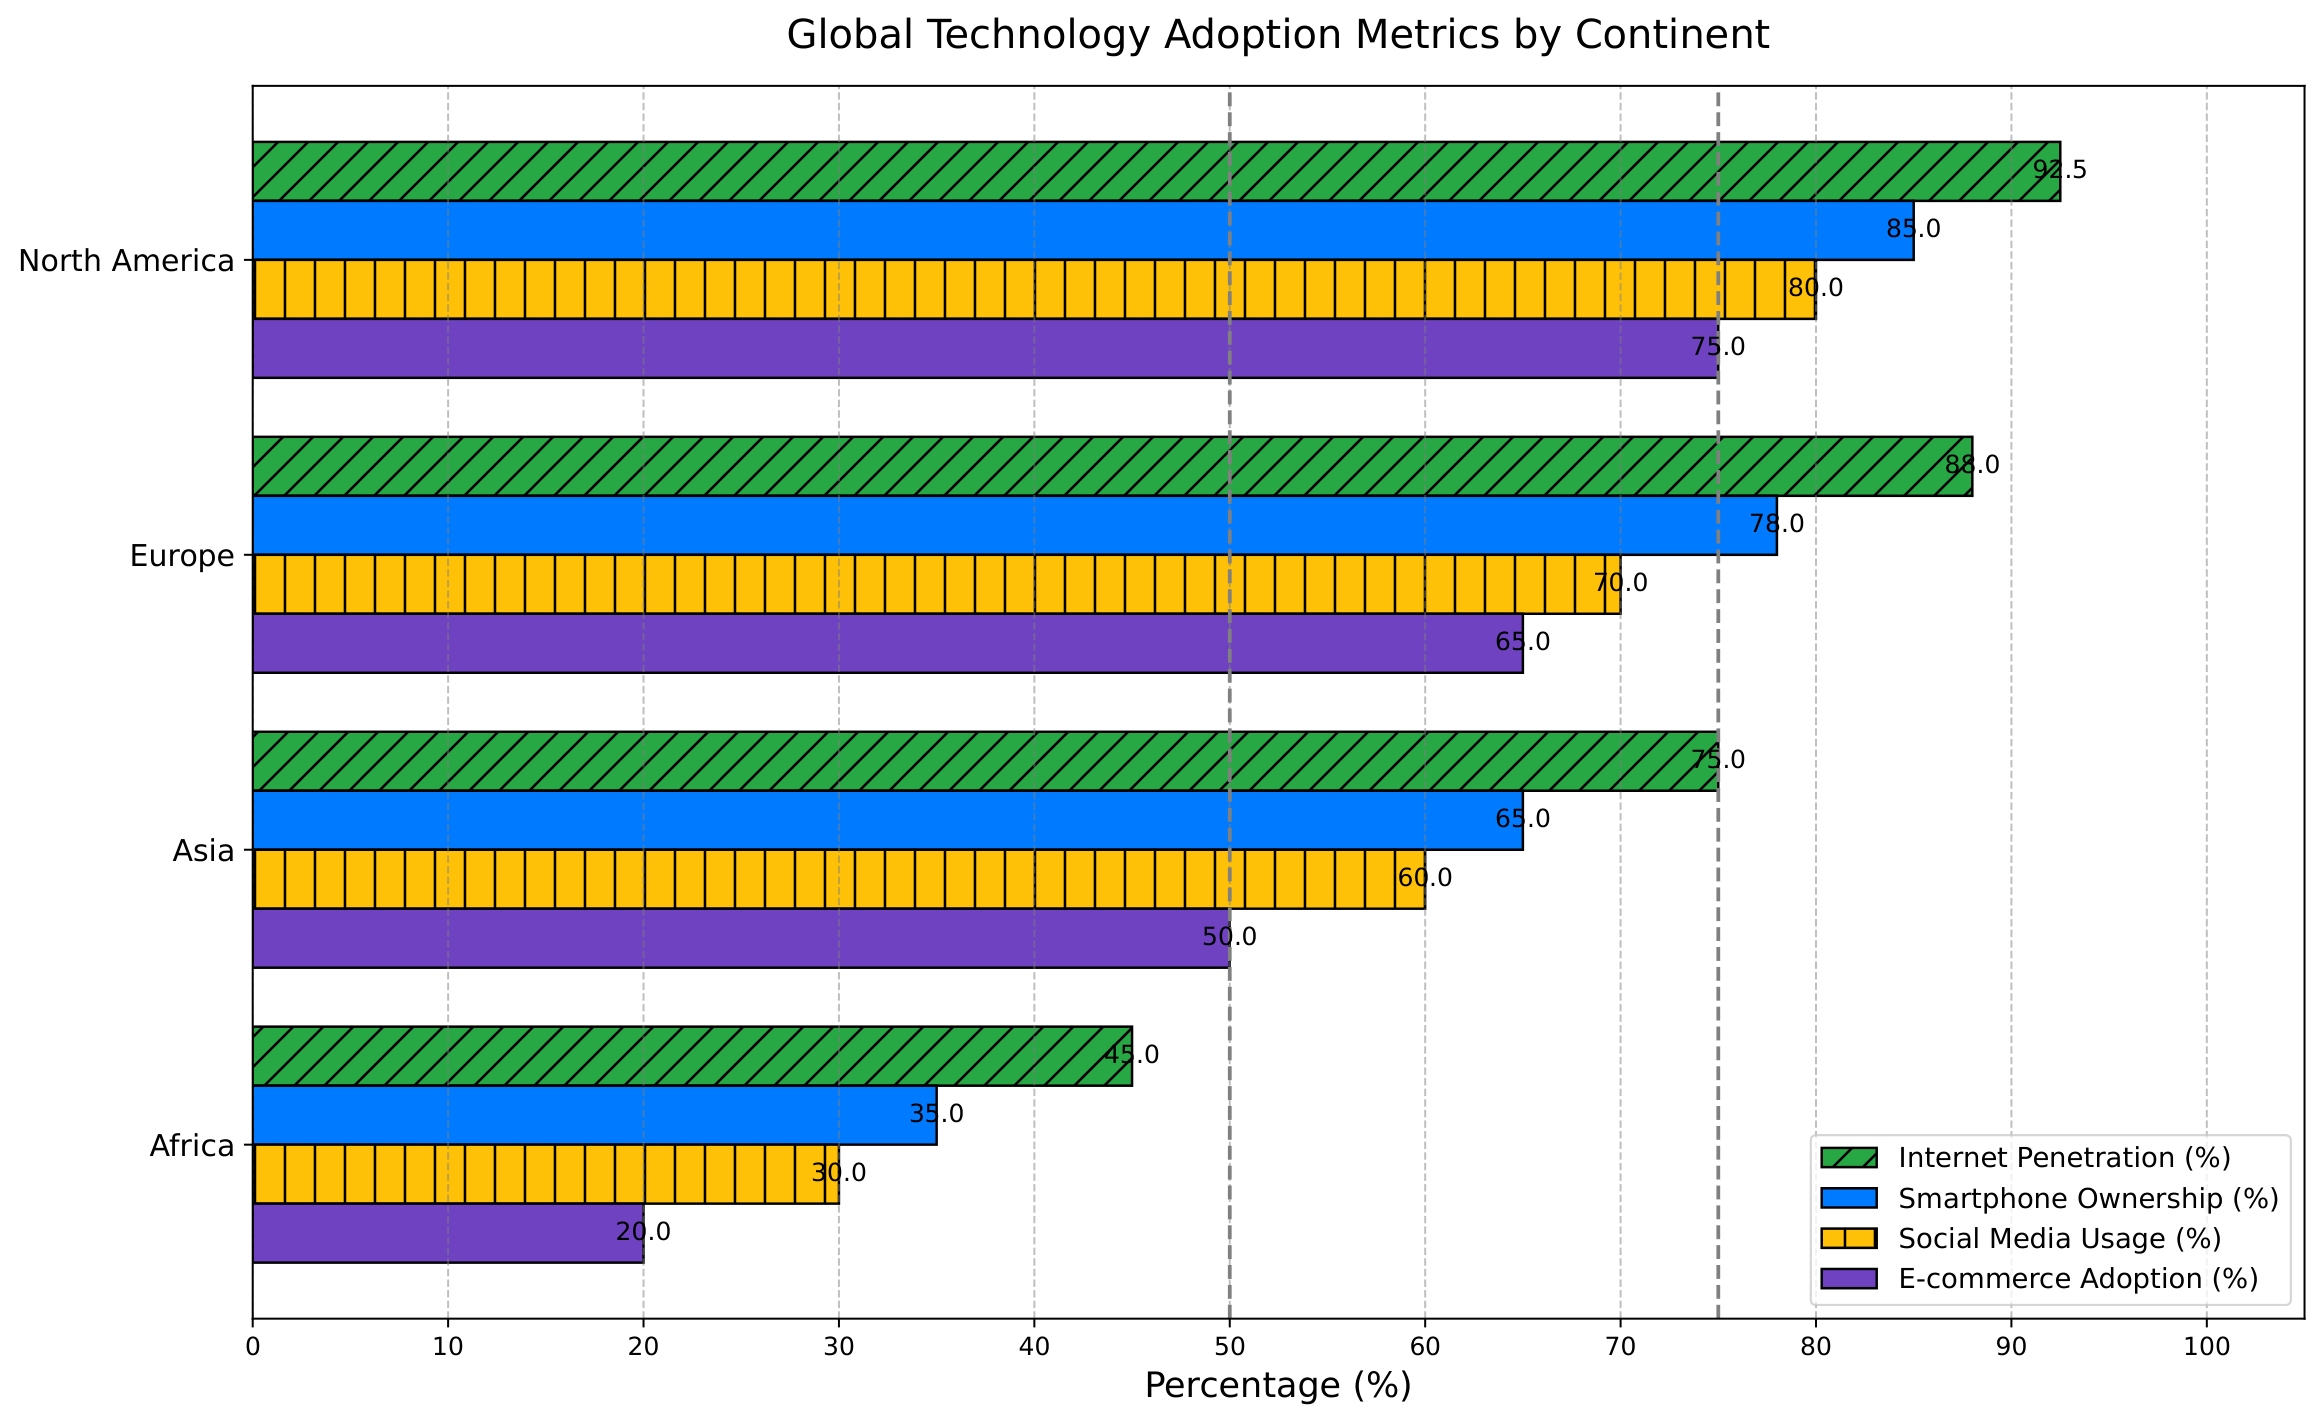
(i) Aesthetic Misalignment. The model prefers explicit labels but misses the more legible chart without overlap.
(ii) Ignoring Glaring Visual Defects. The model accepts charts with obvious flaws such as incomplete data or text overlap.
(iii) Partial Verification Shortcut. The model checks instruction completion but often overlooks collateral visual damage.
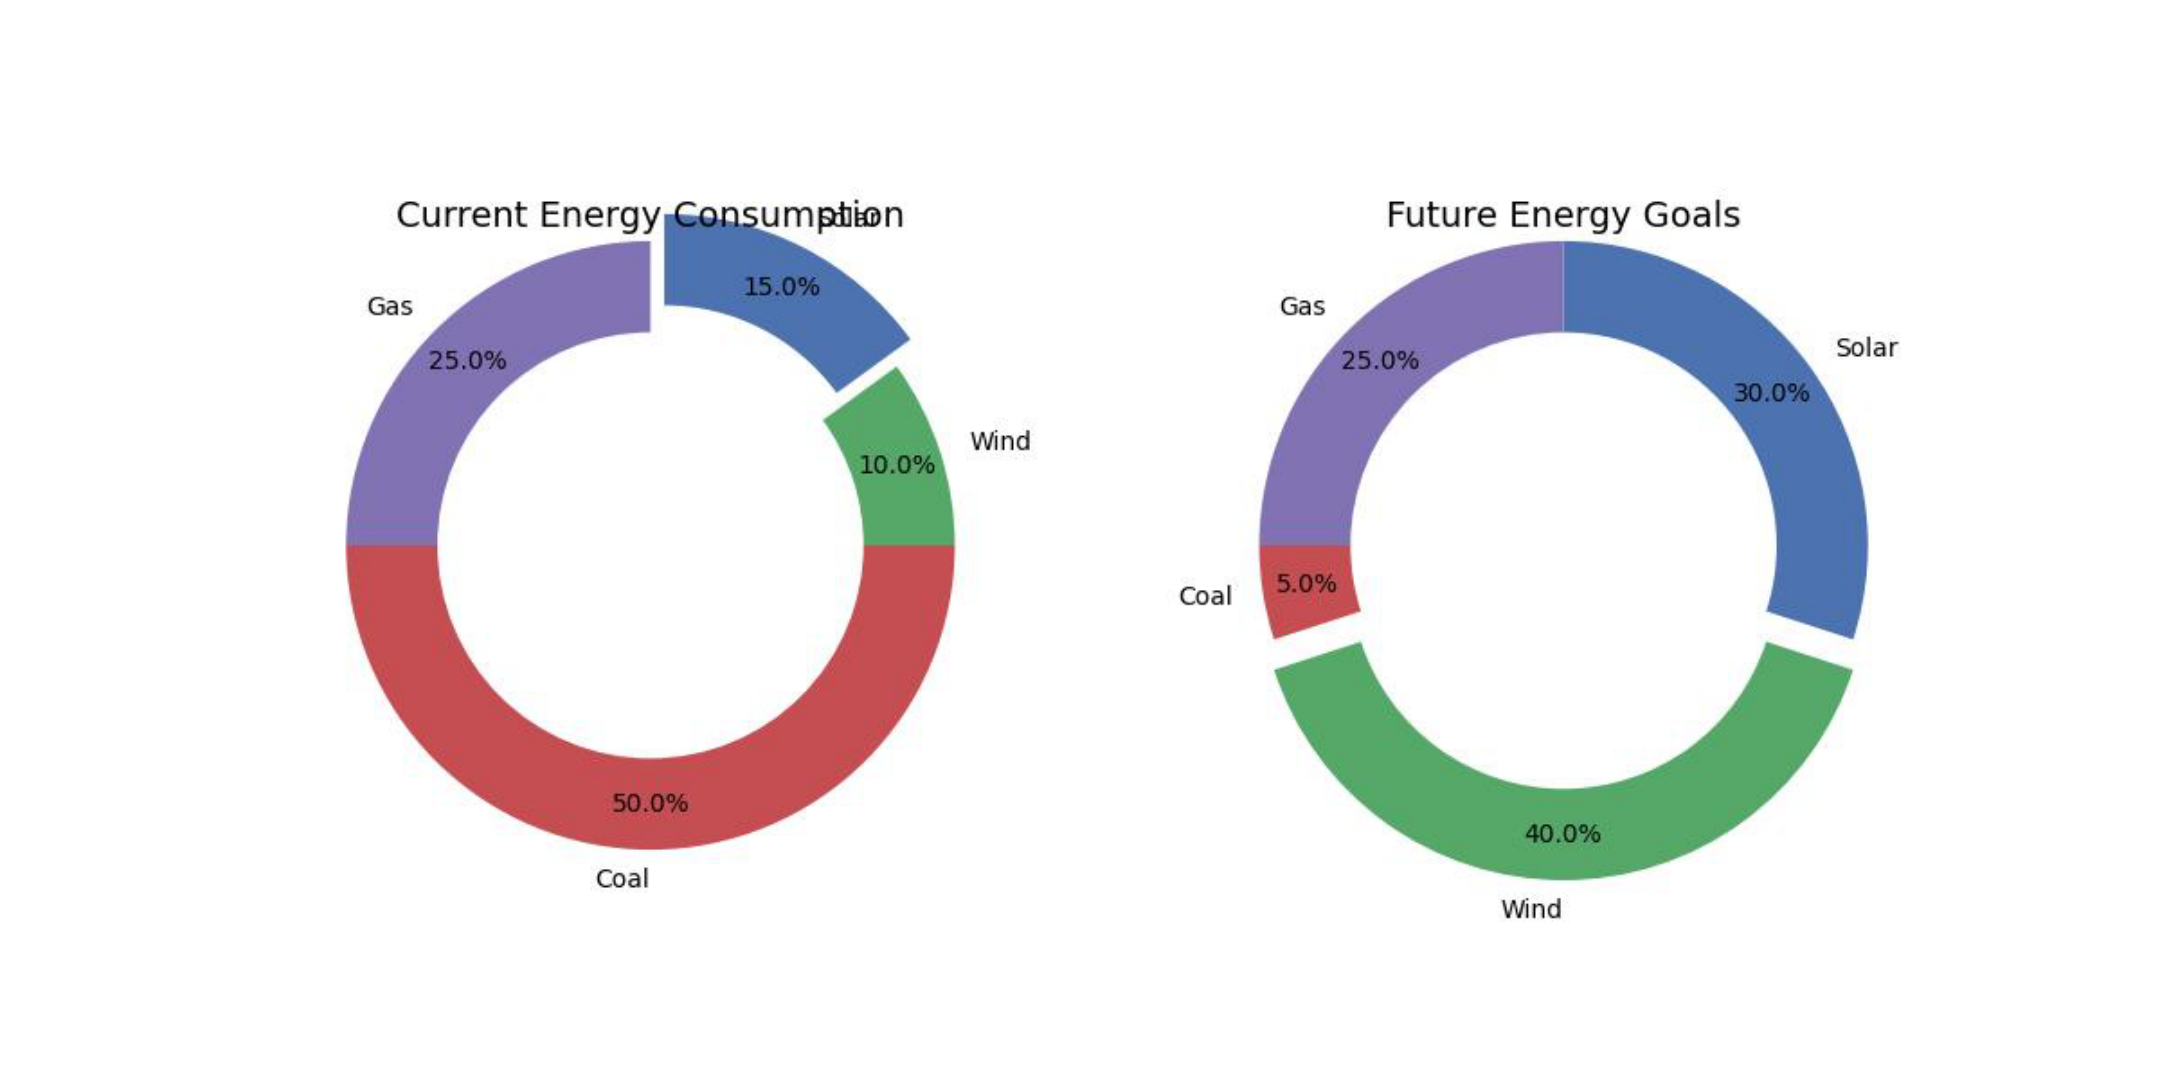
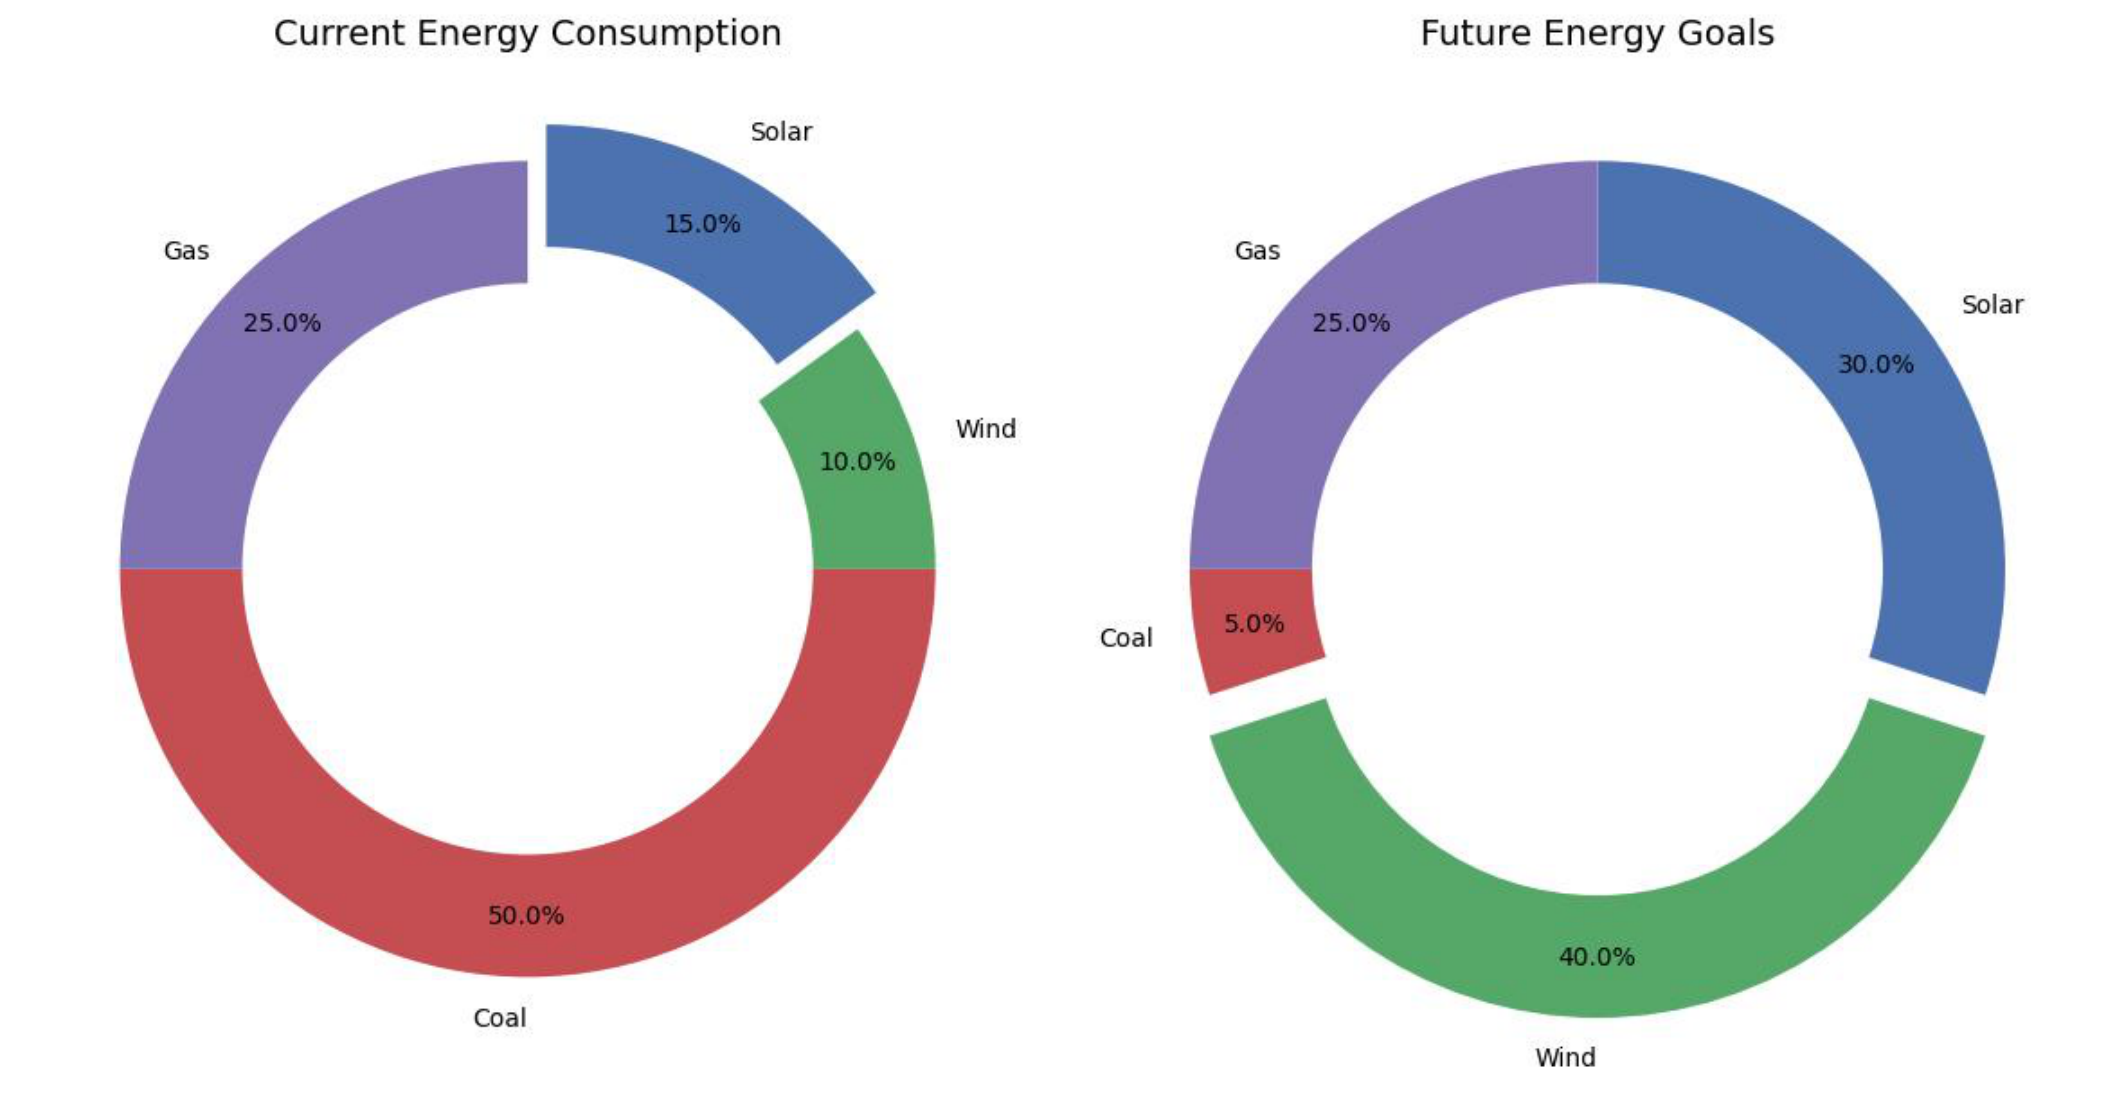
Image AImage B
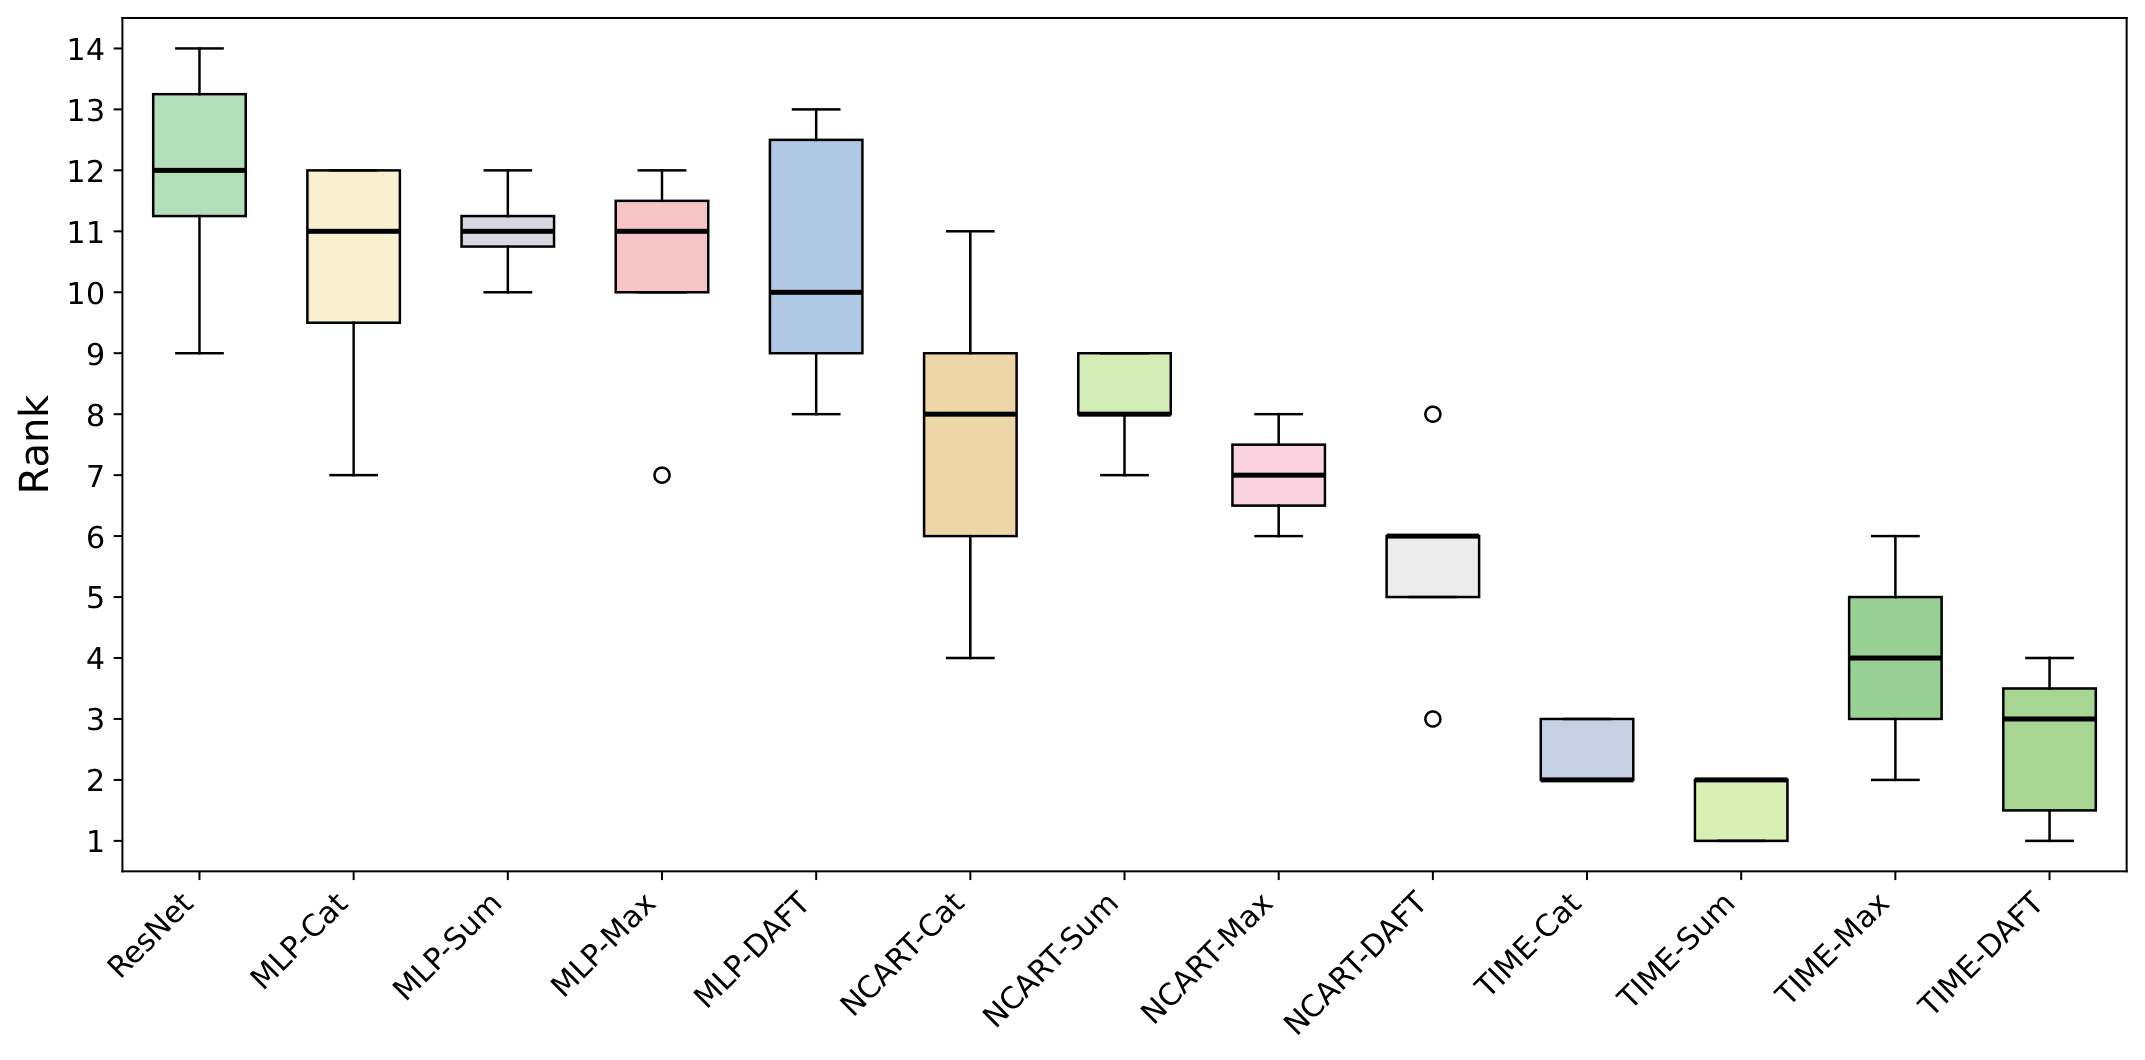
Error Analysis: PerceptionModel: Qwen3-VL-30BGolden Answer: Image B
Model Answer: "[Answer]: Image A. [Reason]: Image A has no text overlap unlike Image B where 'Wind' label partially overlaps the chart."
Analysis: "Image A has overlap between the 'Current Energy Consumption' title and the 15.0% segment label, causing occlusion and reduced readability, while Image B is free of such occlusion and offers better readability."
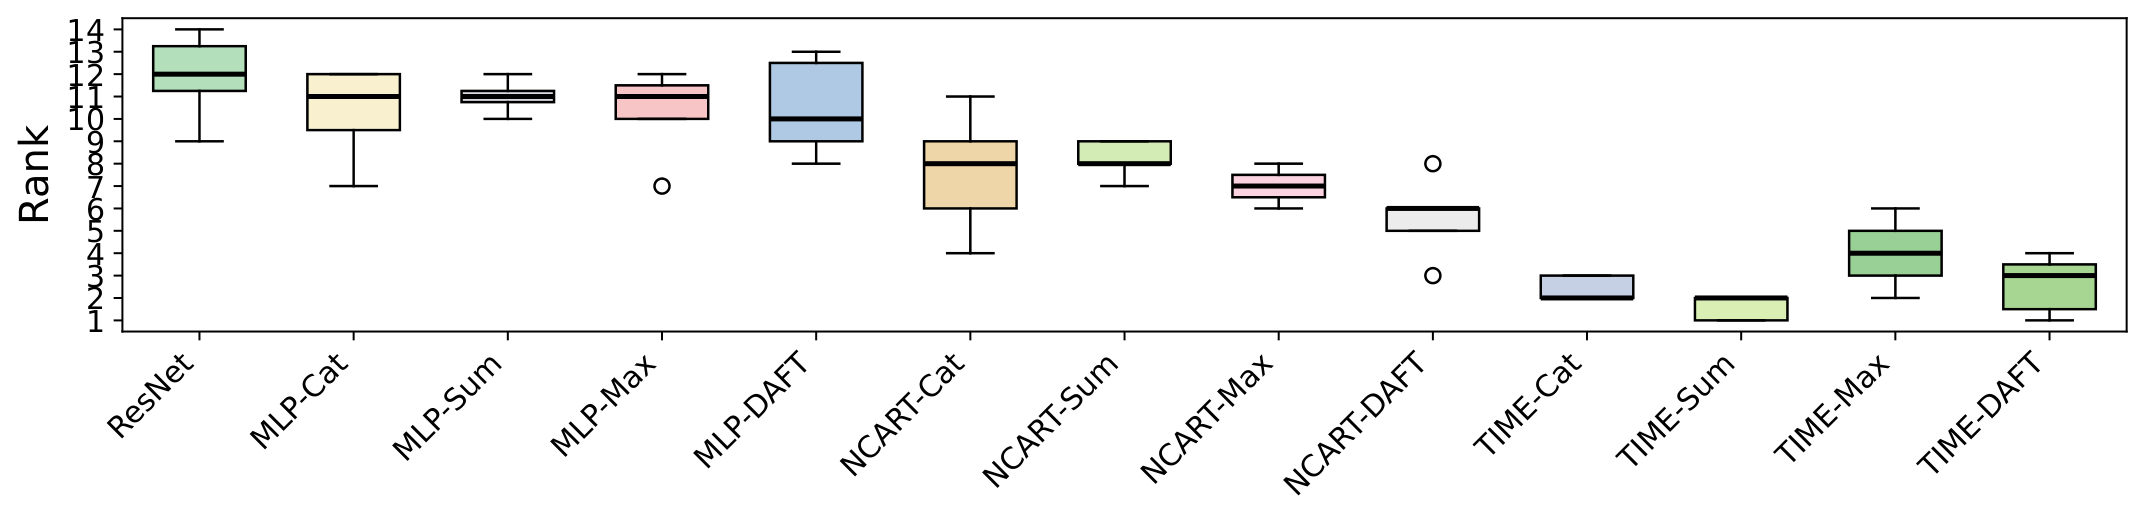
Image AImage B
Error Analysis: Position BiasModel: InternVL3.5-38BGolden Answer: Image B
Model Answer: "[Answer]: Image A. [Reason]: Layout & Visibility: Image A has better spacing and alignment, reducing occlusion and improving readability."
Analysis: "Image A has severe overlap between the vertical 'Rank' y-axis label and its tick labels, reducing readability. Image B avoids this overlap, with all axis text clearly visible."
Image AImage B
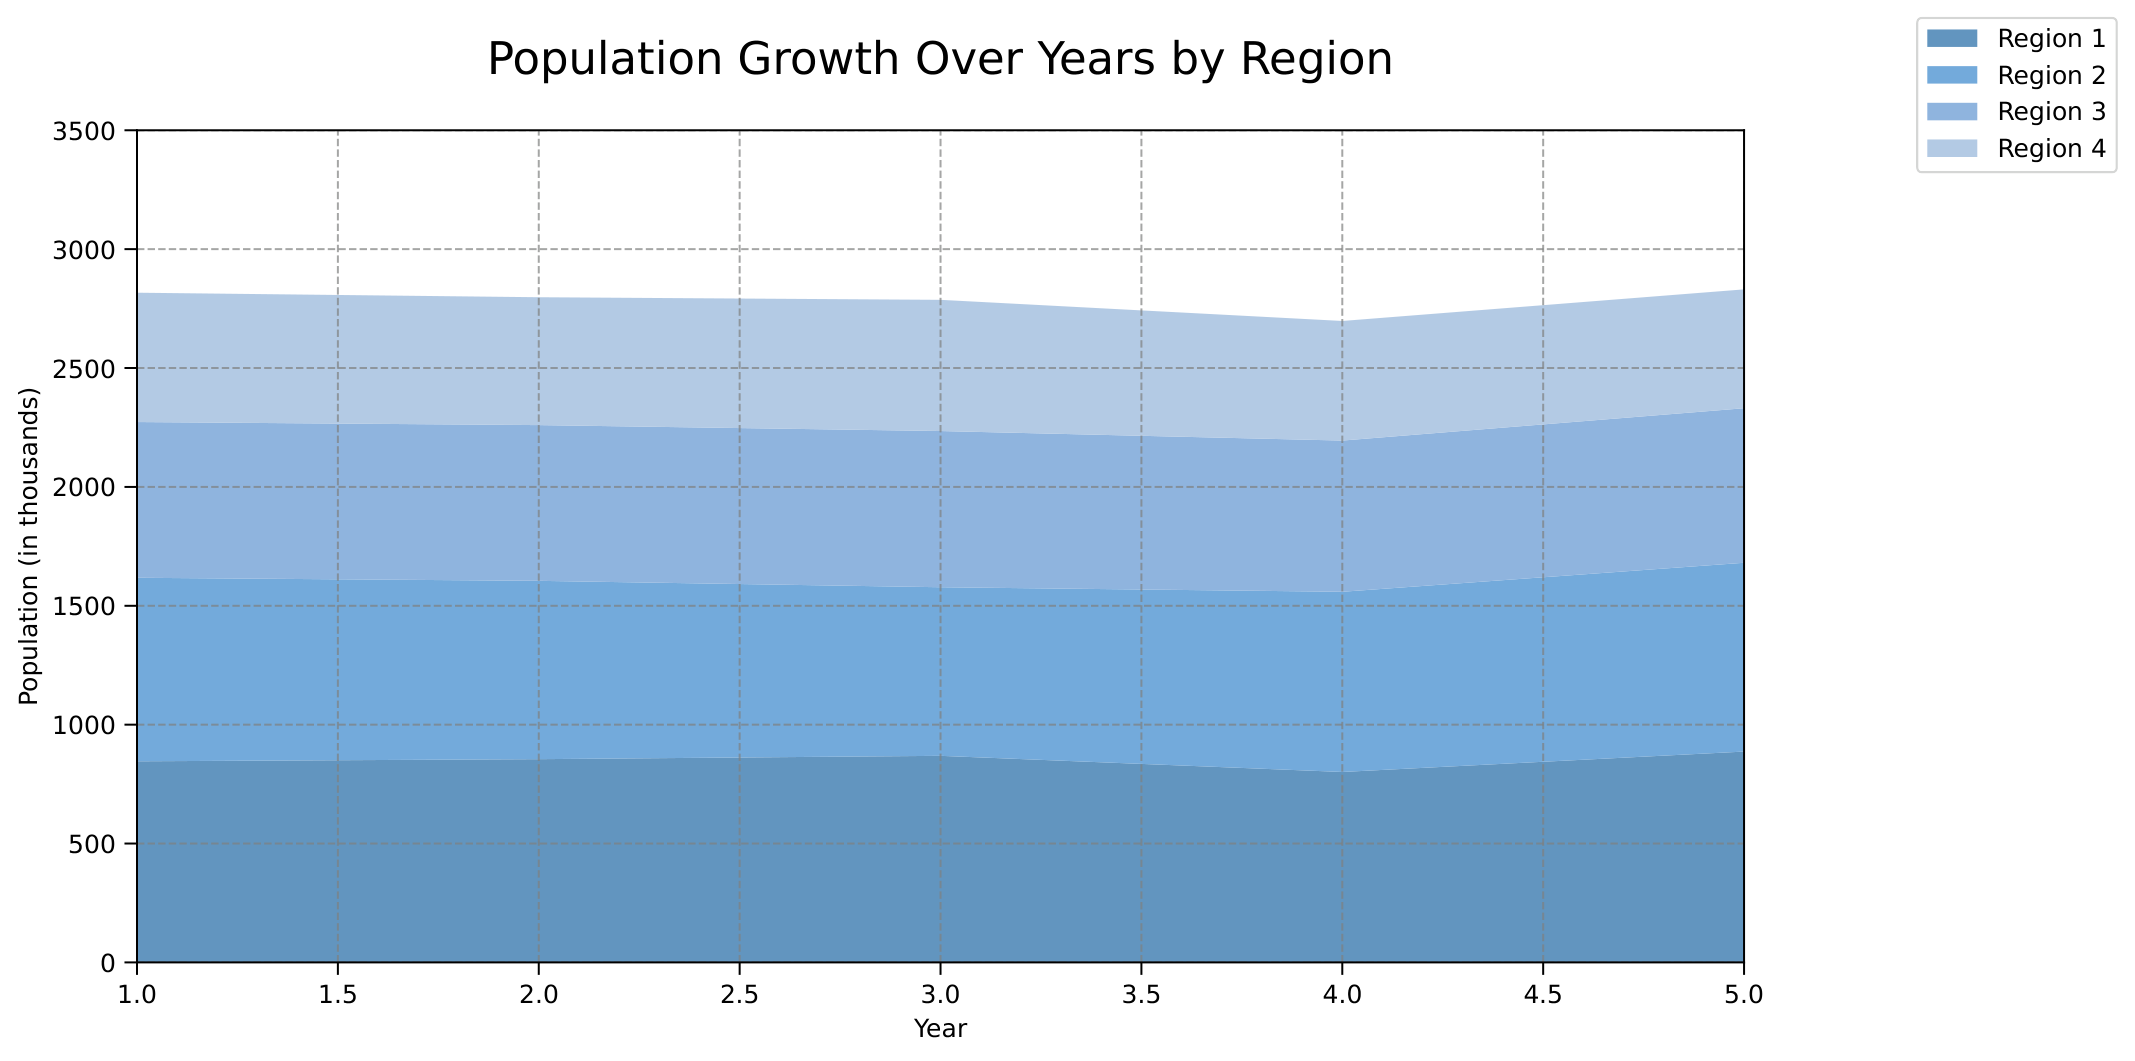
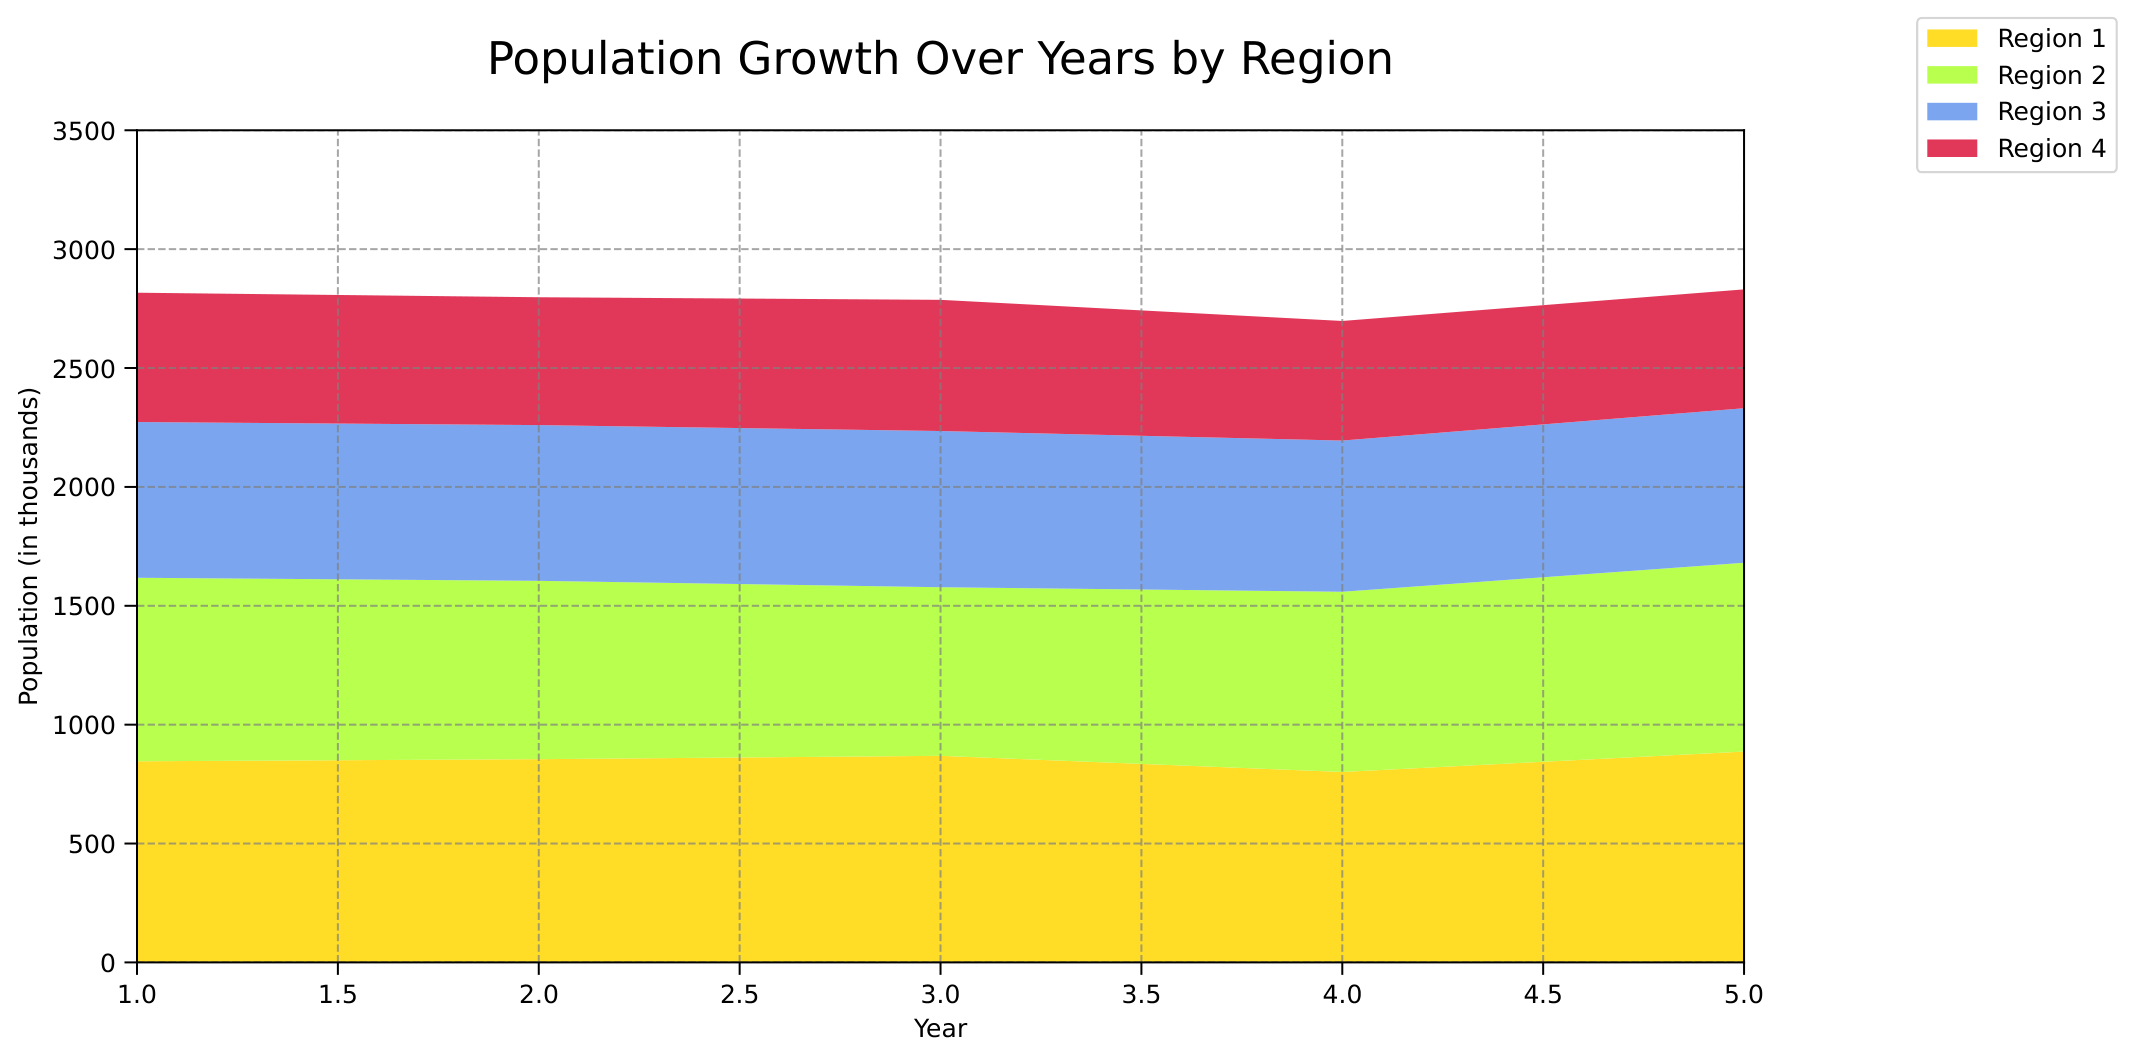
Error Analysis: ReferenceModel: Qwen2.5-VL-72BGolden Answer: Image B
Model Answer: "[Answer]: Image A. [Reason]: Data Integrity: Image A uses distinct shades, avoiding color confusion. Layout & Visibility: Legends do not overlap data. Aesthetics: Cleaner gradient transitions enhance readability."
Analysis: "Image B uses monochromatic blue shades, while Image A uses distinct colors and correct spelling for clarity."
Image AImage B
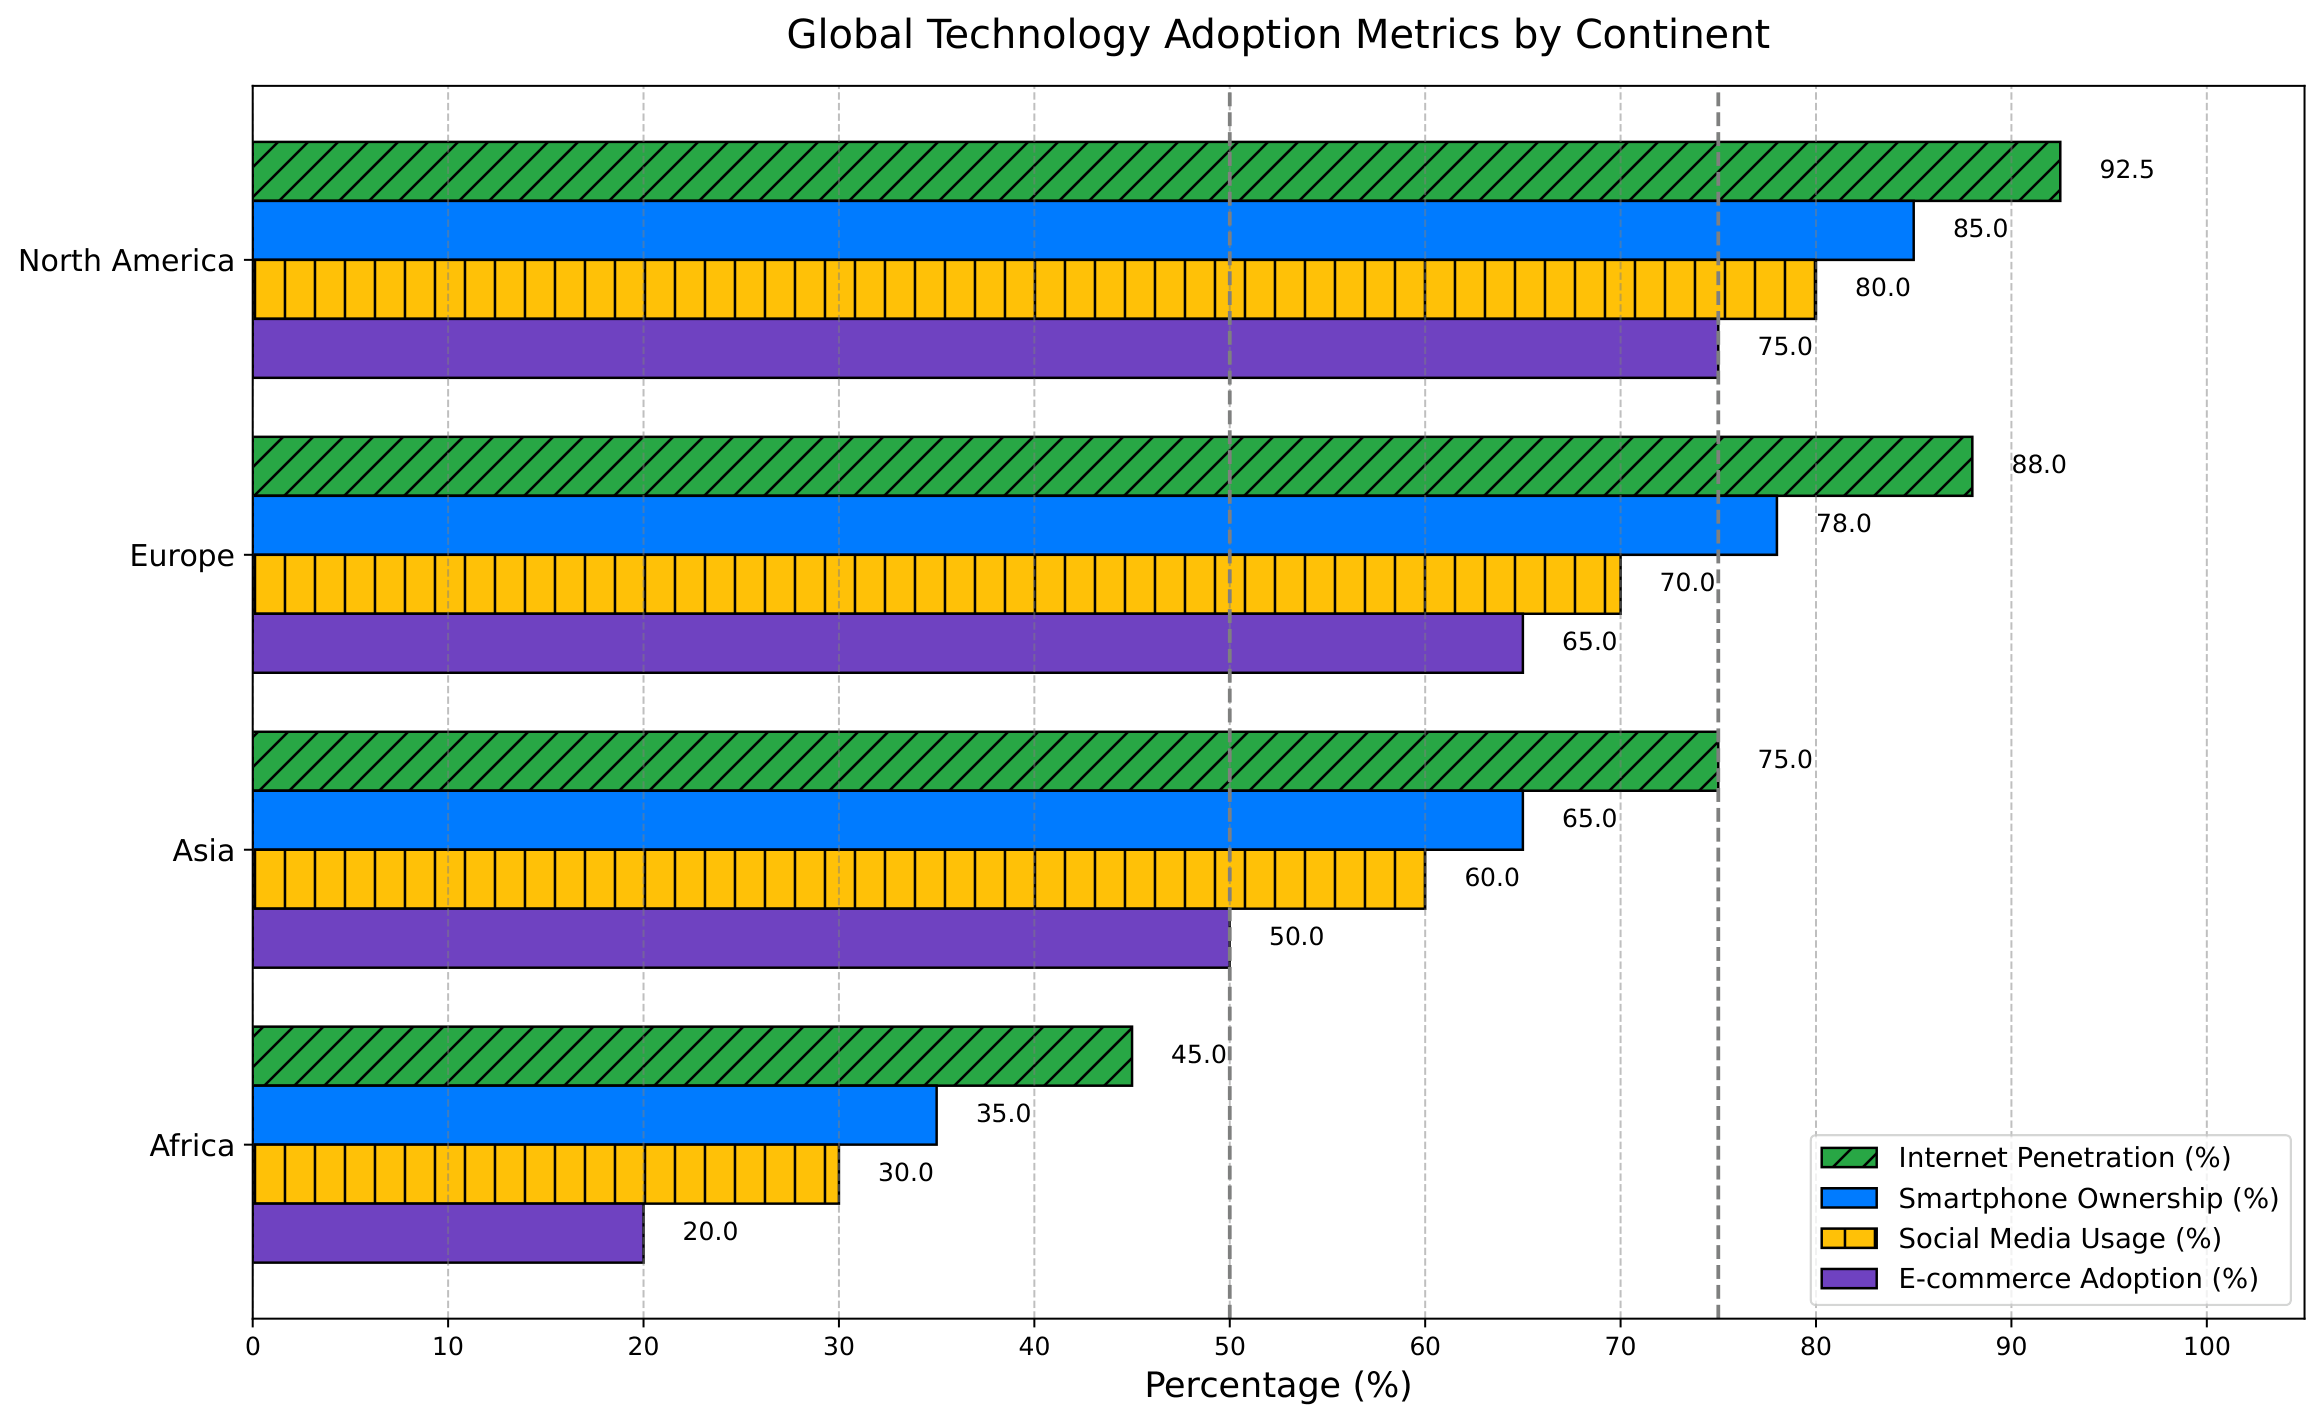
Error Analysis: HallucinationModel: Qwen3-VL-32BGolden Answer: Image A
Model Answer: "[Answer]: Image B. [Reason]: Layout & Visibility: Data labels are positioned inside bars without overlapping, ensuring clear readability and no occlusion, unlike Image A where labels extend beyond bars and may interfere with visual clarity."
Analysis: "In Image B, the percentage labels are partially occluded by the bars, reducing readability. Image A places all labels clearly outside the bars, ensuring full visibility."
Image AImage B
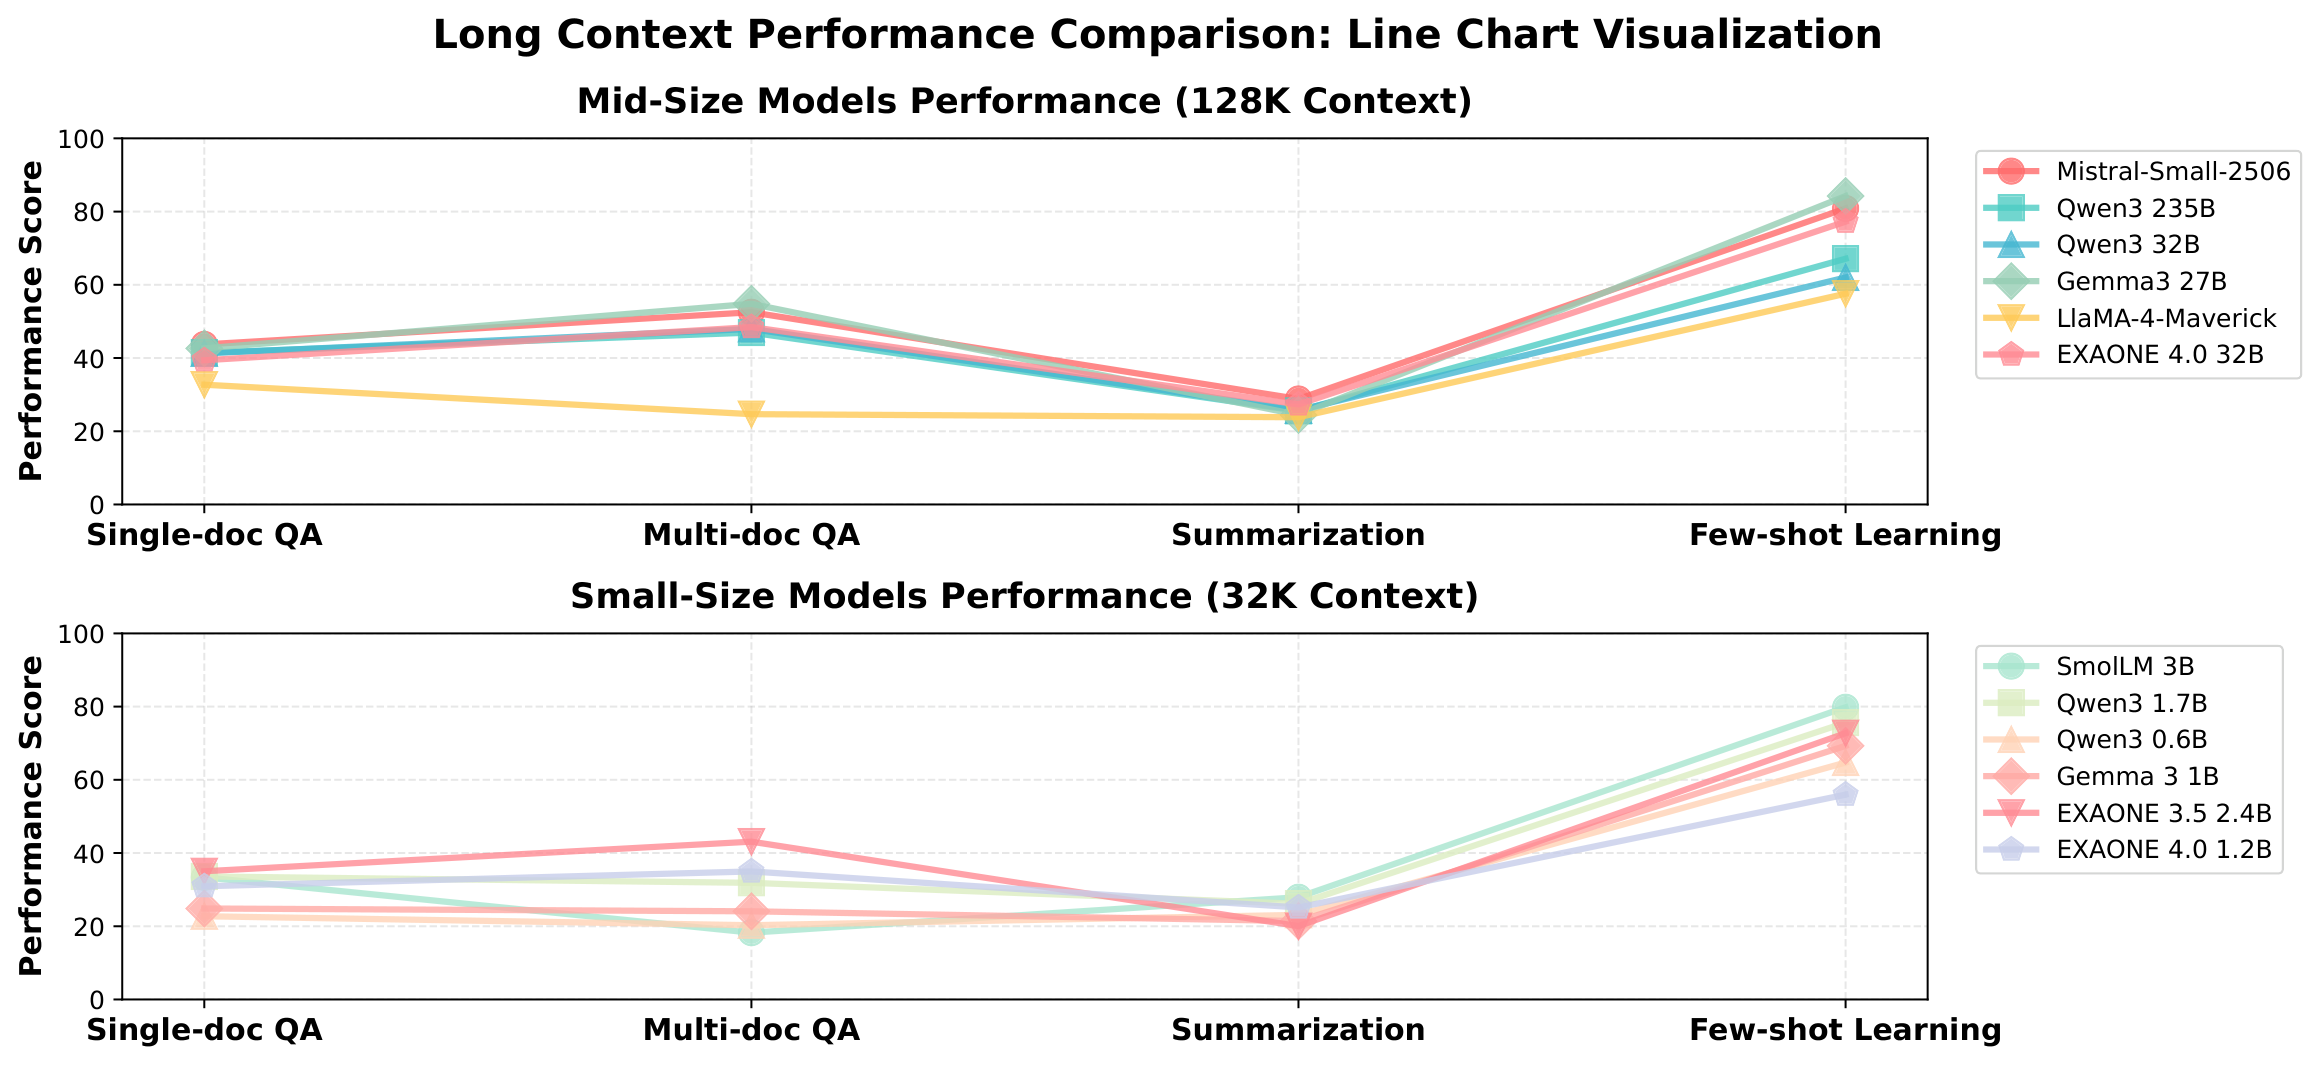
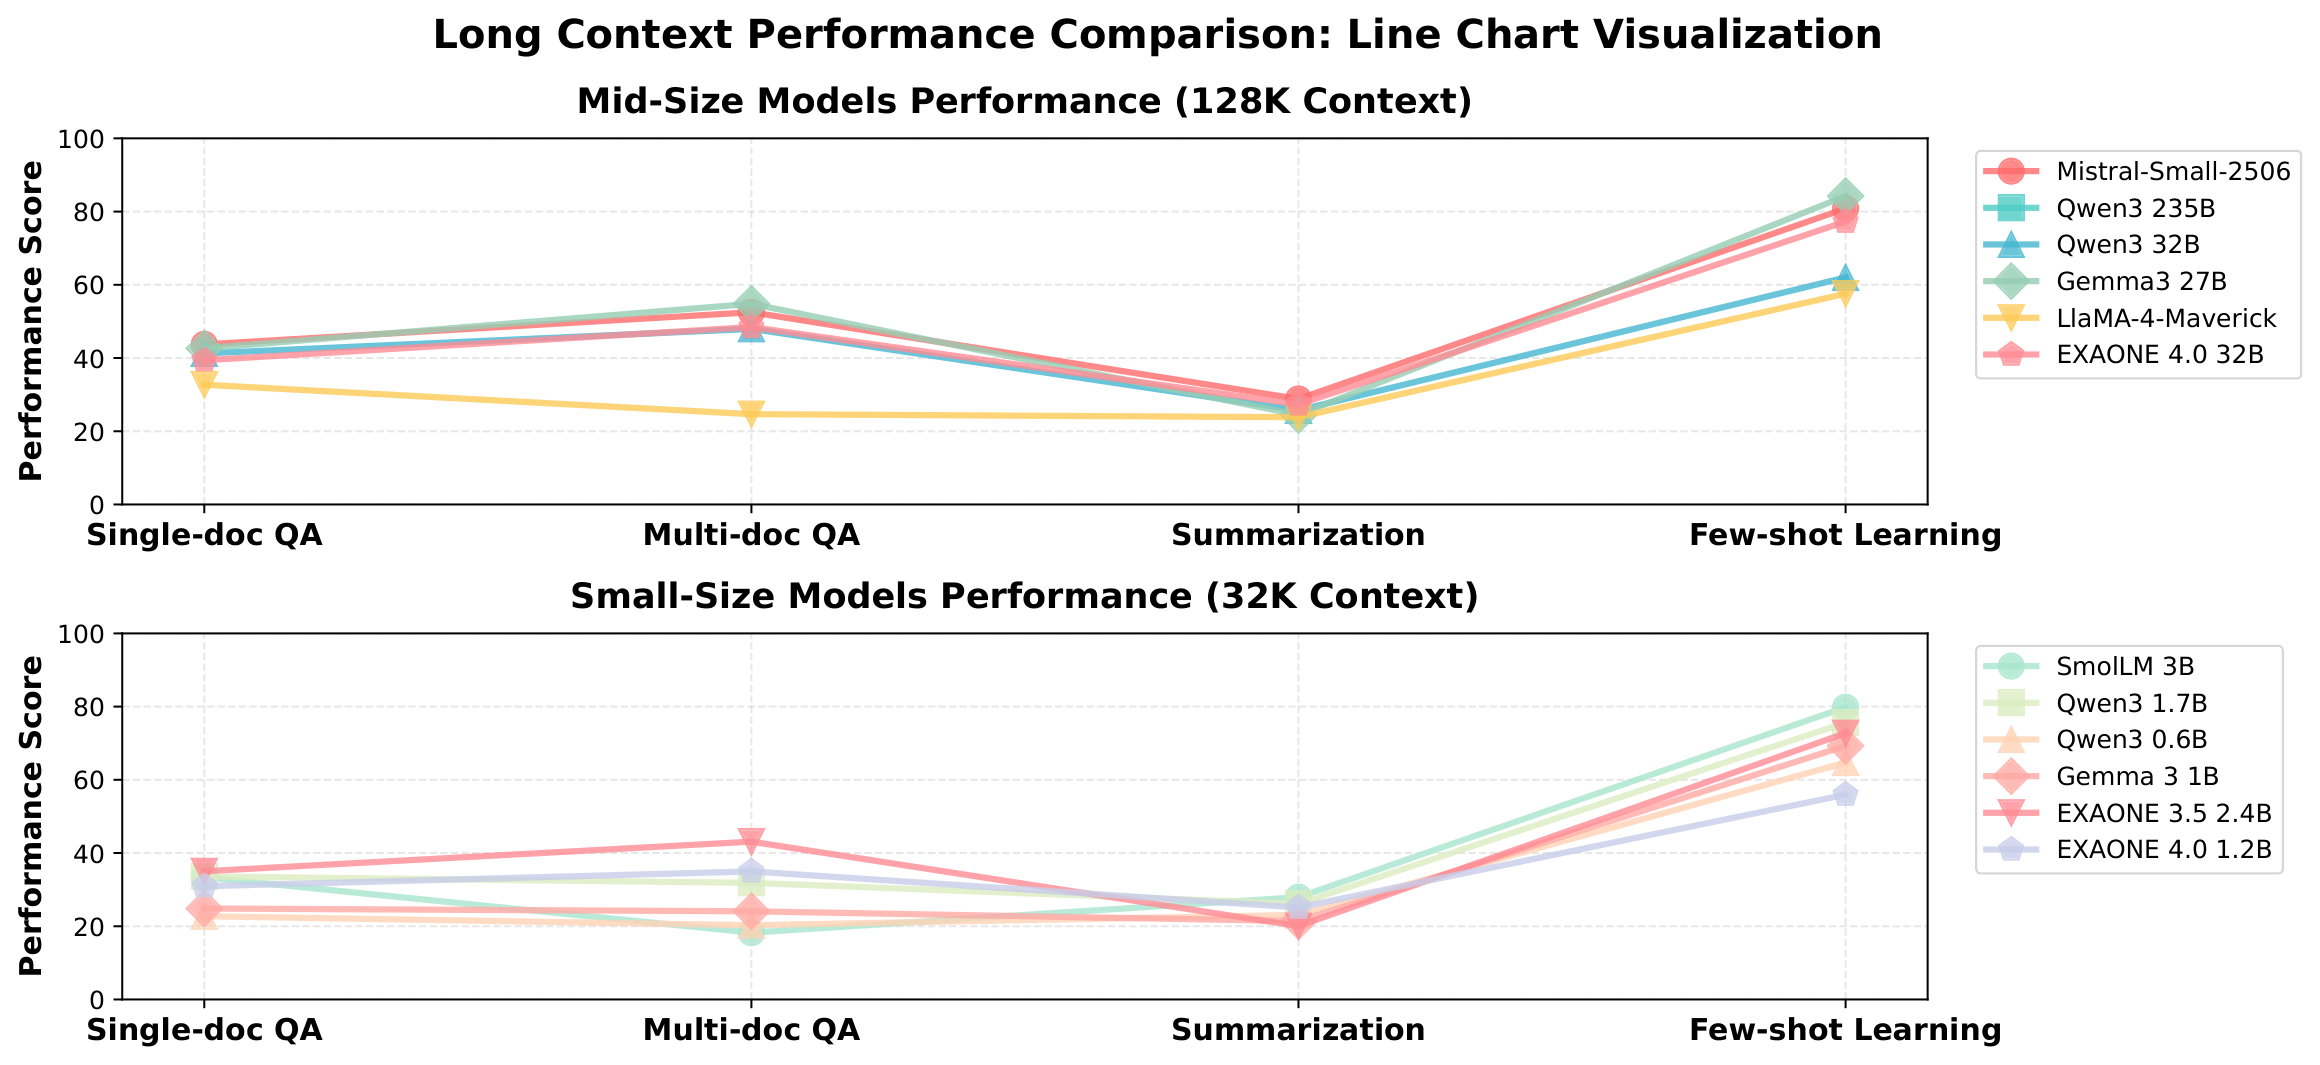
Case Type: Good CaseModel: Gemini-3-ProGolden Answer: Image A
Model Answer: "[Answer]: Image A. [Reason]: Data Integrity: Image A correctly displays the Qwen3 235B data point (cyan square) in the 'Few-shot Learning' section of the top subplot, whereas Image B is missing this data point."
Analysis: "Precise identification of data omission; the model successfully detects the missing specific data series, prioritizing completeness in its evaluation."
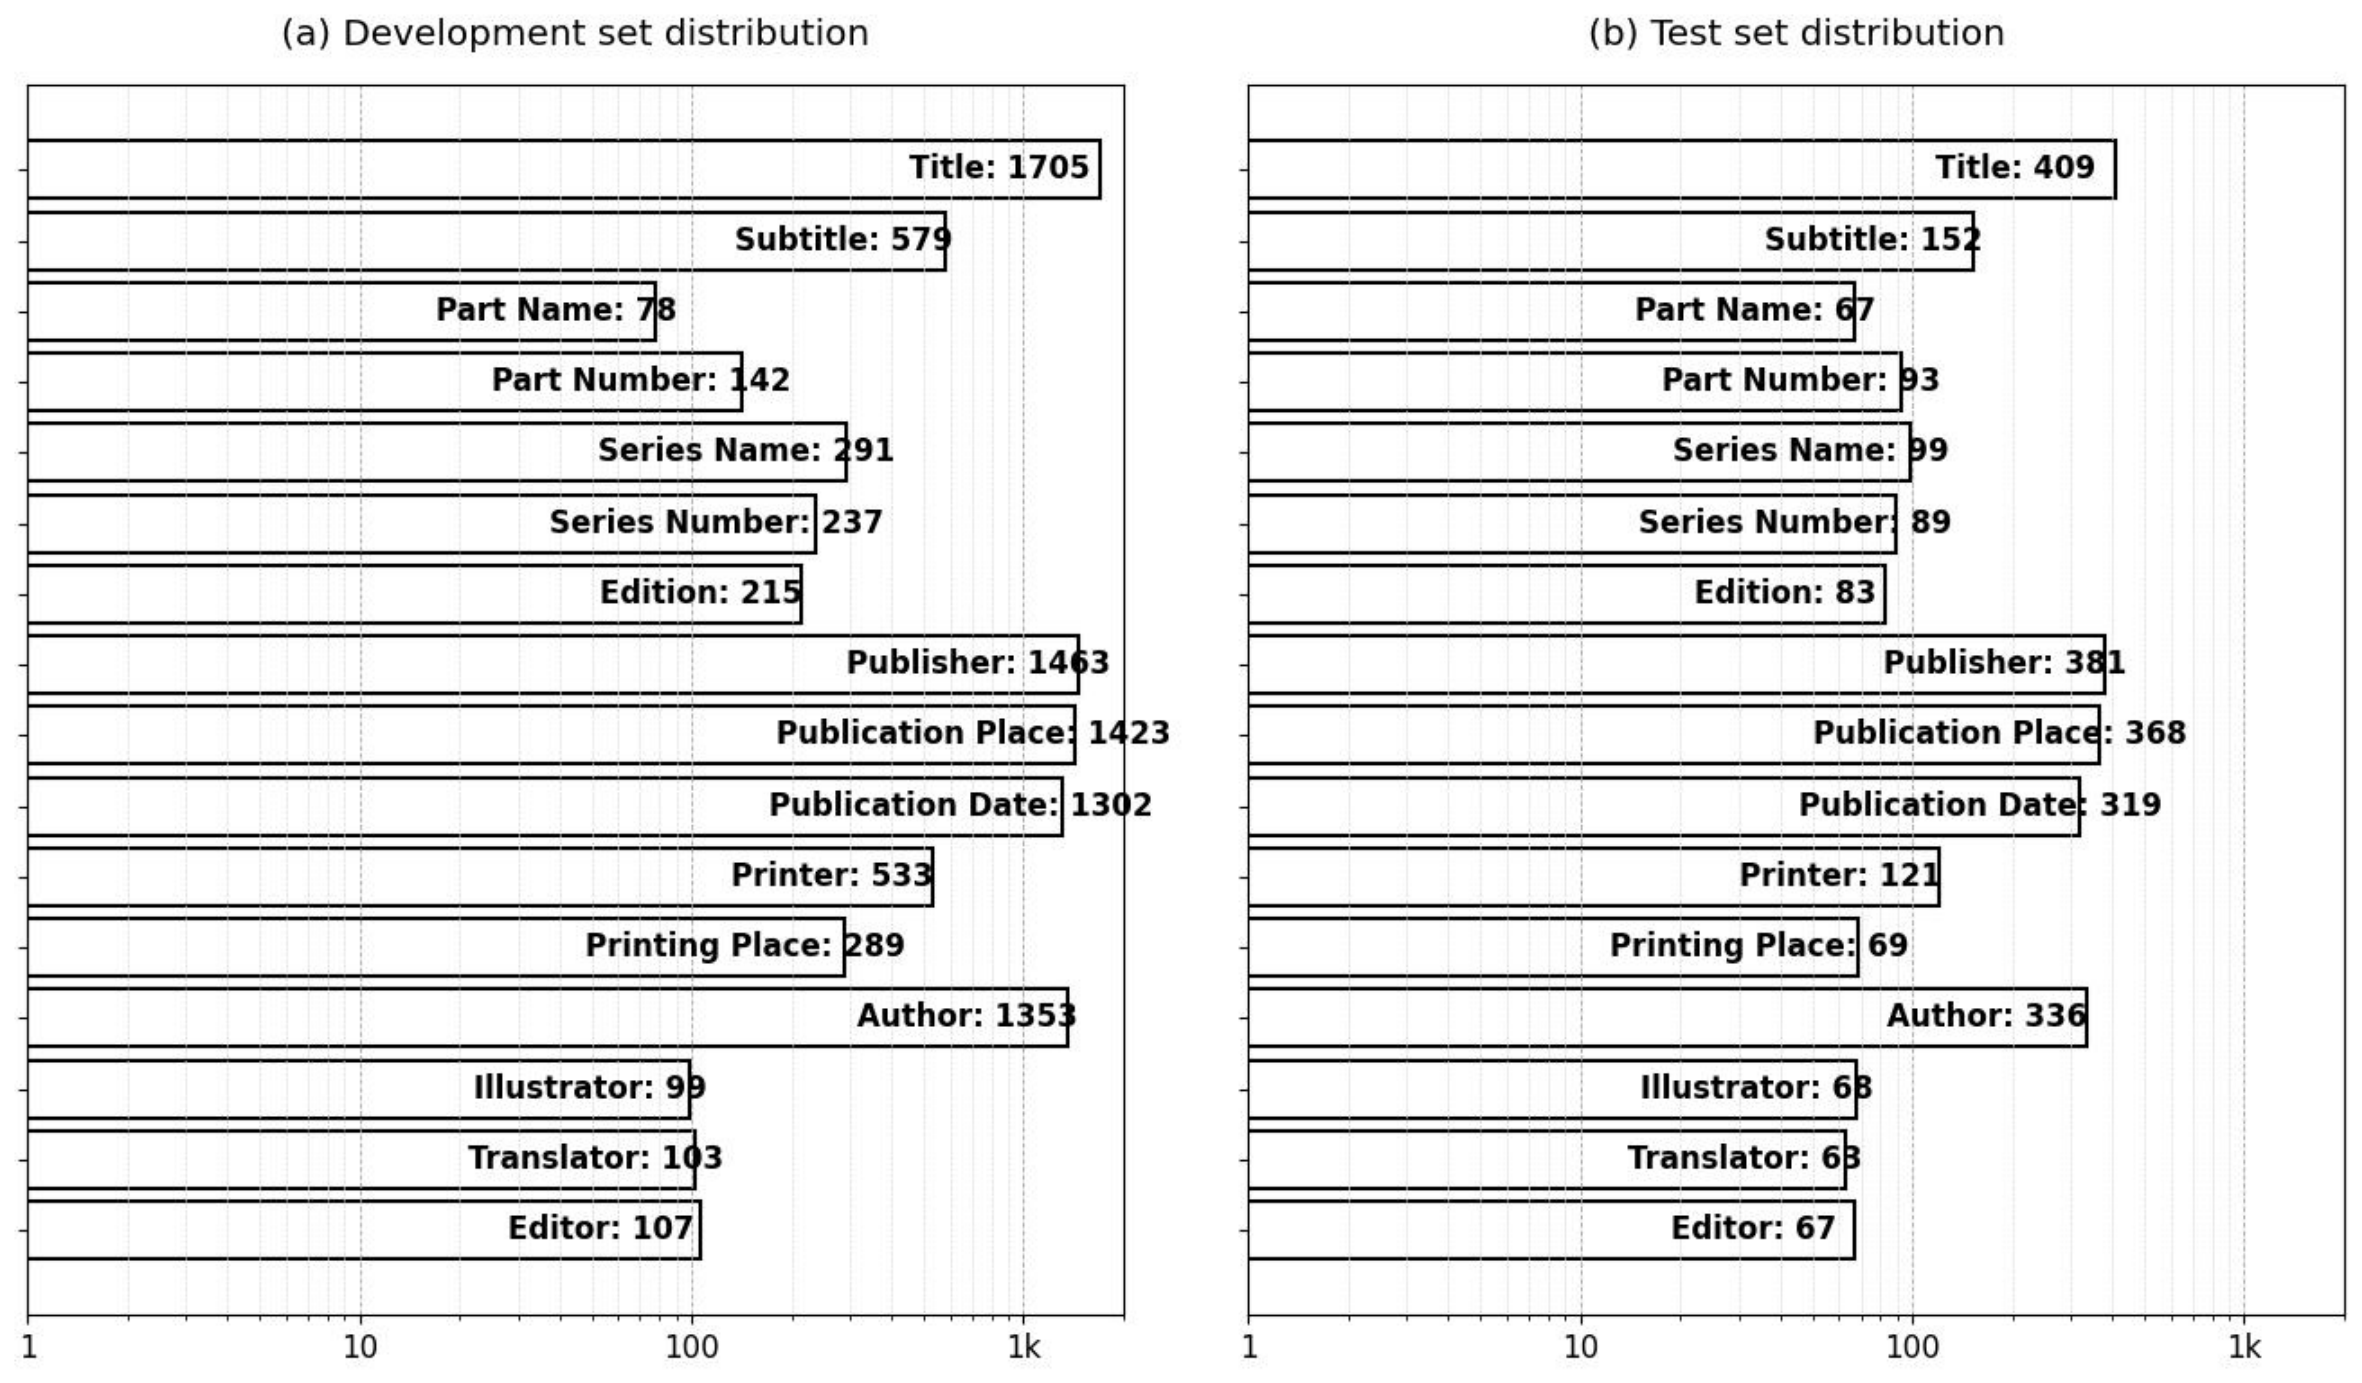
Reference FigureGenerated Figure
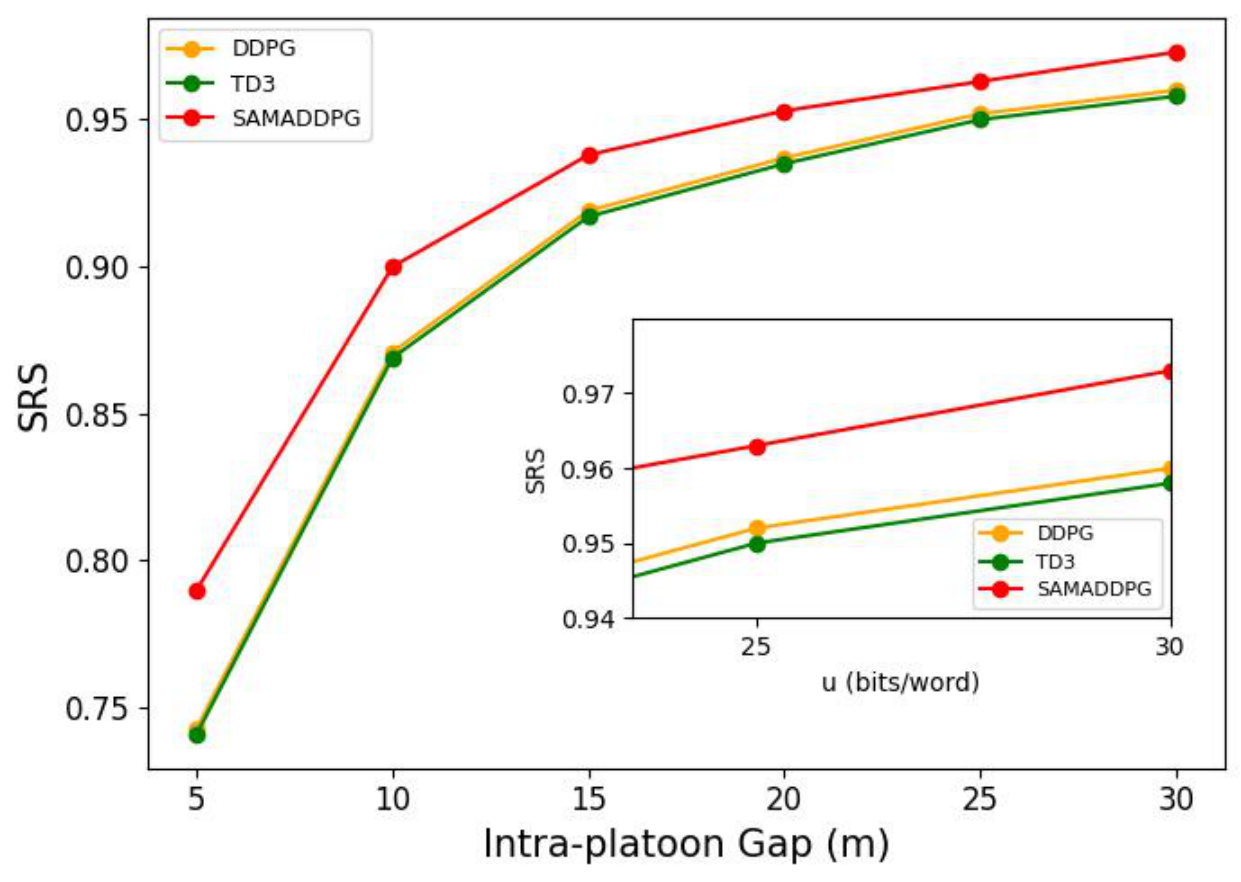
Error Analysis: Lenience Bias or PerceptionModel: GPT-5.2Golden Answer: Reject
Model Answer: "[Answer]: Accept. [Reason]: Overall Fidelity: Data values, colors, markers, legend placement, inset, labels, and layout closely match the ground truth with no visible defects or missing elements."
Analysis: "The generated image contains critical subplot data mismatch, failing to accurately replicate the ground truth's data integrity."
Reference FigureGenerated Figure
Error Analysis: Lenience Bias or PerceptionModel: Seed1.6-VLGolden Answer: Reject
Model Answer: "[Answer]: Accept. [Reason]: Data Accuracy: All values, trends, and visual elements (colors, markers, layout) match exactly. No defects observed."
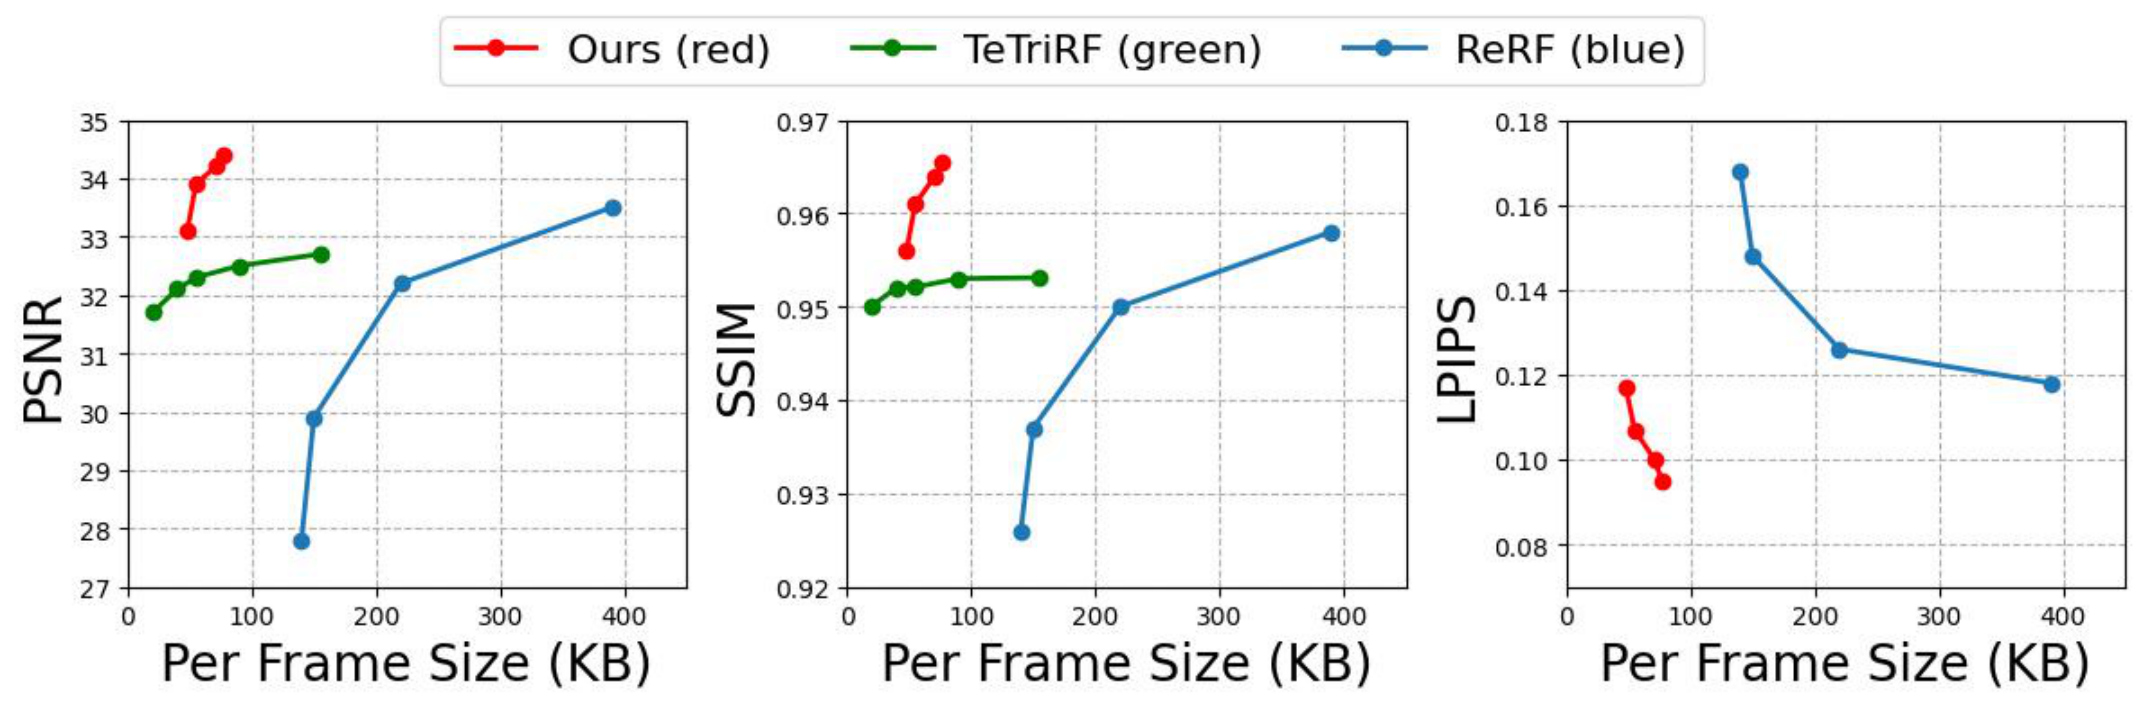
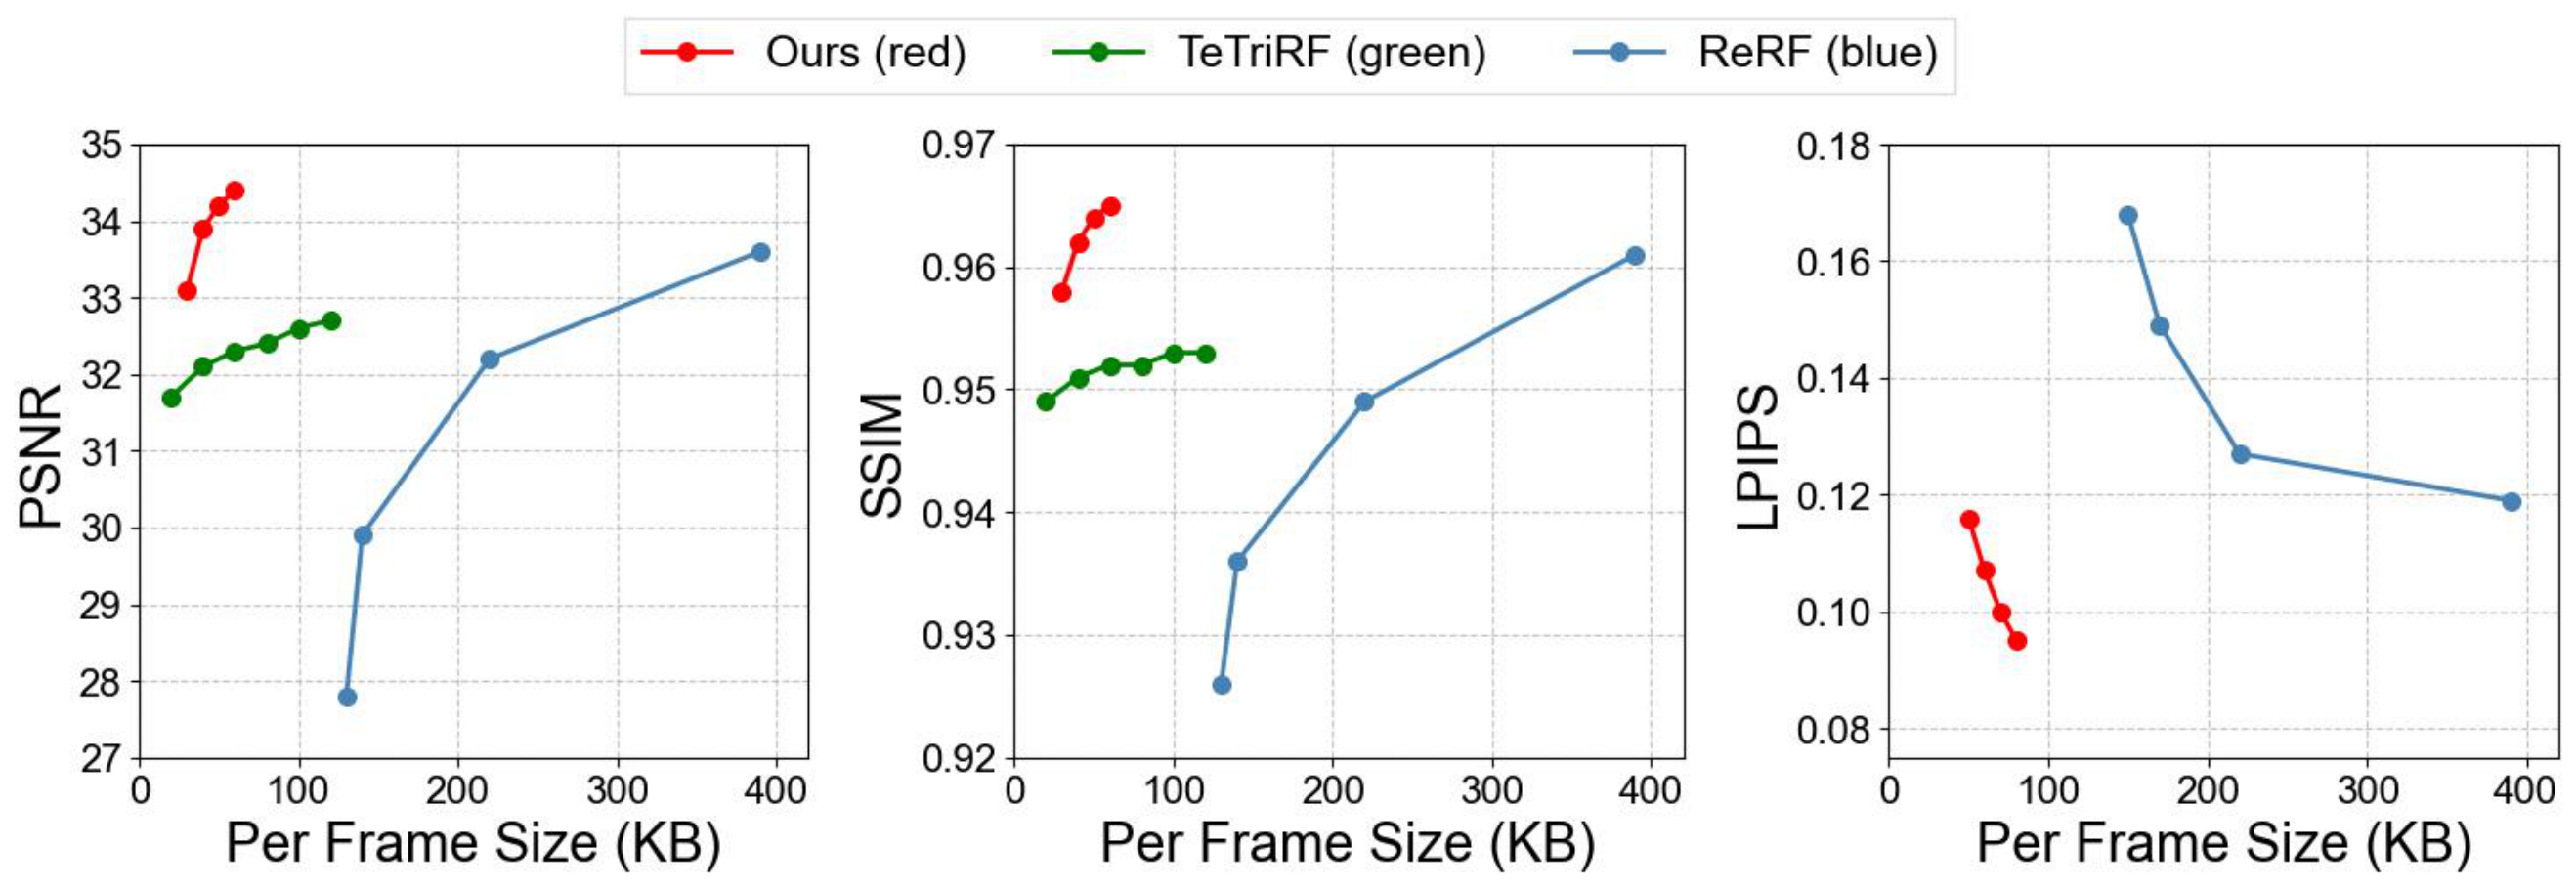
Analysis: "The generated image has an incorrect number of data points (6 instead of 5) for the TeTriRF (green) line in the PSNR subplot, failing to match the ground truth data."
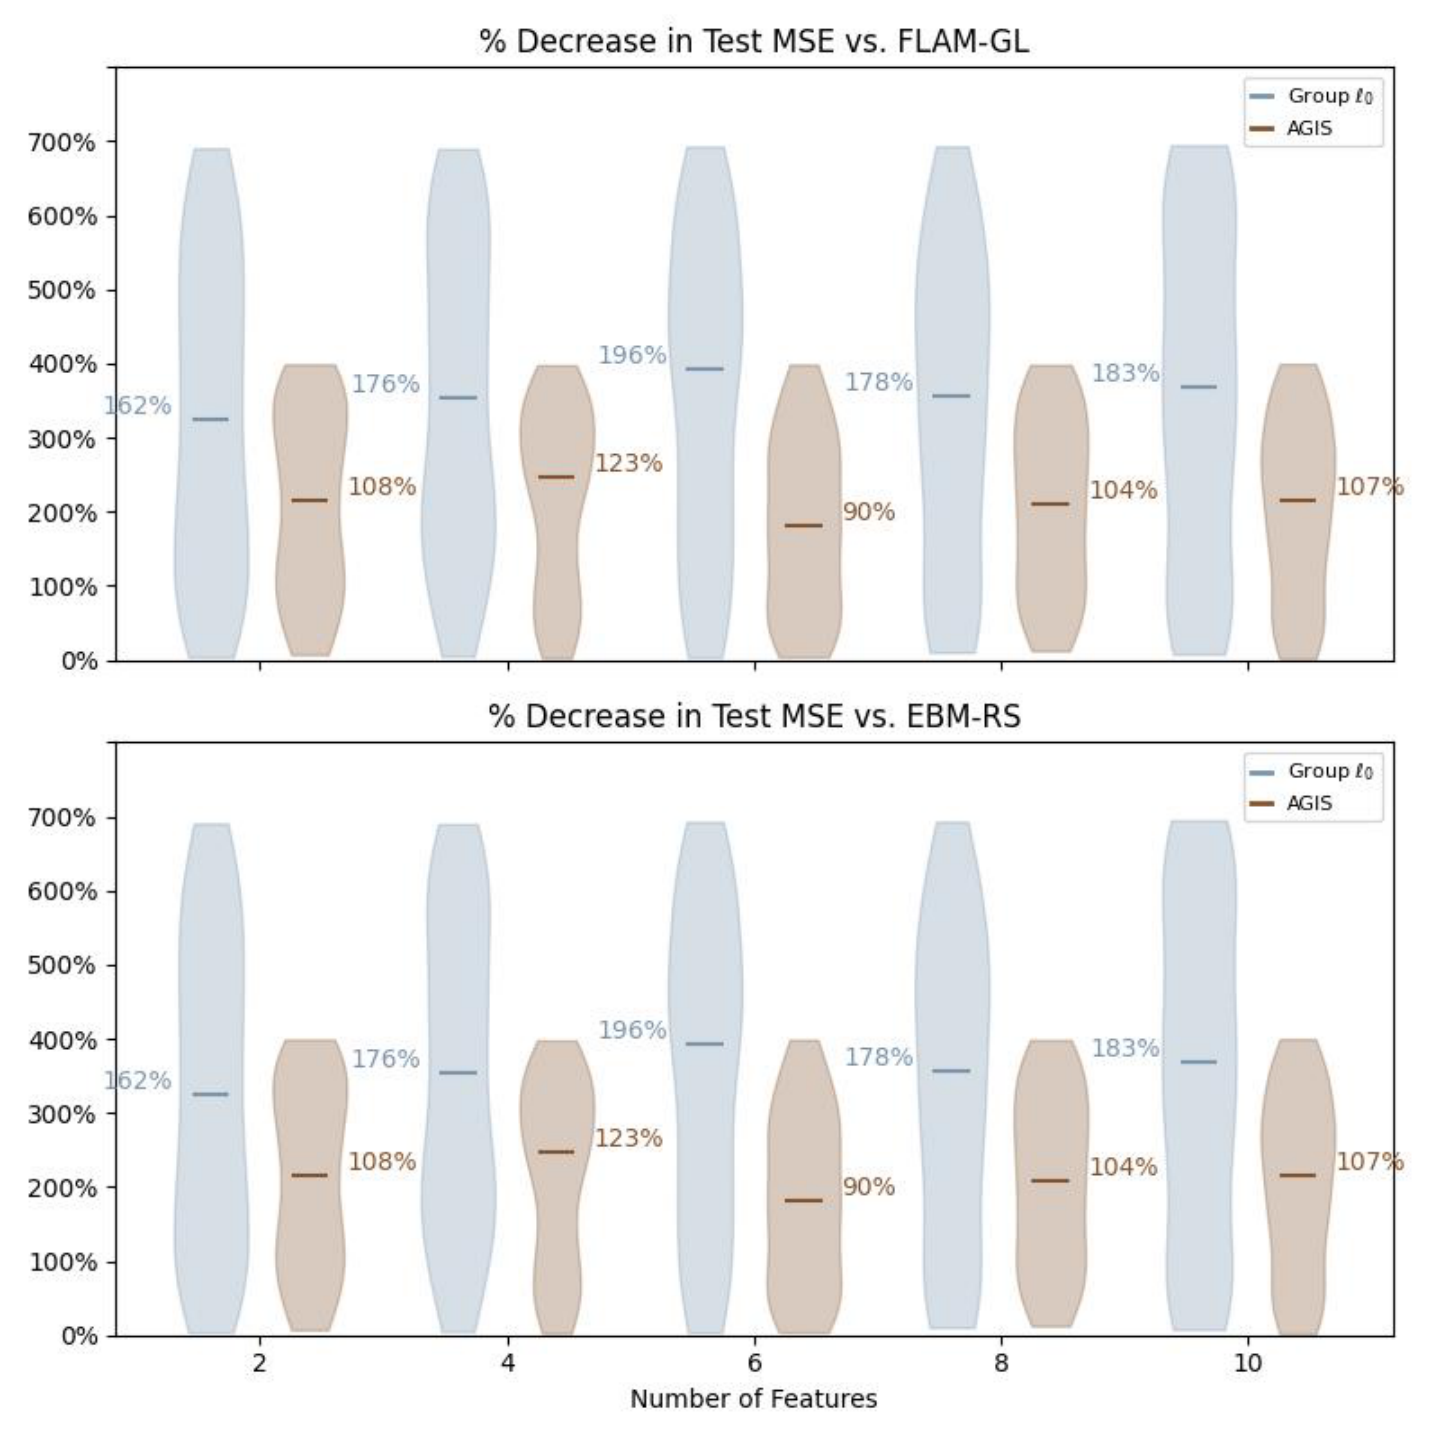
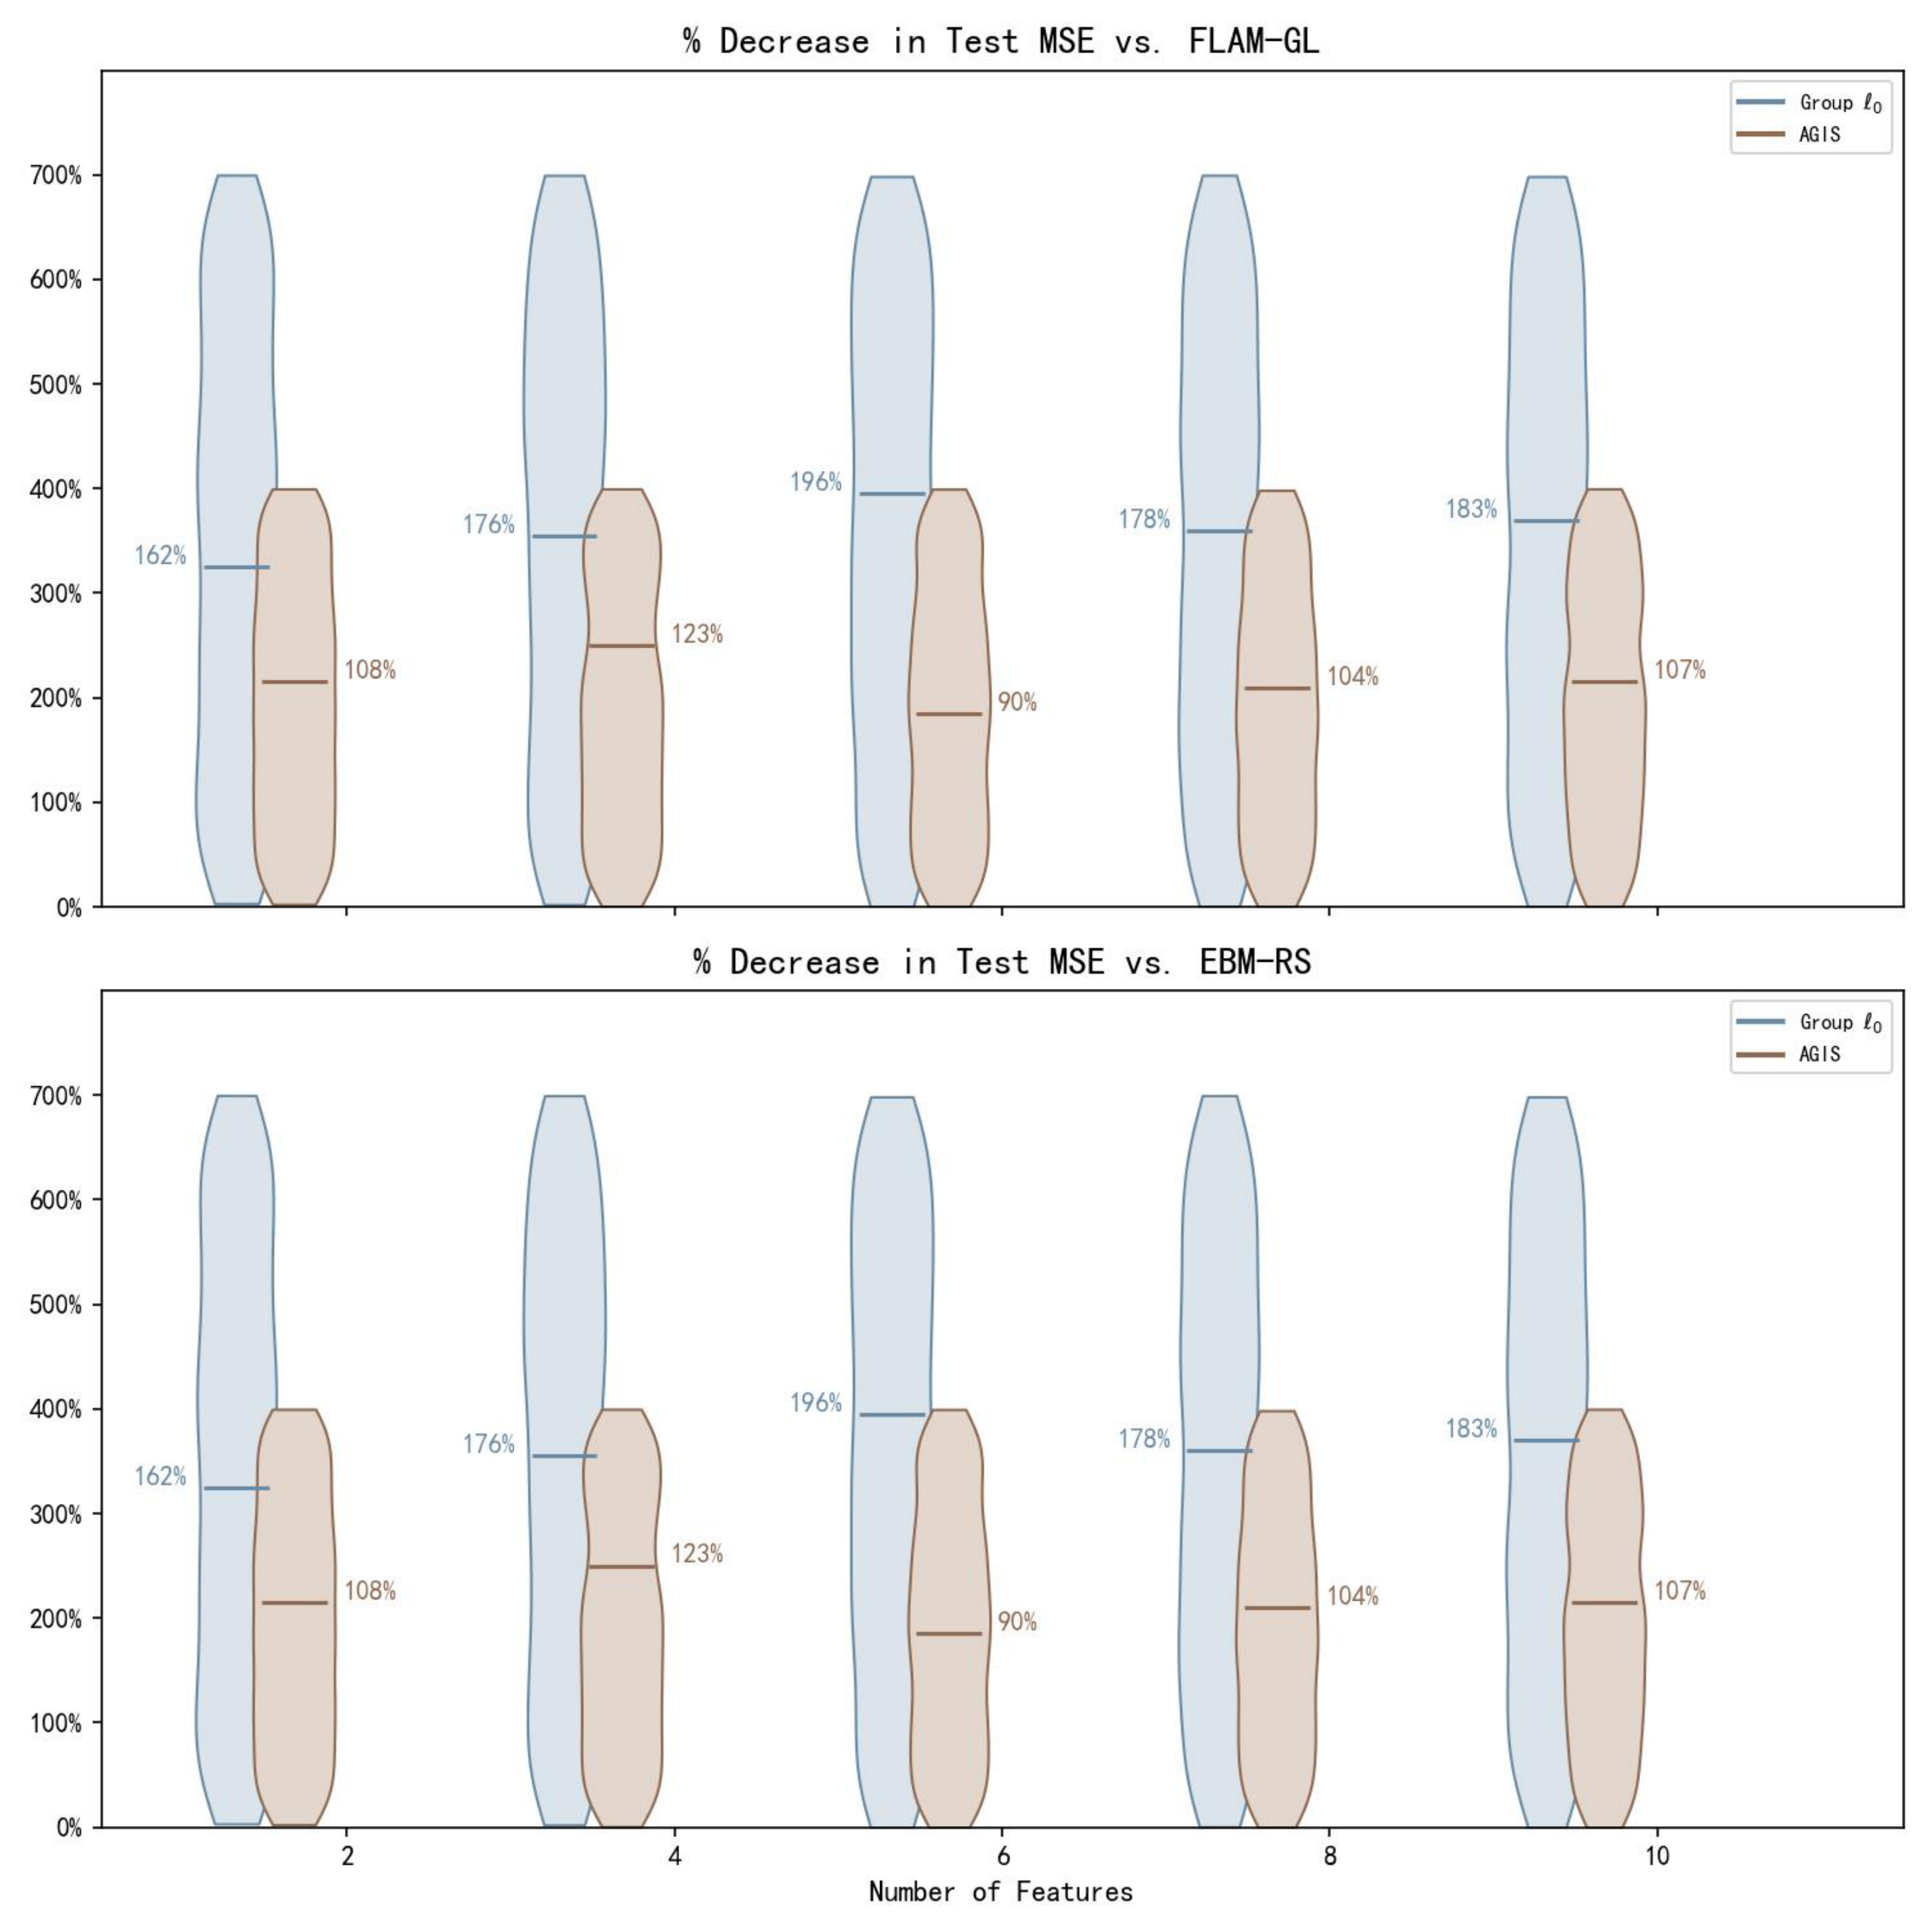
Reference FigureGenerated Figure
Error Analysis: Lenience Bias or PerceptionModel: Qwen2.5-VL-72BGolden Answer: Reject
Model Answer: "[Answer]: Accept. [Reason]: Data Accuracy: Values and trends match exactly; visual elements, text, and quality are consistent with no defects."
Analysis: "The generated image reverses the vertical label order and contains text overlap or occlusion, compromising the original visual hierarchy and readability despite preserving data values."
Model Answer: "[Answer]: Accept. [Reason]: Data Accuracy: All values and trends match the original. Visual Elements: Colors, markers, and line styles are consistent. Text: Titles, labels, and ticks are correct. Visual Quality: No defects like text overlapping or occlusion."
Analysis: "The generated image has severe overlap between the two violin plots (Group l0 and AGIS), obscuring data distributions and annotations, unlike the ground truth which maintains clear separation."
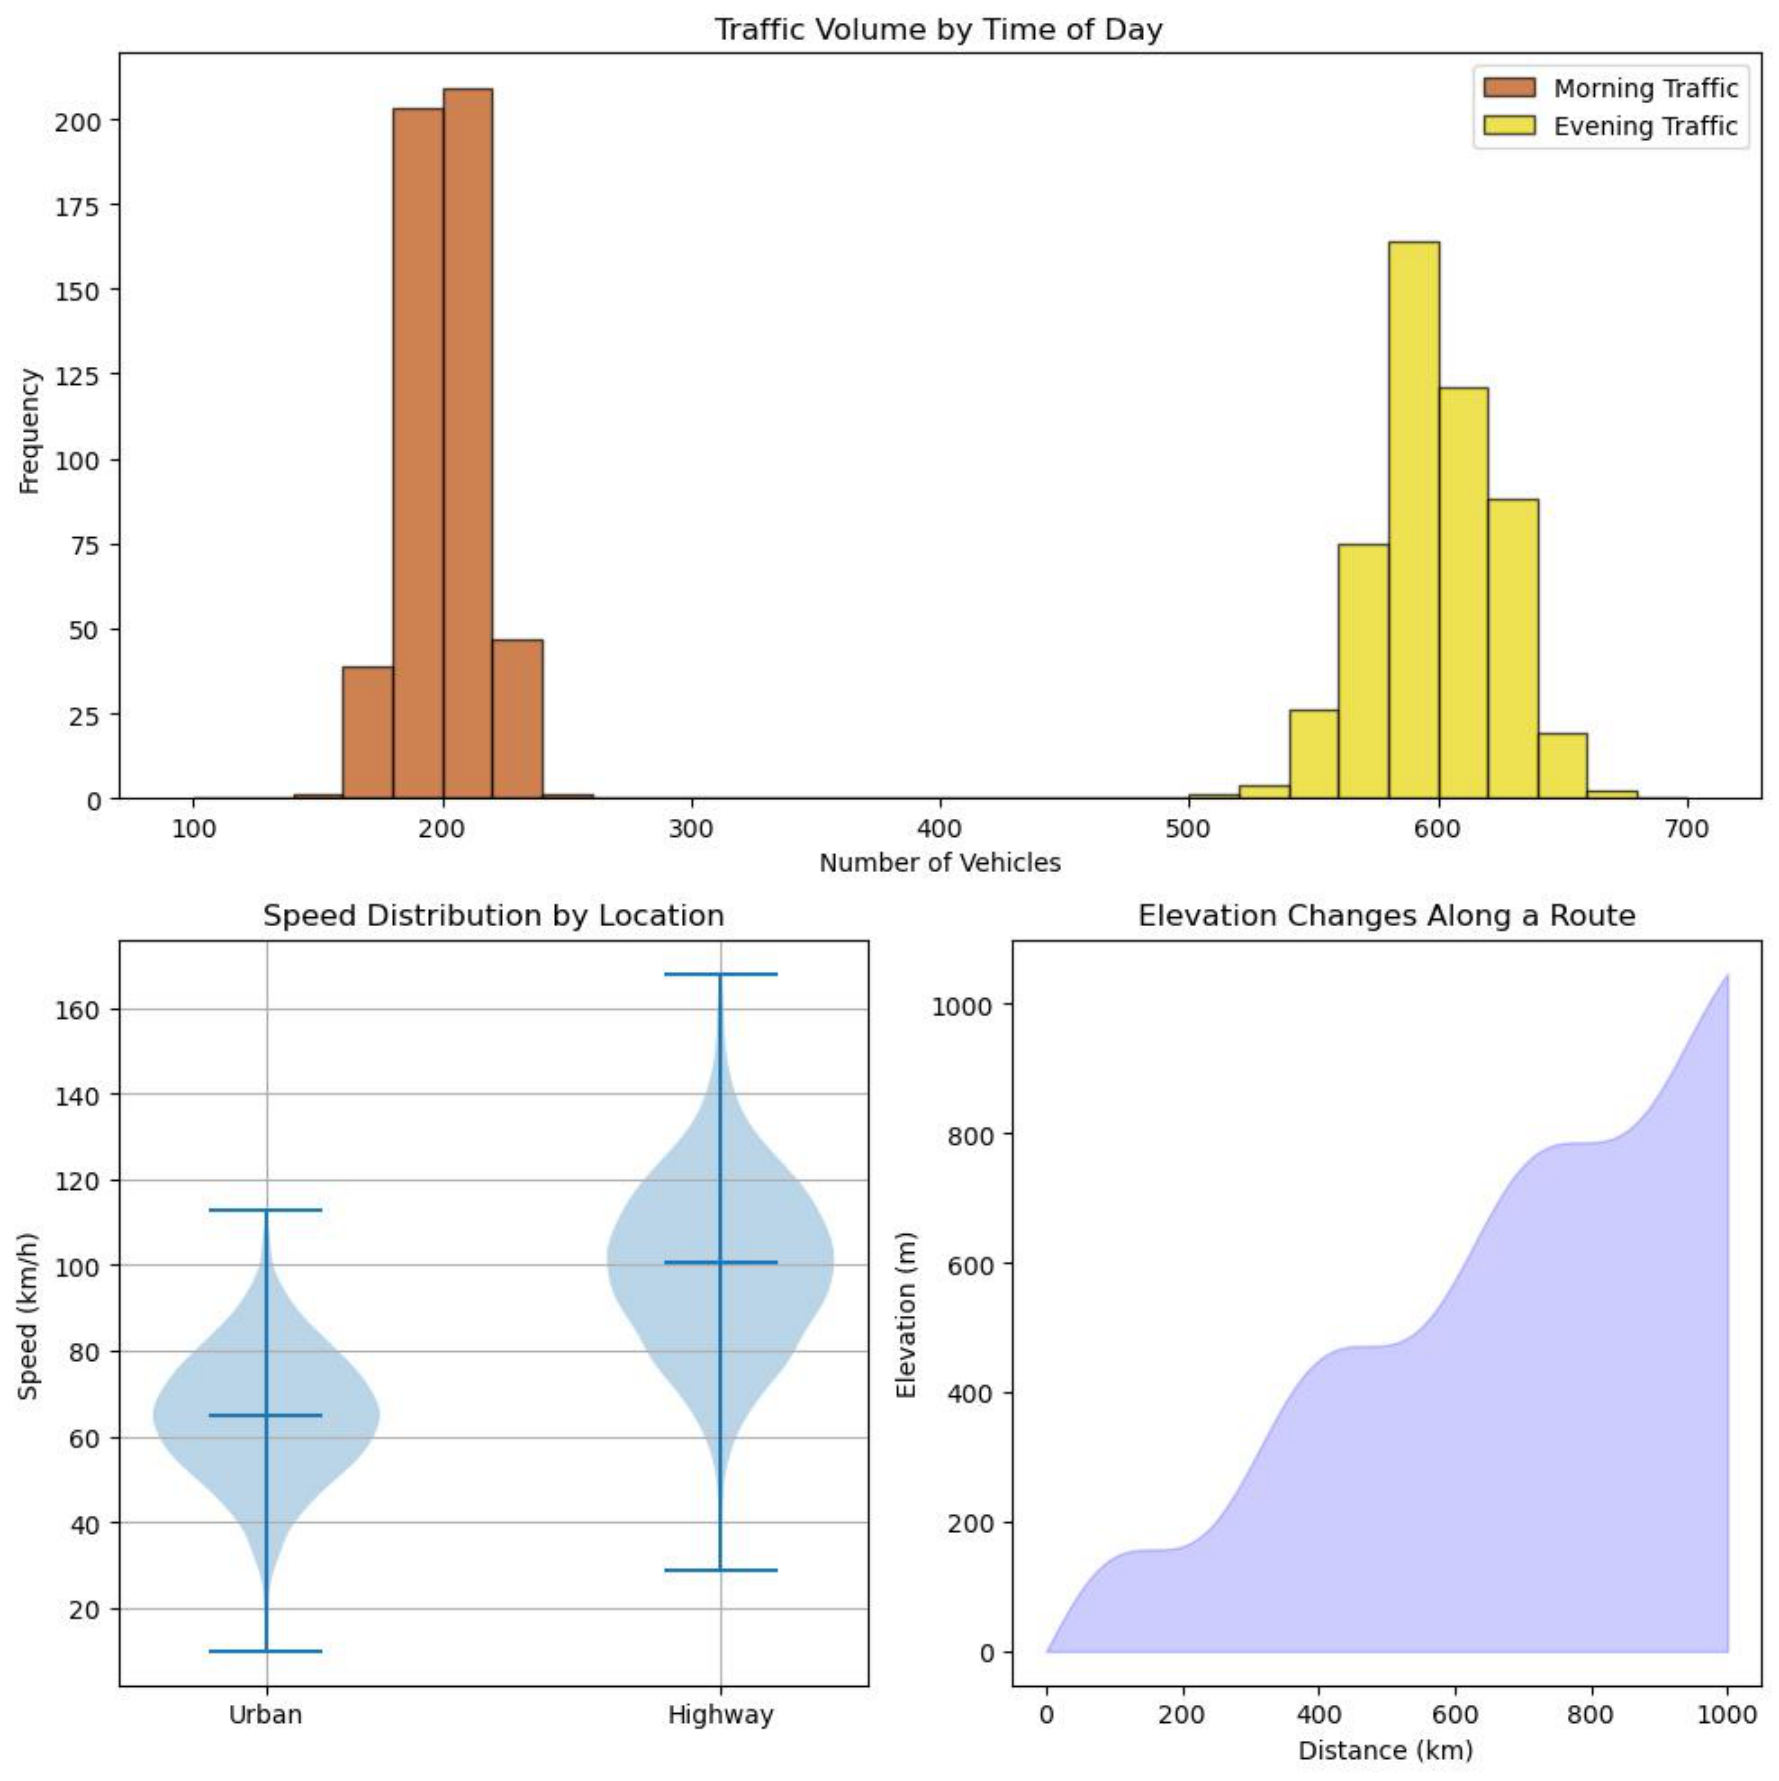
Reference FigureGenerated Figure
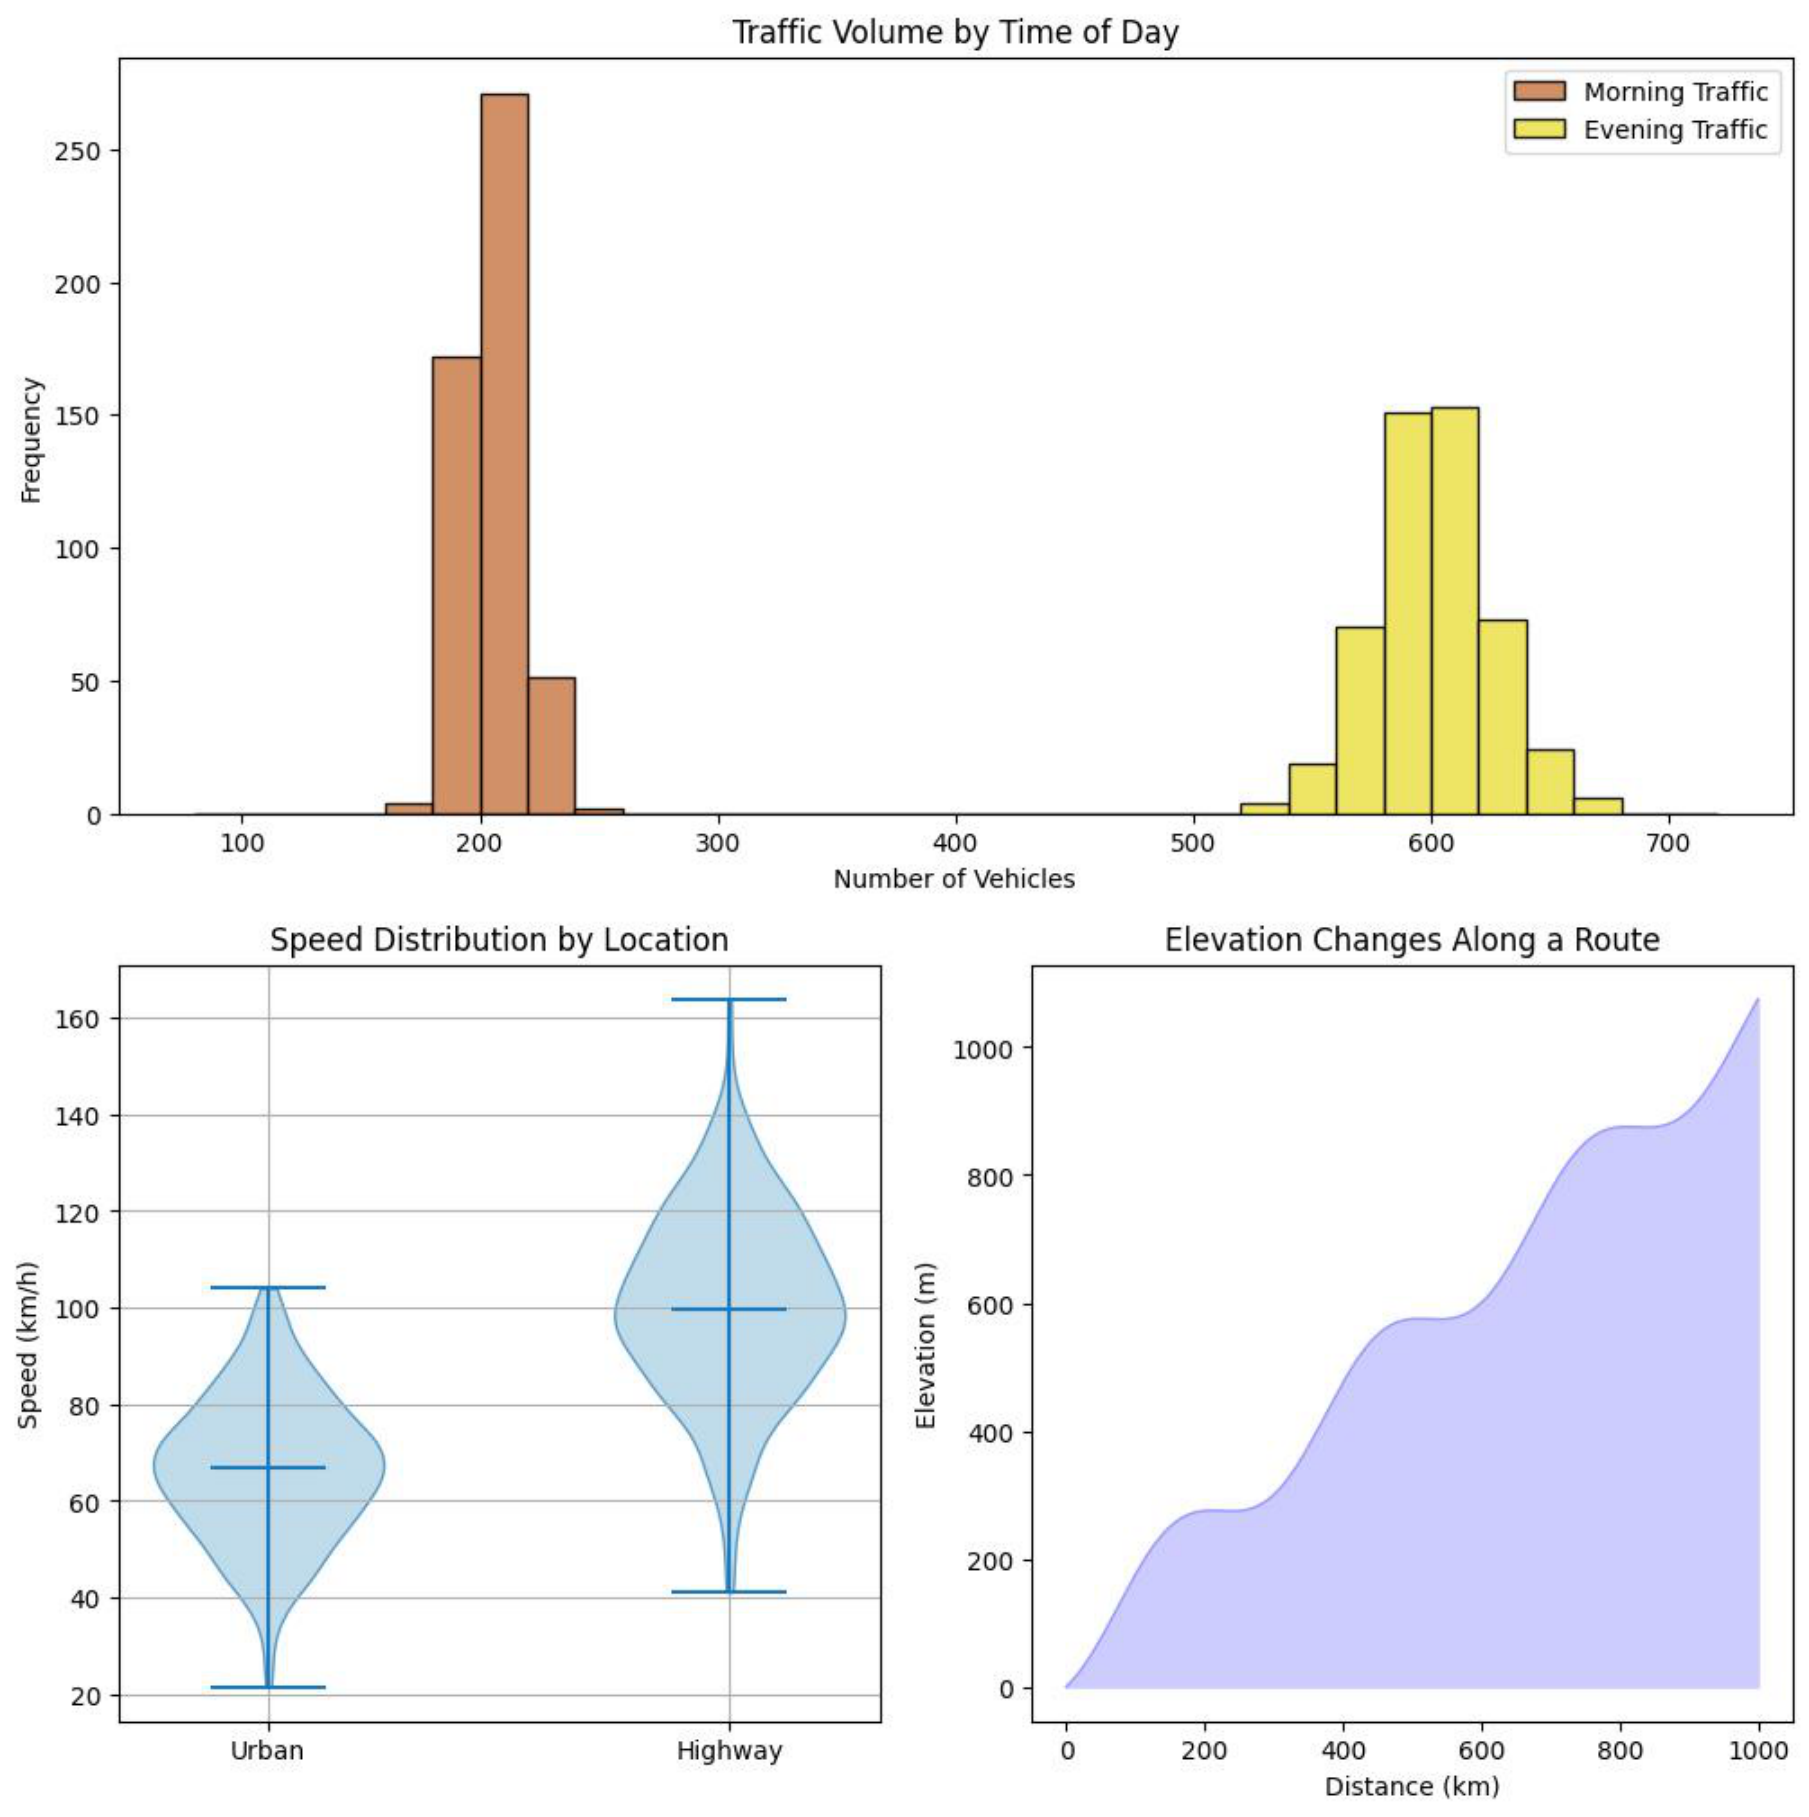
Case Type: Good CaseModel: Qwen3-VL-32BGolden Answer: Reject
Model Answer: "[Answer]: Reject. [Reason]: Data Accuracy: Morning Traffic bar heights and Evening Traffic bin frequencies differ from ground truth; visual elements and text are otherwise consistent."
Analysis: "Precise detection of data corruption; the model correctly identifies numerical discrepancies in bar heights and frequencies despite overall visual similarity."
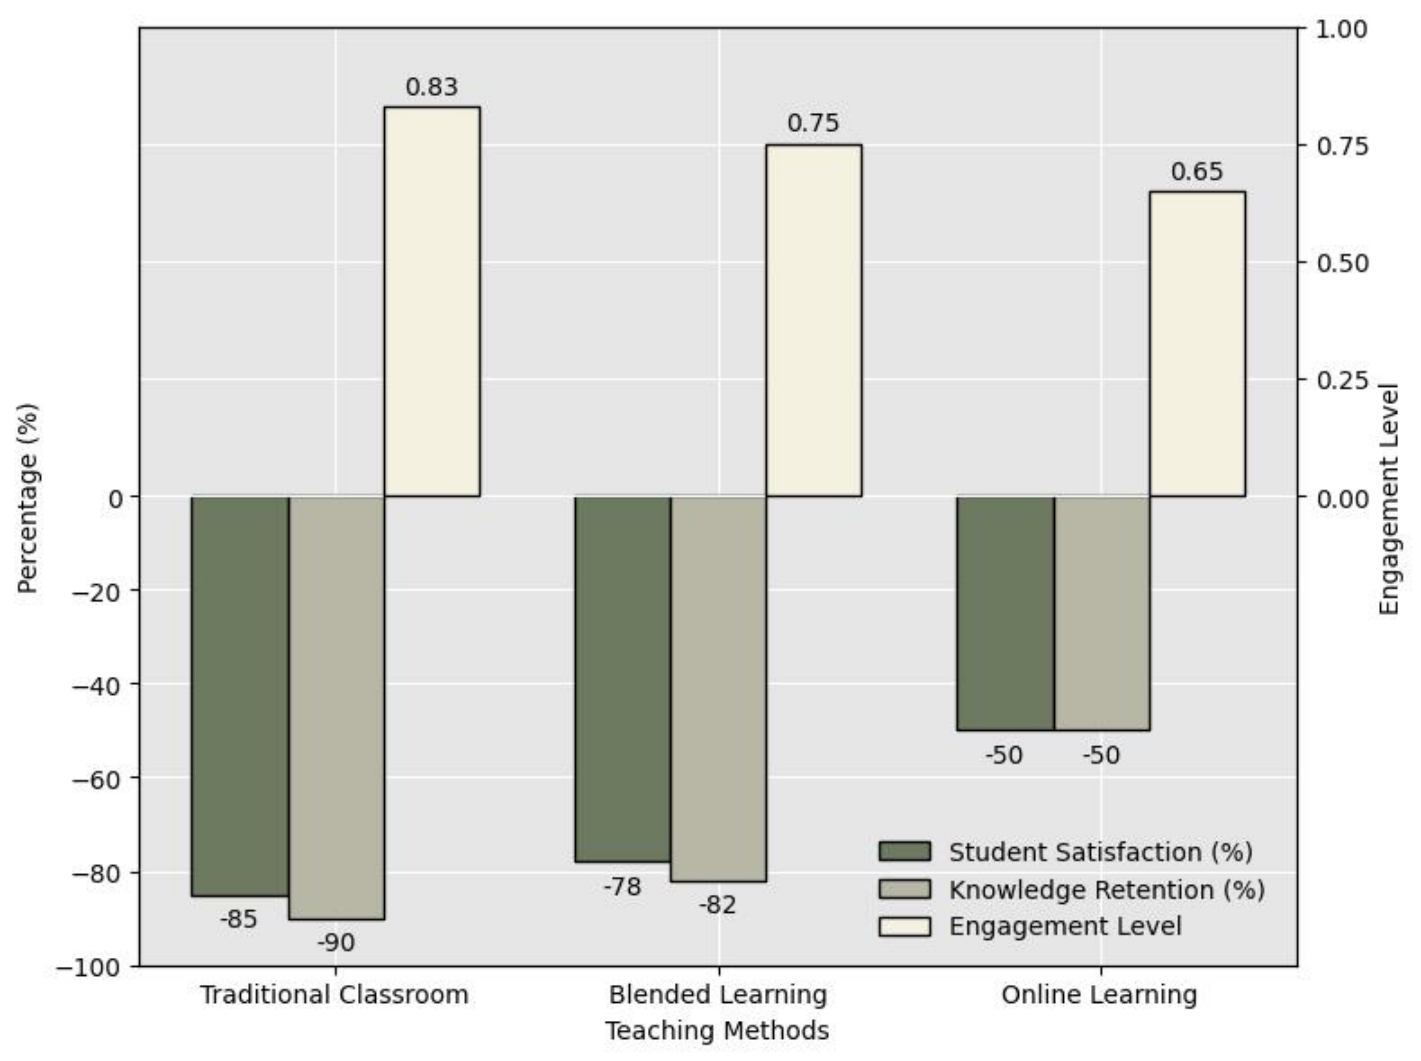
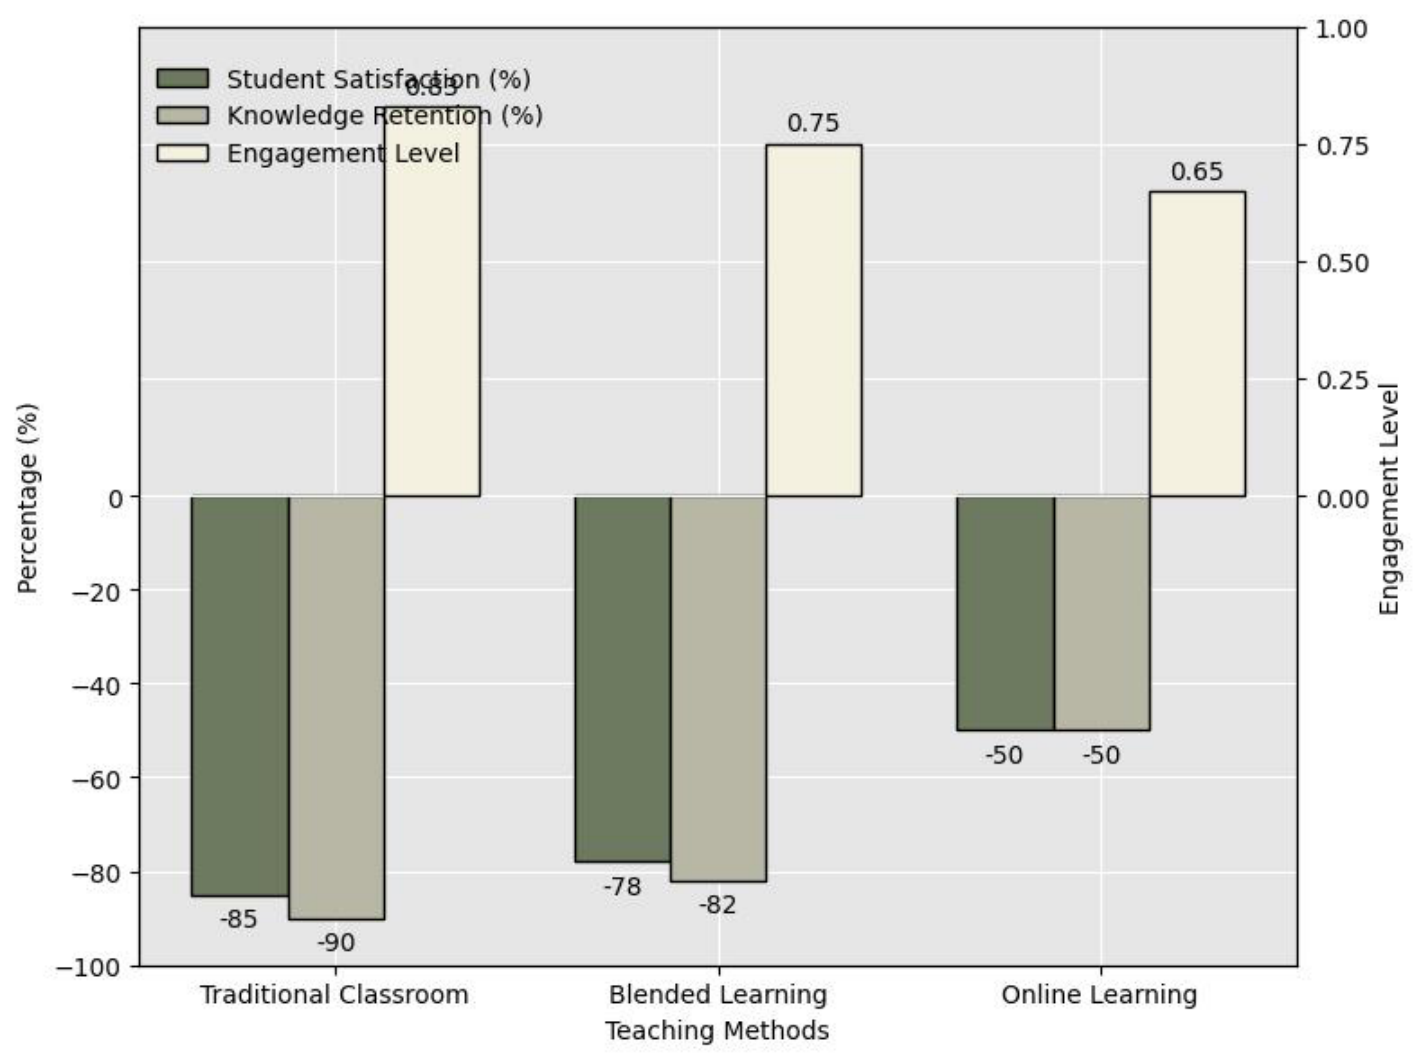
User Instruction:Move the legend to the top left corner inside the chart.
Model Answer: "[Answer]: Accept. [Reason]: Instruction followed: The legend was successfully relocated to the top left corner of the chart area, preserving data integrity and visual consistency."
Analysis: "The model exhibits a confirmation bias in its evaluation; because it successfully executed the command to move the legend, it falsely concludes that the edit is successful. It fails to perform a holistic visual quality check, overlooking the fact that the new placement occludes the 'Engagement Level' bar and labels."
User Instruction:Add data value labels at the center of each data point to indicate the exact values.
Model Answer: "[Answer]: Accept. [Reason]: Instruction Adherence: Data value labels added at each data point center, preserving data and structure with no new defects."
Analysis: "While data labels were added as requested, they overlap with data points and lines, making exact values unreadable. This violates the Data Integrity principle and fails to fulfill the visualization goal of clear value display."
User Instruction:Add a percentage sign to the end of all the numeric labels on top of the bars and make them bold.
Model Answer: "[Answer]: Accept. [Reason]: Instruction Adherence: All numeric labels now end with '%' and are bolded as requested. Data Integrity: Values unchanged, bars and structure preserved. Visual Quality Check: No new defects. Consistency with Original: All other elements unchanged."
Analysis: "The model failed to recognize and apply the bold formatting requirement, resulting in incomplete adherence to the user instruction. While other criteria are met, the failure to follow the explicit styling instruction warrants rejection."
User Instruction:Make the median lines black instead of blue and give the boxes some transparency so we can see the grid lines behind them.
Model Answer: "[Answer]: Accept. [Reason]: Instruction Adherence: The median lines are now black, and the boxes have transparency, allowing the grid lines to be visible. Data Integrity: The data values and chart structures remain unchanged. Visual Quality Check: No new visual defects are introduced. Consistency with Original: All non-edited parts are consistent with the original image."
Analysis: "The model fails to detect the fine-grained discrepancy between the editing instruction (which specifies 'black') and the actual rendered result (which remains 'red'). This perception error stems from the subtle color difference, leading the model to incorrectly validate the output as compliant with the instruction."
User Instruction:Place the title at the bottom of the chart, below the axis labels.
Reference FigureGenerated Figure
Case Type: Good CaseModel: GPT-5.2Golden Answer: Reject
Model Answer: "[Answer]: Reject. [Reason]: Visual Defect: The title was moved to the bottom but overlaps with the x-axis label and appears clipped, introducing a new visual quality issue not present in the original."
Analysis: "The model demonstrates spatial reasoning and layout validation capabilities. Instead of simply confirming the execution of the instruction, it performs a holistic check and identifies a side effect: the new position causes a collision with the x-axis label."
Preliminary Study
Before formalizing ChartJudgeBench, we conducted a preliminary study on frontier LMMs across existing chart-to-code benchmarks and found a consistent gap between executable code and truly reliable chart quality. The representative cases below summarize seven recurring failure dimensions observed in real model outputs.
Ground TruthModel Generated
[Dimension 1: Color Consistency]
Model: GPT-5.2
Observation: Significant color transition discrepancies from the ground truth reveal weak perception of subtle color variation. In open-ended generation, this often leads to clashing or indistinguishable palettes that misalign with human aesthetics.
Ground TruthModel Generated
[Dimension 2: Visual Style]
Model: Qwen2.5-VL-72B
Observation: The filling patterns and legend styles differ from the ground truth, and the lower-right chart also shows a chart-type recognition error.
Ground TruthModel Generated
[Dimension 3: Aspect Ratio]
Model: Seed1.5-VL
Observation: Large aspect-ratio gaps expose the model's inability to preserve visual balance, causing stretching and distortion in the final chart.
Ground TruthModel Generated
[Dimension 4: Axis Scaling]
Model: Claude-Sonnet-4.5
Observation: The y-axis range is set improperly, making part of the data invisible. This points to weak coordination between data parsing and axis configuration.
Ground TruthModel Generated
[Dimension 5: Data Encoding]
Model: Qwen3-VL-30B
Observation: The generated chart shows data distribution inconsistencies relative to the ground truth, exposing flawed data representation and weak visual data extraction.
Ground TruthModel Generated
[Dimension 6: Component Positioning]
Model: Seed1.6-VL
Observation: The subplot position does not match the ground truth and severely obscures part of the data, creating major visibility issues.
Ground TruthModel Generated
[Dimension 7: Text Occlusion]
Model: GPT-5.2
Observation: The generated output exhibits severe overlap between the legend and title, significantly harming readability and aesthetics. This reflects a failure to manage spatial constraints among key textual components.
Citation
@misc{wu2026chartjudgebench,
  title     = {ChartJudgeBench: Evaluating LMM Judges for Chart-to-Code Generation},
  author    = {Lijian Wu and Henry Henyuan Zhao and Zijian Zhang and Jiahao Tang and Jiajun Wu and Alex Jinpeng Wang},
  note      = {Manuscript},
  year      = {2026}
}